rmlint lists five kinds of lint, and only two of them are duplicates
Extremely fast tool to remove duplicates and other lint from your filesystem
At a glance
- What is it?
- sahib/rmlint is a GPL licensed C tool that finds filesystem waste and offers to remove it, built with a make-like build system and written for a documentation builder rather than for a forge. It is careful about the danger of its own output, which is why it ships a paranoia mode and refuses to be interactive.
- Who is it for?
- rmlint fits someone moving a large filesystem who wants to know what is actually taking space before deleting anything, and the format list plus the caching and replay behaviour mean you can scan once and decide later. Check four things.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
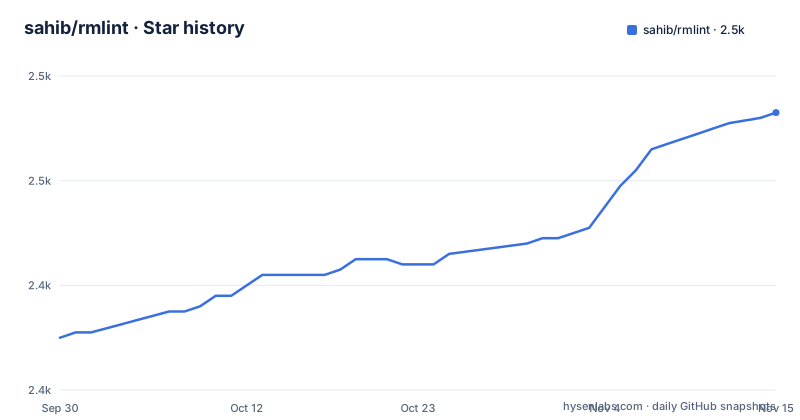
- sahib/rmlint2,473 ★ · +43
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| sahib/rmlint | 2.4k | 2.5k |
43 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two of the five things it finds are duplicates
The features section opens with a one-word verb and five bullets, and the framing is deliberate. It finds duplicate files and duplicate directories, which is what the project's name and its badge both suggest. It finds non-stripped binaries, meaning executables still carrying debug symbols, which is a size problem with a specific fix. It finds broken symbolic links, which is a correctness problem with no size benefit at all. It finds empty files and directories. And it finds files whose user ID or group ID, or both, no longer resolves to a real account on the machine. That last one is the interesting category: it is not about space, it is about a filesystem restored from somewhere else, where every file it owns belongs to a user identifier that does not exist on the current system, and the fix has nothing to do with deleting anything.
A checksum is not proof, so there is a mode that refuses to trust one
The differences list has one entry that is a safety property rather than a feature. Paranoia mode is described as being for people who do not trust hash sums. The implication is that the default duplicate detection compares checksums, and that a checksum match is treated as equality, which is the standard shortcut and is wrong with any non-negligible probability across enough files. So the tool ships a second, slower verification path for anyone who does not accept the shortcut. Two other entries in that list are also about not surprising the user. It has no interactivity, which is listed as a difference rather than a gap: it will not prompt, will not confirm, and will not show progress interactively. And it can restrict the search to files newer than a given modification time, which is the simplest way to keep a scan from touching a long-lived build tree.
The readme is written for a documentation builder, not for a forge
The front page is reStructuredText, and it shows. Before you reach a single sentence of prose there are roughly forty lines of image directives, each with an alignment option and usually a target, one of which is a raw HTML block containing a line break, plus badges for the release, the commit activity, open issues, pull requests, the licence, four continuous integration workflows, and the documentation host. Every one of those lines renders as literal syntax on a forge's Markdown renderer. That is not carelessness so much as a priority: the project has a full documentation site with a tutorial, an online manpage, a developer guide, and a bugs section, and the readme is a pointer into that site rather than the product. The manpage is also treated as the primary reference, to the point that the bug section tells you to read both the developer guide and the manpage's bugs section before reporting anything.
Two releases share a codename and the newest tag is a candidate
The release list has three entries and the naming convention is worth noting because it is a consistent one: every release carries a codename that is two words starting with the same letter, one of them an adjective. The two patch releases both carry the same codename, which means the codename is per branch rather than per build. Then the cadence. A patch release in August 2023, its successor nineteen months later in March 2025, and then an eighteen month gap to a release candidate in September 2026 for the next minor version. So the newest tag is a candidate, there is no final release for that line, and the badge the project displays is configured to include prereleases, which means the version a reader sees on the front page may be the candidate rather than anything they can rely on. The last commit to the tree is dated 2026-10-01, so work continues past that candidate.
The build system is a Python-flavoured one, not a makefile
There is no makefile in the repository root. There is a script named for the construction tool, a version file, a helper directory for it, a clang formatting script, a clang configuration, a clangd configuration, and a set of templates used by the documentation build. So the build is driven by a Python construction tool that reads its own configuration and templates, and the formatters are configured separately from the build, with a script to run the formatter and a configuration that both a linter and an editor read. The version is also a file rather than a constant in a header, which means it is read at build time and stamped into the binary, and the repository has an archival substitution file for distributions that build from a tarball rather than a checkout. That last detail is the kind of thing that only matters if you are a packager, which is also who the repology badge at the bottom of the readme is for.
Caching and replaying is what makes a scan safe to run twice
Two entries in the differences list are about workflow rather than detection, and they are the reason this tool is usable on a filesystem large enough to be frightening. Caching means a scan's results can be kept, so you do not re-hash the same terabyte tomorrow to produce the same answer. Replaying means the decision half is separable from the scan half: you scan, you look, you decide, and then you act on a stored result. Combined with the long list of output formats and the long list of ways to handle duplicates, that is a project designed around the assumption that you will not agree with it on the first pass. The one thing it will not do is let you change your mind interactively, because there is no prompt at all. That is a deliberate trade and it is the one most likely to surprise someone who has only used duplicate finders that show a progress bar and ask before they act. The release notes also mention support for a copy-on-write filesystem, which matters for the same reason: a scan that hard links or copies on such a filesystem behaves differently from one that deletes in place.
The tree carries a translation catalogue, a test configuration in Python, and four maintainers
The repository layout tells you what kind of project this is. There is a source tree and a separate library tree, a documentation tree, a continuous integration tree, a directory of templates used by the build, a graphical interface tree, and a directory of translation catalogues, which means the tool's interface strings are translatable. There is a Containerfile rather than a Dockerfile, a mailmap file that consolidates contributor identities for the changelog, and a changelog at the root. Testing is configured in a Python test-runner file even though the tool is C, which is what you would expect from a project that drives its own test harness from a construction tool. And the authorship table is the most interesting file of all, because it lists four people with the years they were involved: the original author from 2010 to 2017, a second from 2014 to 2021, a third from 2021 to 2023, and a fourth from 2025 onward. A fifteen year old tool that has changed hands twice and still ships weekly commits is a stronger argument than the speed claim in the readme.
Editorial conclusion
rmlint fits someone moving a large filesystem who wants to know what is actually taking space before deleting anything, and the format list plus the caching and replay behaviour mean you can scan once and decide later. Check four things. What you are about to delete, because the tool finds five categories and only two are duplicates, and it will also point at files whose owner no longer exists in your system's user database, which on a restored backup can be every file. How duplicates are verified, because the default is by checksum and the paranoia mode exists because a checksum is not proof. That you read the output before acting, since it reports rather than deletes and there is deliberately no interactive mode. And which platform you are on, because Linux is the target and the other systems are best effort.
Frequently asked questions
What kinds of problems does rmlint find?
Five: duplicate files, duplicate directories, non-stripped binaries carrying debug symbols, broken symbolic links, empty files and directories, and files whose user or group identifier no longer resolves to a real account. Only the first two are about duplicates.
How does rmlint verify that two files are duplicates?
By default it compares checksums, and the project ships a paranoia mode described as being for people who do not trust hash sums, which is a slower verification path for anyone who will not accept a checksum match as proof of equality.
Does rmlint delete files as it scans?
No. It finds problems and offers to remove them, and it has no interactivity at all, which the project lists as a design difference rather than a missing feature. It also supports caching and replaying so a scan can be reviewed and decided on before anything is acted upon.
Which platforms does rmlint support?
It runs and compiles under most Unix-like systems including Linux, FreeBSD, Darwin, and Solaris. The main target is Linux, and the project states that some optimisations may not be available elsewhere. Continuous integration runs on Linux, FreeBSD, macOS, and Cygwin.
How do I get rmlint?
It is packaged in most distributions already. Otherwise the project points you at compiling from source, with the details in its installation guide on the documentation site. The full documentation, tutorial, online manpage, and developer guide are all hosted at the same address.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sahib-rmlint)Star history chart for your README
[](https://hysenlabs.com/projects/sahib-rmlint)Was this useful?