xLAM ships a framework whose setup.py installs something called actionstudio
xLAM: A Family of Large Action Models to Empower AI Agent Systems
At a glance
- What is it?
- The xLAM repository holds the Salesforce Large Action Models, the ActionStudio training framework, and the APIGen-MT data work, behind a root setup.py that installs no dependencies at all. Its newest news entry is dated August 2025, and it has no releases.
- Who is it for?
- xLAM is a reasonable place to start if you want the model family, the training framework, and the data papers in one place under an Apache 2.0 licence. It is not a package you can pip install and run: setup.py installs a differently named project with no declared dependencies, and a note states that the underlying data is only partially released.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 166 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
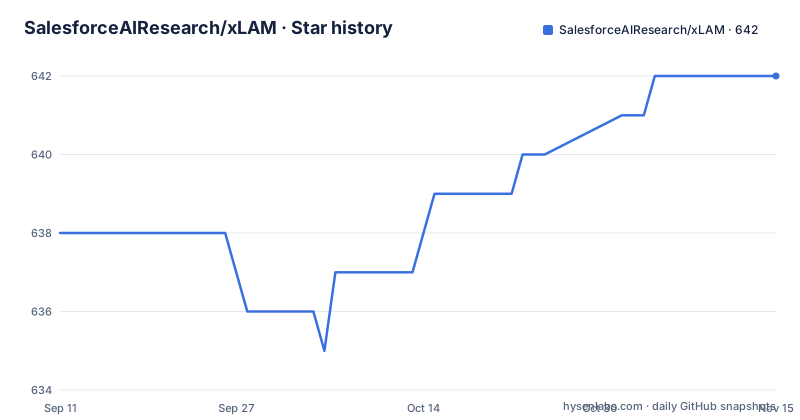
- SalesforceAIResearch/xLAM642 ★ · +4
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| SalesforceAIResearch/xLAM | 638 | 642 |
4 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The packaging file installs a different project than the repository name
The clearest statement about what this repository installs is in setup.py, and it is not xLAM. The package name is actionstudio, the version string is v2.0, the author line credits the xLAM team with Jianguo Zhang, Thai Hoang, Ming Zhu, and Zuxin Liu among others, and the description calls it a lightweight framework for agentic data and training of large action models. Underneath that, install_requires is set to requirements, and requirements is None, because the two lines that would have read requirements.txt into that variable are commented out. A pip install of this project therefore declares no dependencies at all, while the 21 lines that do matter sit one file away. The tree also holds both an actionstudio/ directory and a separate ActionStudio_README.md, so the model work and the framework work share one root.
requirements.txt pins ray twice, in two incompatible styles
requirements.txt is where the dependency story actually lives, and its shape is inconsistent in a way that matters. Most entries are hard pins: datasets 2.18.0, trl 0.8.6, tokenizers 0.21.0, accelerate 1.4.0, peft 0.14.0, bitsandbytes 0.45.5, wandb 0.17.4, tiktoken 0.7.0, joblib 1.3.2. Three float instead, with a lower bound and no ceiling: transformers at 4.55.0 or newer, deepspeed at 0.14.4 or newer, and openai at 1.66.2 or newer. Ray appears twice in two different styles, once as ray==2.30.0 in the middle of the list and again as the final line ray[data,train,tune,serve], which carries no version at all. packaging is held at 24.0 and wikipedia at 1.4.0, the only entry that suggests training data being pulled from somewhere outside the repositories themselves.
The research-only note explains why the data is partial
One note above the introduction sets the terms for everything else. The repository is provided for research purposes only, and any data related to xLAM is partially released due to internal regulations, stated as being done to support the advancement of the agent research community. That sentence explains the gap between what the readme advertises and what a download actually yields: the models, the papers, and the leaderboard placements are open, while the trajectories behind them are not complete. It also frames the pipeline described just below it, where xLAM collects agent trajectories from distinct environments, standardizes them into a single format, builds a generic data loader on top, and keeps the training pipeline balanced across sources while preserving independent randomness across devices during dataset partitioning and training.
The news list stops at August 2025 while commits run to June 2026
The readme keeps a dated news list at the top, and the dates tell their own story. It runs from an initial AgentOhana and xLAM paper release in February 2024, through the first two function-calling models in July 2024, the full family in August 2024, a tokenizer example notebook in November 2024, then ActionStudio and APIGen-MT going open source on 15 April 2025, NAACL 2025 slides and the APIGen-MT-5k dataset in May 2025, an ActionStudio update on 5 August 2025, and an EMNLP 2025 acceptance note on 20 August 2025. Nothing in that list is newer. The last push to the repository is dated 2 June 2026, and the repository has no GitHub releases at all, so there is no tag line to line the news entries up against.
Only the 8b model has a GGUF download in the table
The model table is small and its columns do not agree with each other. Llama-xLAM-2-70b-fc-r is listed at 70B parameters and 128k context, released 26 March 2025, with NA in the GGUF column. Llama-xLAM-2-8b-fc-r is 8B and 128k on the same date, and it is the only row with a quantized download linked. The 32B entry is listed at 32k context with a parenthetical maximum of 128k and an asterisk marker, whose note is not visible alongside the table. So local quantized inference is offered at one size only, and the context lengths cannot be compared across rows without reading past the numbers. All three rows share one release date and one category, multi-turn conversation and function calling.
Every leaderboard claim is stamped with a month
Each performance claim in the readme carries a date and a model name, which makes them checkable and also dates them. In July 2024, xLAM-1b-fc-r and xLAM-7b-fc-r were placed third and twenty-fifth on the Berkeley Function-Calling Leaderboard, described as outperforming many significantly larger models. In August 2024 the full family was placed first and sixth on the same board. On 15 April 2025, xLAM-2-fc-r was reported at top-1 performance on the latest BFCL leaderboard. Those are three different model generations measured at three different moments, so the placements describe snapshots rather than a standing position, and anyone reading them now is reading numbers that were current when each was recorded.
Three deliverables share one root directory
The directory names are the quickest way to tell three deliverables apart. The xLAM/ directory holds the model and training side described in the introduction, the aggregation pipeline and the data loader. The actionstudio/ directory plus ActionStudio_README.md hold the framework, which the news list records as open-sourced in April 2025, updated in August 2025, and accepted at the EMNLP 2025 main conference. The data work sits in papers and Hugging Face datasets rather than in a folder: APIGen, APIGen-MT, xlam-function-calling-60k, and the compact APIGen-MT-5k. Around them sit the administrative files an Apache 2.0 project needs, including AI_ETHICS.md, CODEOWNERS, SECURITY.md, license_info.md, and a requirements.sh sitting beside requirements.txt.
Editorial conclusion
xLAM is a reasonable place to start if you want the model family, the training framework, and the data papers in one place under an Apache 2.0 licence. It is not a package you can pip install and run: setup.py installs a differently named project with no declared dependencies, and a note states that the underlying data is only partially released. Before building on it, read the partial-release note to see which artifacts you can actually obtain, and install from requirements.txt yourself rather than trusting install_requires.
Frequently asked questions
What is Salesforce xLAM?
xLAM is a family of Large Action Models from Salesforce AI Research, aimed at function calling and multi-turn conversation. The xLAM-2-fc-r generation is published at 8B, 32B, and 70B, with the largest entry named Llama-xLAM-2-70b-fc-r.
How do I install the xLAM training framework?
The setup.py at the repository root declares the package name actionstudio at version v2.0 and leaves install_requires empty, because the lines that read requirements.txt are commented out. The 21 dependency lines sit in requirements.txt and have to be installed separately.
Are xLAM models available in GGUF format?
Only one of the listed models has a GGUF download, Llama-xLAM-2-8b-fc-r. The 70B entry shows NA in that column, and the 32B row lists 32k context with a parenthetical maximum of 128k.
Does Salesforce release all the xLAM training data?
No. A note in the readme states that the repository is provided for research purposes only and that xLAM data is partially released due to internal regulations.
How current is the xLAM repository?
The last push is dated 2 June 2026, the newest entry in the readme's news list is dated 20 August 2025, and the repository has no GitHub releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/salesforceairesearch-xlam)Star history chart for your README
[](https://hysenlabs.com/projects/salesforceairesearch-xlam)Was this useful?