Gorilla's six sub-projects and the APIBench dataset
Gorilla: Training and Evaluating LLMs for Function Calls (Tool Calls)
At a glance
- What is it?
- The repository behind Gorilla has grown well past the 2023 function-calling model into APIBench, OpenFunctions-V2, the Berkeley Function Calling Leaderboard, GoEx, RAFT and Agent Arena. Choosing a sub-directory is your first real decision.
- Who is it for?
- Take the dataset and evaluation code from APIBench and the paper-era scoring harness if you are reproducing function-calling numbers, and treat OpenFunctions-V2 as the surface to evaluate rather than adopt blind, since its serving details are not in the README's project table. Leave GoEx out of any path where an action cannot be undone, because its validation runs after execution.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 28 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
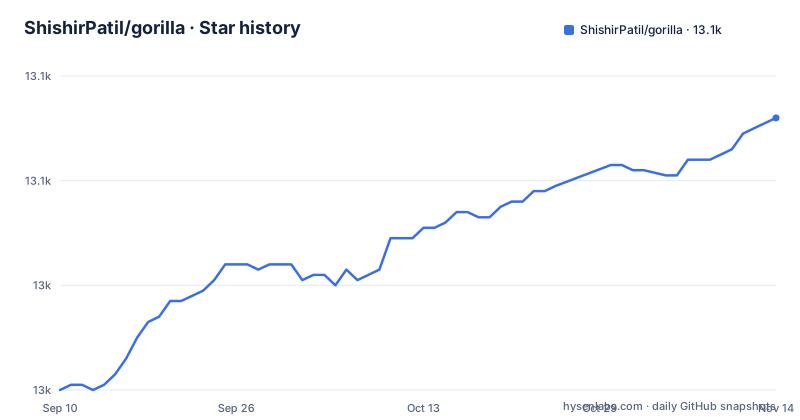
- ShishirPatil/gorilla13,072 ★ · +52
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| ShishirPatil/gorilla | 13k | 13.1k |
52 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Gorilla is six projects sharing one repository root
The tree shows how far the scope has moved: agent-arena/, berkeley-function-call-leaderboard/, data/, goex/, gorilla/, openfunctions/ and raft/, alongside a .devcontainer/ directory. The repository description still reads Training and Evaluating LLMs for Function Calls (Tool Calls), which fits the original paper and little of what arrived after it.
Closing that gap is your first real decision. gorilla/ holds the inference and evaluation code, with the chat interface documented at the inference README path. data/ is APIBench. goex/ is an execution runtime for model-generated actions, released in April 2024. raft/ adapts a model to domain-specific retrieval. agent-arena/ arrived in October 2024 to rank agents on search, finance and RAG tasks. Nothing states which of these you need for the problem in front of you, and the project table in the README describes capabilities rather than dependency order.
APIBench and the paper evaluation code shipped on the same day
The origin point is May 2023, when APIBench was released together with the evaluation code used in the paper. The dataset is described as the largest collection of APIs, curated so it can be trained on, and the paper's evaluation runs against more than 1,600 API calls. Both the dataset and the scorer live here, which matters if you want to reproduce a number instead of trusting a table on a website.
Two training ideas attach to that original work. One is a finetuning approach aimed at API invocation, where the model has to produce both the semantically correct API and syntactically correct arguments from a natural language query. The other is retrieval-augmented training for test-time adaptation.
No install command exists; the entry points are a Colab notebook and model hubs
The README's update feed points to hosted entry points rather than an install command. The first model arrived on 2023-05-27 and was reached through a hosted Colab notebook or the HuggingFace weights gorilla-7b-hf-delta-v0 under the gorilla-llm organisation. One day later came Torch Hub and TensorFlow Hub models, and two days after that a command line interface documented at the inference README path.
So the practical first run is: pick the surface you already have, load weights from one of those three places, and read the inference README for the chat interface. Apache-2.0 covers the models, made commercially usable on 2023-06-06, but a licence that permissive says nothing about which revision your weights came from. Record the commit and the hub revision yourself.
OpenFunctions-V2 is the surface built around parallel calls
OpenFunctions-V2 is positioned as a drop-in alternative for function calling, and its distinguishing feature is parallelism. The listed capabilities are multiple and parallel function execution behind OpenAI-compatible endpoints, native support for Python, Java, JavaScript and REST APIs with expanded data types, function relevance detection to reduce hallucinations, and improved RESTful API formatting. That set targets the case where one request needs several tools at once rather than one tool per turn.
The gaps sit in the plumbing. The README's project table gives no endpoint URL, request schema or model version, and drop-in is the project's own wording. The original checkpoint is a 7b variant. Anyone wiring OpenFunctions-V2 into an existing client should look for serving details in openfunctions/.
The newest release tag and the newest benchmark share one date
Three tagged releases exist: v1.1 on 2024-08-27, v1.2 on 2025-01-05 and v1.3 on 2025-07-17, each titled as a Berkeley Function Calling Leaderboard update. The benchmark underneath moved repeatedly. BFCL went live in February 2024, added cost and latency metrics on 2024-04-01, then V2 in August 2024 with enterprise-contributed data and real-world scenarios, V3 in September 2024 with a state-based evaluation system for multi-turn and multi-step calling, and V4 Agentic on 2025-07-17 covering web search with multi-hop reasoning and error recovery, agent memory management, and format sensitivity.
The consequence for anyone citing a score: a BFCL number without its version says very little. A model measured on early single-turn accuracy and one measured under V4 with memory and format sensitivity are being scored on different tasks, and V3's state-based scoring adds a dimension neither earlier version had. Record the version next to the number or you cannot compare it to anything, including to your own previous run.
GoEx validates after the action has already run
GoEx, released on 2024-04-12, is the one component that confronts side effects. It runs LLM-generated actions such as code and API calls, then applies post-facto validation to assess the action after execution, alongside undo and damage confinement abstractions for handling unintended effects. The stated intent is autonomous agents with a human out of the loop.
Read post-facto literally. Validation arrives once the action has run, and undo is offered as an abstraction rather than a transaction, so the guarantee is bounded by whatever the runtime can model and roll back. No atomicity, isolation or recovery guarantee is claimed for arbitrary side effects such as a payment or a deletion outside the systems GoEx wraps. If you are weighing it as a safety layer, that ordering is the first thing to check, and the paper at arxiv.org/abs/2404.06921 plus the code under goex/ are where to find out what damage confinement actually covers.
RAFT and Agent Arena pull the evaluation story in two directions
Two later announcements widened the remit. RAFT went live in March 2024 for adapting a language model to domain-specific retrieval, announced through a Microsoft and Meta blog alongside the Berkeley one, and it lives in raft/ rather than under the Gorilla paper directory. Agent Arena followed on 2024-10-04, from Gorilla X alongside the LMSYS Chatbot Arena, to compare agents on search, finance and RAG tasks through its own ranking system and a community-driven prompt hub.
For a reader picking a harness, this splits evaluation in two. BFCL scores function and tool calling; Agent Arena scores agents on end-to-end tasks. No page tells you which one answers the question you have, and a prompt hub that is community-driven means the inputs other agents were scored on can change without a release. Decide which axis your decision depends on before running anything, because a benchmark you did not choose on purpose still produces a number you will be tempted to quote.
The last commit and the last release are eight months apart
The last push to the repository was on 2026-10-17. The newest GitHub release is v1.3, dated 2025-07-17, and the most recent line in the README update feed is the BFCL V4 Agentic announcement from that same day. Two different dates, about fifteen months apart, with nothing in the update feed explaining what changed in between.
The changelog link does not close the gap. It points into berkeley-function-call-leaderboard/, and the sentence introducing it ends with an empty date field, so the version stamp the README meant to publish was never filled in. Commits are still landing on main, so the code is not frozen, but the release and announcement trail stopped in mid-2025. Check the commit log for the specific sub-directory you plan to depend on rather than trusting the tag list.
Editorial conclusion
Take the dataset and evaluation code from APIBench and the paper-era scoring harness if you are reproducing function-calling numbers, and treat OpenFunctions-V2 as the surface to evaluate rather than adopt blind, since its serving details are not in the README's project table. Leave GoEx out of any path where an action cannot be undone, because its validation runs after execution. Before depending on anything, check the commit log for the specific sub-directory you need, since the newest release tag is v1.3 from 2025-07-17 and the last push is dated 2026-10-17.
Frequently asked questions
What does the Gorilla repository actually contain?
It has grown well past the original function-calling model. The root holds data/ for APIBench, openfunctions/ for OpenFunctions-V2, berkeley-function-call-leaderboard/ for BFCL, goex/ for the execution runtime, raft/ for domain-specific retrieval adaptation and agent-arena/ for agent comparison, while the description still mentions only training and evaluating LLMs for function calls.
How do I run a Gorilla model?
The first weights were reached through a hosted Colab notebook or the gorilla-llm HuggingFace organisation, were later distributed through Torch Hub and TensorFlow Hub, and a chat interface is documented at the inference README path.
What is the Berkeley Function Calling Leaderboard used for?
It ranks models on function and tool calling, and its shape has changed several times. BFCL V2 added enterprise-contributed data, V3 added state-based evaluation for multi-turn and multi-step calling, and V4 Agentic added web search with multi-hop reasoning, agent memory management and format sensitivity, while cost and latency metrics arrived on 2024-04-01.
Can I use Gorilla models commercially?
The models were announced as commercially usable under Apache 2.0 on 2023-06-06. The repository itself carries an Apache-2.0 licence.
Is OpenFunctions-V2 safe to point at an OpenAI-compatible client?
The project describes OpenAI-compatible endpoints with multiple and parallel function execution and native support for Python, Java, JavaScript and REST APIs. The README's project table gives no endpoint URL, request schema or model version, so check openfunctions/ before relying on the interface.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shishirpatil-gorilla)Star history chart for your README
[](https://hysenlabs.com/projects/shishirpatil-gorilla)Was this useful?