The scalameta README is a pointer file, and the top level is where the project actually lives
Library to read, analyze, transform and generate Scala programs. Tutorial If you'd like to find out how to use scalameta, see this tutorial.
At a glance
- What is it?
- A Scala library for reading, analysing, transforming and generating Scala programs, with seven named maintainers and no usage text at all. Everything a reader needs to know is in the repository layout: an agent instruction file per assistant, three release documents, and modules for SemanticDB and Scala 3.
- Who is it for?
- This is a mature library with a deliberately empty project file, so judge it on the repository rather than on the readme. Two things tell you how it is run.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
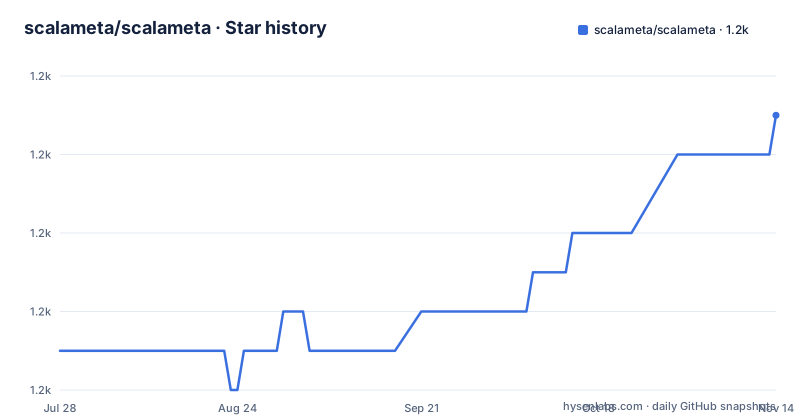
- scalameta/scalameta1,161 ★ · +6
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| scalameta/scalameta | 1.2k | 1.2k |
6 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Seven names, two links, and no usage text
The project file is short enough to read in one go, and everything in it is a pointer or a name.
There is a build status badge. There is a line telling the reader to head over to the user documentation to learn about the project and its roadmap, and a separate line pointing at a tutorial for how to use it. Then there is a team section, which lists seven people as the current maintainers, described as the people who can merge pull requests, each with a name and a GitHub handle.
Seven merge permissions is a small number for a library of this age and visibility, and the file makes it explicit rather than leaving you to infer it from the commit log. It also links to the contributors graph, which is the standard way to see everyone else who has contributed since.
What is not in the file is as notable as what is. There is no installation line, no dependency coordinate, no minimum Scala version, no example, and no statement of what changed in the current release. The project's own description, in the repository metadata, is the only statement of scope: a library to read, analyze, transform and generate Scala programs.
So the entire onboarding path is one hop out of the repository, to the project site, and then to a tutorial. For a library that most people meet because another tool already depends on it, that is a defensible division of labour. For anyone choosing between libraries, it is not.
Three agent instruction files and a blame ignore list
The top level tells you how the project expects to be worked on.
There are three assistant instruction files: one for a general agent convention, one for Claude, and one for Gemini. Committing all three means the repository carries machine-readable instructions for coding assistants as a first-class artifact, which is increasingly normal and still worth noticing.
Next to them is a file that tells git to ignore certain revisions when attributing blame, which is the standard accompaniment to a repository-wide reformat. Once a formatter touches every line, blame becomes unreadable unless those commits are excluded. The presence of that file is evidence that the project runs a formatter over the whole tree, and the configuration file for that formatter sits at the root too, alongside a Java version pin, JVM options, and a configuration file for an automated Scala version updater.
Those four small files are the project's toolchain stated as data rather than as prose: which Java, which JVM flags, which formatter, and who bumps the Scala version.
The licence is a file rather than a label, with a notice file beside it, which is the usual arrangement when third-party code is bundled and needs attribution.
Three documents describe how a release happens
Versioning, releasing and contributing each have a document of their own at the root, and a changelog directory sits alongside them.
Three separate documents is more than most projects of this size carry. Combining them would be the obvious economy, so their existence says the project treats each as a separate audience: one for the version scheme, one for the mechanics of cutting a release, one for contributors. That is a repository where the people doing the work are not always the people writing the code.
The tags are consistent with that. Recent releases are 4.17.2 on 2026-07-09, 4.17.3 on 2026-07-24 and 4.17.4 on 2026-09-11: a stable four-series with patch releases roughly monthly, no pre-release tags visible, and no sign of a second supported line in the recent history.
The last commit to the repository is dated 2026-09-23, twelve days after the newest tag, which is the ordinary shape of a library that is still being worked on: work lands on the branch, and the tag follows when there is a reason.
The changelog directory being a directory rather than a single file means entries are probably added per release, which is what makes a release document and a versioning document worth having.
SemanticDB is implemented here, not just consumed
Two directories at the top level are a semantic database implementation and a matching test suite for it.
That is a larger claim than it first looks. A semantic database for Scala is a specification about how tools exchange information about source code, and it has its own ecosystem: analysis tools that write it, editors and language servers that read it, and a spec that has to keep matching compiler output. Building it inside the library repository means this project is both a consumer of the idea and an implementer of it.
The practical reason a library that parses and transforms Scala code would want to emit structured semantic information is that it is exactly the layer that knows what the code means rather than what it says. A parser sees a tree; a semantic database describes the tree with resolved names and types attached.
So the pair of directories is not a stray experiment. It is the point where this project crosses from text manipulation into tool infrastructure, and it is also the reason the repository carries a separate test suite for that component alone rather than folding those tests into the main one.
Nothing in the visible project file mentions it. A reader who installs the library for parsing would not find out from the readme that there is a semantic database in the same repository.
Scala 3 support lives in a module named tree lifts
One directory name tells you how this project handles the language transition: scala3-tree-lifts.
A tree lift is a conversion between two representations of the same code. Scala 3 changed the syntax tree that a compiler sees, so a library built around the Scala 2 tree needs a way to move between the old shapes and the new ones, and doing that conversion explicitly is what the directory name describes.
The important consequence is architectural. If cross-version support is a separate module rather than a set of conditionals inside the parser, then the language-version question is isolated: the core library keeps one representation, and the lift layer translates. That is a harder design to write and an easier one to maintain, and it is also the design that lets a library support two major language versions without doubling its test matrix.
The tree is consistent with that reading. Alongside the main library module there is a directory for the lifts, a directory for the semantic database with its own tests, a directory for community tests, plus separate test and benchmark directories and a bin directory for scripts.
So a repository that looks like one library from the outside is really several modules with distinct reasons to change, and the directory names are the only map of that structure because the project file does not draw one.
community-test/ is a module for testing against other people's code
One more module name deserves reading closely, because it describes a testing strategy rather than a feature.
A community test suite in a library repository usually means the library is compiled against, or its behaviour checked against, projects it does not own. That is a different discipline from unit tests: instead of asserting that a function returns a token sequence, you take somebody's real project and assert that your change does not break it.
For a library whose job is reading and transforming other people's source code, that is the only test that really matters. Parsers break on inputs the author never imagined, and transform libraries break on code shapes that no unit test covers. A module of community tests is the project admitting that and paying for it in build time.
The same reasoning explains the separate benchmark directory. A tool that runs over a whole codebase has performance characteristics that users feel, and the repository carries the machinery to measure them rather than leaving the question to the issue tracker.
The two directories sit next to the ordinary test directory, so the layout distinguishes three kinds of checking: its own tests, other people's code, and how fast it is. Few libraries of this kind make the third distinction visible.
The build is sbt, the website has its own directory, and npm has a readme
The remaining top-level entries explain how the project is built and where its output goes.
The build is sbt, with a build file at the root and a project directory holding its configuration. That is the conventional Scala build, and it is worth naming because it is the one decision in the repository that constrains every contributor: you cannot build this without an sbt toolchain, and the Java version pin plus JVM options at the root are what make that reproducible.
Then there is the web presence. A website directory sits at the root, alongside a docs directory and a directory called notes. The project file points readers at the documentation site, so the site is presumably built from one of those, and the notes directory suggests design discussion kept in the repository rather than in an issue tracker.
And there is an npm-flavored readme, sitting next to the main one. That is a distribution surface, which means this library is consumed from Node as well as from the JVM, and it means the two audiences get different entry documentation.
Put together, the top level describes a project that builds with sbt, publishes for at least two ecosystems, keeps its design notes and its website in version control, and treats its release process and its assistant instructions as source.
Editorial conclusion
This is a mature library with a deliberately empty project file, so judge it on the repository rather than on the readme. Two things tell you how it is run. The presence of versioning, releasing and contributing documents plus a changelog directory means the release process is written down and someone maintains it, and the version tags move in the four-series with dates you can check. The three agent instruction files at the root tell you that whoever maintains this expects coding assistants to work in it, which is worth reading before you contribute. Before you depend on it for a specific Scala version, check the compatibility file rather than the readme, since that is where the matrix lives.
Frequently asked questions
What is scalameta?
A Scala library to read, analyze, transform and generate Scala programs, licensed BSD-3-Clause and developed on GitHub with an sbt build. Recent releases are in the four series, with v4.17.4 published on 2026-09-11 and the last commit on 2026-09-23.
How do I learn to use scalameta?
The project file is a pointer: it sends you to the user documentation for the project and its roadmap, and to a tutorial for how to use it. It also names seven maintainers as the people who can merge pull requests, and links to the contributors graph for everyone else.
Does scalameta support Scala 3?
The repository carries a module named scala3-tree-lifts next to the main library module, which is where conversion between Scala 2 and Scala 3 syntax trees lives. A COMPATIBILITY.md at the root is where the support matrix is kept, rather than anything in the readme.
Why does the scalameta repository contain SemanticDB?
Because it implements it. There is a semanticdb module and a matching tests-semanticdb suite at the top level, so the structured semantic information about Scala code is produced here rather than only consumed.
How does scalameta handle releases?
Three documents at the root cover it: VERSIONING.md, RELEASING.md and CONTRIBUTING.md, with changelog entries kept in a changelog directory. The tag history is a stable four-series with roughly monthly patches.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scalameta-scalameta)Star history chart for your README
[](https://hysenlabs.com/projects/scalameta-scalameta)Was this useful?