SchemaStore is a static catalog with one hosted MCP endpoint, and its npm package is private
A collection of JSON schema files including full API. Visual Studio Code Create .vscode/mcp.json in your workspace: Visual Studio Add a .mcp.json file to your solution root: Any MCP Client Point your client at using HTTP transport.
At a glance
- What is it?
- A look at a JSON schema collection: the tooling that validates and formats thousands of independent schemas, the two JSON drafts it has to support at once, the three different config file shapes two IDEs need for the same endpoint, and the fact that the npm manifest is version 1.0.0 and marked private.
- Who is it for?
- SchemaStore is the right dependency if your editor or agent needs a schema for a configuration format nobody wants to hand maintain, and if being a few days behind the upstream format is acceptable. It is the wrong choice if you need a versioned, guaranteed-current schema for a production pipeline, because there are no releases to pin and the last push was on 2026-10-01.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
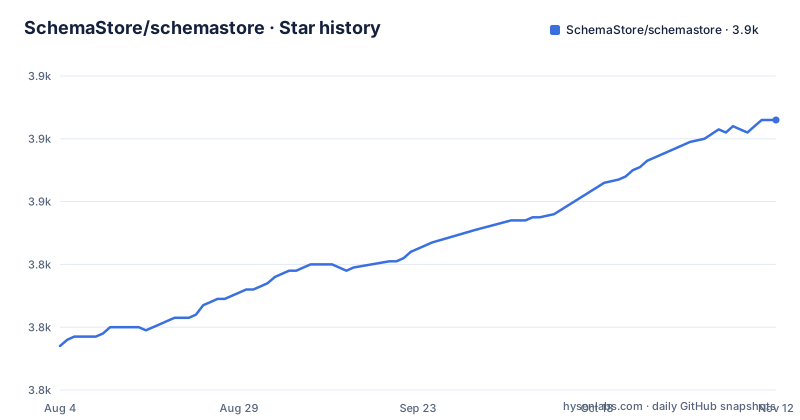
Star history
- SchemaStore/schemastore3,886 ★ · +72
| Repository | 2026-08-04 | 2026-11-12 |
|---|---|---|
| SchemaStore/schemastore | 3.8k | 3.9k |
72 Stars in the last 100 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The npm package is private, so nothing here is installable
The manifest at the root of the repository looks like a published package and is not one. The name is schemastore.org, the version is 1.0.0, and private is set to true, which means npm refuses to publish it and there is nothing to install from a registry.
That resolves an easy confusion. SchemaStore is a website and a repository of files, not a library. You do not add it to a project; you either fetch a schema from it, or you point a tool at its endpoint.
What the manifest does tell you is how the site and its tooling are built. The type field is module, so the code is ES modules. Engines requires node 18 or newer. The repository URL and the bugs URL both point at the capitalised SchemaStore spelling of the project, while the manifest name is the lowercase domain, which is the kind of small inconsistency you hit when you follow a link from the readme to the manifest.
The version 1.0.0 is worth noting for a repository that is not archived and had a push on 2026-10-01. A project that has never moved past 1.0.0 and ships no releases is signalling that its versioning is not the thing to track. The files are the thing.
Two JSON schema drafts have to validate at the same time
The development dependencies include ajv, ajv-formats, ajv-keywords and ajv-draft-04, plus a separate package for draft 2019-09 formats. Two draft implementations sitting side by side is not redundancy; it is the requirement.
A catalog of schemas for popular configuration documents accumulates schemas written in different eras, and those eras used different JSON Schema drafts. A validator that handled only the current draft would reject a large part of the catalog. So the tooling carries a draft-04 validator and a 2019-09 formats package at the same time, which is why you can find a schema for an old configuration file and still have it validate.
The other validators in the list are for a different job. @prantlf/jsonlint is a linter rather than a validator, so it catches syntax problems in the schema files themselves rather than in the documents they describe. @exodus/schemasafe is a second implementation of JSON Schema validation, and jsonc-parser covers configuration files that are JSON with comments, which is the format many editors use for their own settings.
So the toolchain answers a question the readme does not ask: the catalog can be checked by more than one validator, and it can serve files that are not strict JSON.
The gate is pre-commit, and the scripts behind it are narrow
There is a pre-commit configuration file at the top level and a badge pointing at the pre-commit continuous integration results for the master branch. For a repository where most changes are data files, that is the entire review mechanism: the checks have to run before a commit exists rather than after it is proposed.
The npm scripts those checks call are worth reading closely because they are small. Prettier runs in check mode over the whole tree, with the configuration file named explicitly and .gitignore used as the ignore path, so the formatter and the repository agree on what is in scope. There is a separate script for the write mode.
Typecheck runs tsc against jsconfig.json rather than a tsconfig.json, which is what a JavaScript project uses when it wants the checker without a build step. And eslint runs against one file, ./cli.js, with a fix variant alongside.
That last detail is the honest limit of the setup. Linting is applied to the command line entry point and to nothing else in the repository, while formatting and validation apply to everything. For a catalog of JSON files that split is defensible: there is one program to lint and thousands of schemas to format and validate.
Prettier sorts JSON keys, which is why the schemas read alphabetically
The formatter is not a stock configuration. Alongside prettier itself the dependencies include prettier-plugin-sort-json and prettier-plugin-toml, plus smol-toml and yaml as the parsers, and a .prettierrc.cjs that points at all of it.
Two consequences follow. JSON files have their keys sorted rather than kept in the order the author wrote them, which is why a schema in this repository reads as an alphabet of property names instead of the logical grouping a human would choose. And TOML files are formatted by prettier too, which matters because the catalog is kept as TOML: the format has its own plugin and its own parser in the dependency list rather than being handled by a general-purpose YAML path.
The result is that a schema contributed here comes back reformatted before review. That is convenient for a repository with this many files and slightly annoying if you are trying to read a diff of the semantic change you made.
Two other small tools sit alongside. ora is a terminal spinner and minimist is an argument parser, which together are the two things a command line tool needs to look present while it runs. Both are development dependencies, so they belong to the site tooling rather than to any schema consumer.
The MCP endpoint has three config shapes for two IDEs and every other client
The one part of this project designed to be used by an assistant is an MCP server, and it is hosted rather than installed. The endpoint is public, no local setup is required, and the transport is HTTP.
For Visual Studio Code you create a .vscode/mcp.json in your workspace:
{
  "servers": {
    "SchemaStore": {
      "url": "https://mcp.schemastore.org/",
      "type": "http"
    }
  }
}
Visual Studio takes a .mcp.json at the solution root instead, and the file shape is different: it carries an inputs array and a headers object around the same server entry.
For anything else, the instruction is a single sentence: point your client at the same URL using HTTP transport. That is what makes the endpoint usable outside two specific editors, and it is why the URL ends in a slash in every example.
The distinction to notice is that the schema store and the server are different things. The MCP server has its own repository, and the catalog you are pointing at is this one. So an assistant configured this way reads schemas from the catalog over a service run somewhere else, and neither is bundled with your editor.
The MCP server lives in another repository entirely
The server is not in this tree. The readme links a separate repository for the SchemaStore MCP server and describes what it does: search, browse and retrieve JSON schemas from the catalog.
That separation is the practical thing to understand about this project. Contributing a schema means working in this repository, which is files plus validation and formatting. Running or changing the endpoint means working in the other one. Nothing in the tree here contains server code, and the only trace of the endpoint in this repository is documentation.
It also means the version relationship between the two is not visible from here. There is no releases list to compare, no dependency pinning the server to a catalog revision, and no manifest field naming a required server version. The catalog is updated by commits to master and the endpoint is whatever that server currently serves.
For an editor user the effect is small and mostly invisible: schemas you get through the endpoint are as current as the catalog at the moment you ask. For anyone building a pipeline that needs a stable, repeatable answer, that is the gap to plan around, and the raw schema files are the more predictable route.
The catalog is volunteer-run and the readme asks for sponsorship directly
The last section of the readme is not documentation, it is a funding request, and it is unusually blunt about who benefits.
It says that keeping the site running smoothly requires time, effort and resources, that the infrastructure and maintenance costs have grown alongside its popularity, and that it is still volunteer-driven. It then says that for-profit organizations are among the biggest beneficiaries, because they use the schemas to validate configurations, cut steps out of their workflows and save time, and asks those organizations to consider sponsoring the project so that hosting, maintenance and development costs are covered and the resource stays free and open.
That is worth reading as information about the project rather than as an appeal. A volunteer-run catalog with growing costs and no release cadence is a dependency with a maintenance risk, and the project is stating that risk itself. It is also the only signal about operational stability you get from the repository.
The licensing position is cleaner than the funding position. The licence is Apache 2.0 with a NOTICE file, the code of conduct and a contributing guide are both present, and the project is not archived with a push on 2026-10-01.
A Visual Studio solution file sits next to a JavaScript manifest
The top level of the repository contains SchemaStore.sln, which is a Visual Studio solution file, alongside a package.json, a JS-oriented eslint config and a jsconfig.json.
The solution file belongs to the MCP integrations rather than to the catalog. It is consistent with the readme documenting a .mcp.json format for Visual Studio, which is a Visual Studio concept: this repository carries tooling to produce and check the client configuration files that Visual Studio consumes.
Several other entries describe what kind of repository this is. CNAME is the custom domain file that maps the site to its own hostname, so the site is served as static content from a custom domain rather than from a path. .codespellrc is a spell checker configuration, which matters more than usual when the content is other people's tool names. .git-blame-ignore-revs is a list of commits to exclude from blame, which is what a repository looks like after it has reformatted itself wholesale.
The scripts/ and src/ directories hold the site generation, and config/ holds the catalog. That is the whole layout: catalog, site, tooling, and the editorial files around them.
Editorial conclusion
SchemaStore is the right dependency if your editor or agent needs a schema for a configuration format nobody wants to hand maintain, and if being a few days behind the upstream format is acceptable. It is the wrong choice if you need a versioned, guaranteed-current schema for a production pipeline, because there are no releases to pin and the last push was on 2026-10-01. Before depending on it, decide whether you want the raw schema URL or the MCP endpoint, since the endpoint lives in a separate repository and is described as publicly hosted with no local setup, and if you rely on either, plan for the catalog being volunteer-run and asking sponsors to cover its hosting.
Frequently asked questions
What exactly is a JSON Schema in SchemaStore's terms?
It is one of the JSON schema files in the catalog. SchemaStore describes itself as a universal JSON schema store and as the largest collection of independent JSON schemas in the world, where schemas for popular JSON documents can be found, published at schemastore.org from the master branch.
What is SchemaStore used for in an editor or a tool?
It lets a tool fetch the schema for a configuration file instead of shipping one. Its own tooling covers that job with ajv, ajv-formats, ajv-keywords and a draft-04 validator, jsonc-parser for JSON with comments, jsonlint for the schema files themselves, and yaml and smol-toml for the catalog formats.
How do I use SchemaStore from VS Code or Visual Studio?
In VS Code you create a .vscode/mcp.json in your workspace with a server entry pointing at https://mcp.schemastore.org/ with the type set to http. In Visual Studio you add a .mcp.json at the solution root instead, which also carries an inputs array and a headers object around the same server entry.
Is SchemaStore a schema registry, and how is it maintained?
It is a static collection of schema files rather than a registry service with its own API. There are no GitHub releases to pin, the default branch is master, the last push was on 2026-10-01, and the readme describes the site as volunteer-driven while asking for sponsorship to cover hosting and maintenance.
What exactly does SchemaStore store, and how is it checked?
JSON schema files for popular JSON documents, kept as a catalog. The repository formats them with prettier plus a plugin that sorts JSON keys, lints them with jsonlint, validates them with ajv at both draft-04 and draft 2019-09, and runs those checks through a pre-commit configuration.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/schemastore-schemastore)Star history chart for your README
[](https://hysenlabs.com/projects/schemastore-schemastore)Was this useful?