html5ever has one release on record while its workspace sits at 0.40.1
High-performance browser-grade HTML5 parser
At a glance
- What is it?
- servo/html5ever is the browser grade HTML parser written in Rust for the Servo project, and it has a design that explains most of its shape: the parser drives the document through callbacks and deliberately owns no tree, a separate crate in the same workspace holds the tree, strings are UTF-8 only with other encodings listed as future work, and the page is candid that its behaviour differs from the specification in ways the project tracks under its own bug label. One release appears on the record while the workspace manifest is five minor versions ahead of it.
- Who is it for?
- Use html5ever if you are parsing untrusted HTML in Rust and want a parser that follows the specification closely and ships with no garbage collector, because that is exactly what it is and the specification conformance work is visible rather than claimed. Three things to check before you commit.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
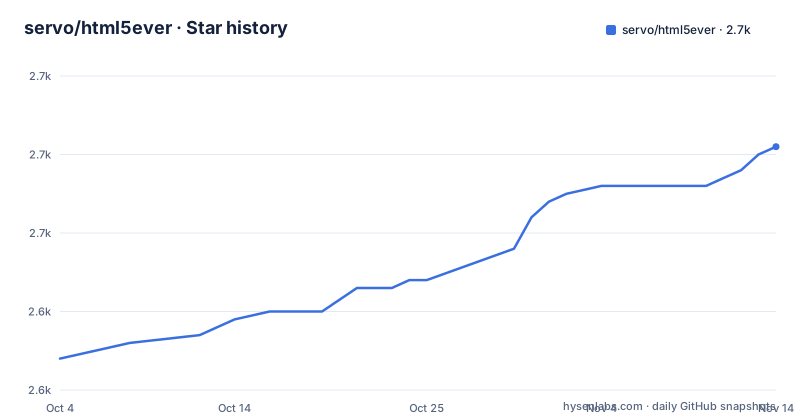
- servo/html5ever2,661 ★ · +27
| Repository | 2026-10-04 | 2026-11-14 |
|---|---|---|
| servo/html5ever | 2.6k | 2.7k |
27 Stars in the last 41 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One release on record while the workspace sits at 0.40.1
The release list has one entry: a tagged crate release from the middle of 2025. The workspace manifest declares the shared version as five minor versions higher than that. The last commit to the repository is dated September 2026, so the gap is not a dormant project, it is a project whose crates have not been published in a year while their source has moved on. That matters more here than it would for a small utility, because the crates are the parser other people's browsers and tools depend on, and a dependency pinned to the published release is a dependency pinned to code that predates a year of fixes. The page's own advice points the same way: it links the generated documentation for the published crate rather than telling you to build from the branch, which is the safe choice and also the one that misses everything new.
The parser has no tree and a separate crate has the tree
One line in the details section is the most important thing on the page: the parser uses callbacks to manipulate the document and therefore provides no DOM tree representation at all. That is a deliberate architectural choice rather than an omission, and it is what lets a browser embed the parser without allocating a tree it would only throw away. It also means the library you reach for is not the library you probably want. A separate crate in the same workspace provides an in-memory document, and the two example programs on the page exist to show both shapes: one converts a document from one form to another without materialising it, and one walks a materialised tree and prints it. A user who installs the parser and then reaches for a tree has to discover the second crate, and the page does not connect the two for them.
Strings are UTF-8 only and other encodings are future work
The parser represents every string as UTF-8, and the page says that support for other document encodings will come in future by converting the input on the way in, together with a supplementary plane aware variant of a runtime document write. That is the honest way to phrase a real limitation, and it is a real one for a parser whose selling point is that it handles what browsers handle. Legacy documents that declare their own encoding, which is most of what a large archive contains, will be mis-decoded unless the caller transcodes them first. The encoding library it already depends on is the one that knows those tables, so the capability is present in the tree; it is the wiring that is deliberately absent. The same paragraph explains the practical consequence of the language choice, which is that the performance profile resembles a parser written in C without the collector.
The conformance gap is tracked under its own label
The page claims browser grade parsing to the specification and then, two sentences later, says there are differences in actual behaviour, most of which are documented in the bug tracker, and gives a link filtered to open issues carrying a web compatibility label. That link is the most useful thing in the paragraph, because it converts a vague caveat into a query you can run. The testing position is stated with the same precision: every tokeniser test from the standard suite passes, most tree builder tests pass outside the features that are not implemented, and the stated goal is to pass the whole suite while providing the hooks a production browser needs, naming a runtime document write as the example. A user deciding whether the parser is safe for their input can therefore read the gap list rather than trusting the adjective.
Seven crates where the name suggests one
The workspace holds seven members and the published crate is one of them. There is an HTML parser, an XML parser, a layer that both share, an in-memory document, a table of web-wide names, and a string interning library with its own benchmark. The naming convention makes the layering obvious once you read it, and so does the dependency list: the parser depends on the shared layer, the shared layer depends on the interning library and the name table, and both the HTML and XML parsers sit on top. That structure is why adding a dependency is not a single crate operation, and why the example paths on the page live inside a subdirectory rather than at the repository root. It also means an upgrade is a coordinated move across several published crates rather than one version bump.
Internal dependencies carry versions as well as paths
Every internal dependency in the workspace list is written twice: once with a version and once with a path to the sibling directory. The form is deliberate, because a path alone is useless to anyone consuming the crate from a registry, and it makes the intent explicit that the crates move together. The cost is that publishing has an ordering requirement the manifest cannot express: the shared layer has to be published before the parsers that name a version of it, and every crate in the workspace shares one version number. That is why the workspace carries a single shared version field rather than one per crate, and why the release document at the root is a separate file rather than a paragraph in the readme. It is a small amount of ceremony for a set of crates that have to agree.
The test suite arrives as a submodule and the docs build with cargo
Working on the project takes two commands, and the first is not a build. The test suite is a submodule, so it has to be initialised before anything can be checked against it:
git submodule update --initThat is the correct arrangement for a specification suite that other people also contribute to and the wrong one for a contributor who wants to run a quick check. The second command builds the documentation locally with the usual documentation tool, and the page points at two example programs as the intended starting point. There is also a line about language versions that is worth reading precisely: the project builds against stable releases of the compiler, though some optimisations are only available on nightly ones. That is a deliberate split, and it means a stable build is a slightly different binary from a nightly one rather than the same binary with a different setting.
Editorial conclusion
Use html5ever if you are parsing untrusted HTML in Rust and want a parser that follows the specification closely and ships with no garbage collector, because that is exactly what it is and the specification conformance work is visible rather than claimed. Three things to check before you commit. It gives you callbacks, not a document, so if you want a tree in memory you are adding a second crate from the same workspace and inheriting its design. It is UTF-8 only, which is fine for content served today and wrong for older documents with declared encodings. And the version you depend on comes from a registry with a single release recorded while the workspace moves, so read the release notes before pinning and expect to track the branch for anything newer.
Frequently asked questions
What is html5ever?
A browser grade HTML parser written in Rust and developed as part of the Servo project. It parses and serialises HTML according to the WHATWG specifications and passes all of the standard tokeniser tests.
Does html5ever produce a DOM?
Not in its core. It manipulates the document through callbacks and deliberately provides no tree representation, and a separate crate in the same workspace provides an in-memory document you can walk.
Does html5ever handle documents that are not UTF-8?
No. It represents strings exclusively as UTF-8, and the page lists support for other document encodings as future work to be handled by converting the input.
Is html5ever fully conformant with the HTML specification?
The page says there are differences in actual behaviour, most tracked in the bug tracker under a web compatibility label, that all tokeniser tests pass, and that most tree builder tests pass outside the features that are not implemented.
How do I add html5ever to a Rust project?
With one cargo add command, then read the two example programs it points to and the generated API documentation. For the parser's own test suite you need to initialise the submodule that holds it.
Why is html5ever written in Rust?
The page gives two reasons: it avoids the security problems that come with a parser written in C, and it delivers the performance of a C parser without a garbage collector or a heavy runtime.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/servo-html5ever)Star history chart for your README
[](https://hysenlabs.com/projects/servo-html5ever)Was this useful?