EasyR1: A Practical Path to Multimodal RL Training on top of veRL
EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework based on veRL
At a glance
- What is it?
- EasyR1 is a clean fork of veRL that adds vision-language support, several RL algorithms, and LoRA training. It lowers the barrier for GRPO on VLMs but inherits veRL's complexity and hardware demands.
- Who is it for?
- Adopt EasyR1 if you are already using veRL and need to run GRPO, DAPO, or Reinforce++ on Qwen-VL or Llama models with full or LoRA tuning, and if you have multiple high-memory GPUs. Do not choose it if you need a production-stable, broadly documented framework or if you are new to RL training, because the README assumes you know veRL's Ray and FSDP concepts.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
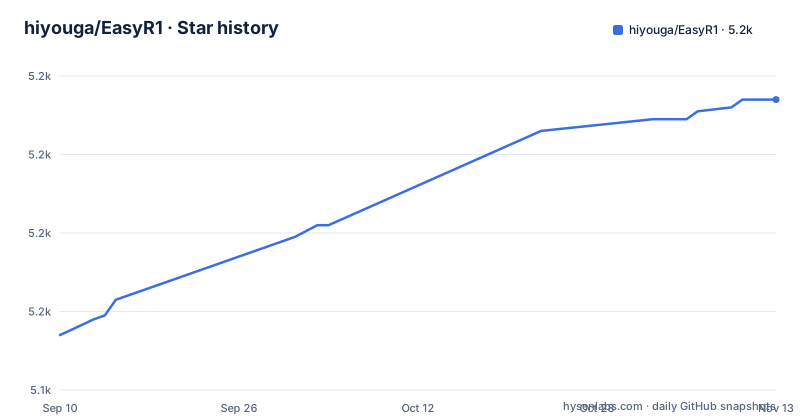
Star history
- hiyouga/EasyR15,214 ★ · +60
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| hiyouga/EasyR1 | 5.2k | 5.2k |
60 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What EasyR1 solves and who it targets
EasyR1 addresses a specific gap in the veRL ecosystem: reinforcement learning for vision-language models. EasyR1 is a fork of veRL made to support vision language models such as Qwen2-VL, Qwen2.5-VL, and Qwen3-VL. The target user is an engineer or researcher who already runs RL training with veRL and wants to extend that to multimodal inputs without writing a custom fork. The README lists supported algorithms: GRPO, DAPO, Reinforce++, ReMax, RLOO, GSPO, and CISPO. That is a broad set, but the README tutorial centers on GRPO with Qwen2.5-VL on a geometry dataset. If you are working on visual reasoning tasks like counting or geometry, this project gives you a ready-made starting point. For text-only work, the original veRL remains the more established choice.
How it works: a fork with vision extensions
EasyR1 is not a from-scratch framework. It is a clean fork of veRL, and its efficiency claims rest on two external pieces: the HybridEngine design from a 2024 paper and vLLM's SPMD mode. The architecture therefore follows veRL's pattern: a Ray cluster coordinates actors and a vLLM-based rollout engine, with FSDP for model sharding. The vision support is the main addition, letting the same pipeline handle image-text and multi-image inputs. The README's GRPO section points to Hugging Face's blog rather than explaining the algorithm in text. What is clear is that the training loop samples rollouts, computes rewards, and updates the policy, all orchestrated through veRL's existing components. For a user, the practical effect is that you write a shell script that calls a Python entry point, and the framework handles distributed communication. The reliance on vLLM and Ray means you are tied to those projects' release cycles, which is a real constraint for reproducibility.
Getting it running: commands and config keys
Installation is straightforward if you have the right GPU environment. The README gives three commands: clone the repository, change into the directory, and run pip install -e. It also recommends a pre-built Docker image, which is the safer route given the dependency stack: Python 3.9+, transformers>=4.54.0, flash-attn>=2.4.3, and vllm>=0.8.3. After install, you run one of the example shell scripts, such as bash examples/qwen2_5_vl_7b_geo3k_grpo.sh for full GRPO training or the LoRA variant for a 4B model. The scripts contain the actual configuration, so you must edit them to change dataset or model paths. The examples directory also contains a config.yaml. For bf16 training, you set worker.actor.fsdp.torch_dtype=bf16 and worker.actor.optim.strategy=adamw_bf16. Checkpoint merging requires a separate script: python3 scripts/model_merger.py --local_dir checkpoints/easy_r1/exp_name/global_step_1/actor. That is a concrete workflow.
Hardware requirements and the LoRA escape hatch
The hardware table is the most useful part of the README for planning. For GRPO full fine-tuning with AMP, a 1.5B model needs 2 GPUs with 24GB each, while a 72B model demands 32 GPUs with 80GB each. In BF16, the numbers roughly halve but remain substantial. LoRA fine-tuning cuts requirements dramatically: a 1.5B model fits on a single 12GB GPU, and a 72B model needs 4 GPUs with 80GB each. That makes LoRA the only realistic option for smaller labs. The README marks these as estimated, so treat them as planning guides, not guarantees. The BF16 path requires explicit config keys, which suggests the default is AMP and you must opt into the lower memory mode. This table gives a clear boundary: if you cannot assemble at least one 24GB GPU for BF16 or two for AMP, full fine-tuning is impractical, and you should look at LoRA or a smaller model.
What is missing: documentation and evaluation depth
The README is thin in several places. It links to a baselines.md file for performance numbers but does not summarize any results in the main text. The GRPO explanation is a pointer to Hugging Face's blog, not an in-depth description of how EasyR1 implements the algorithm. For custom datasets, you must reverse-engineer the format from example datasets on Hugging Face, which is a non-trivial task. The multi-node instructions give four Ray steps and defer to veRL's official docs for more details. If you are new to veRL, this project will not teach you the fundamentals. The README does mention a Docker pull count and a star badge, but those are not evidence of stability. The lack of a changelog beyond release titles means you cannot easily assess what changed between v0.3.1 and v0.3.2. That is a genuine limitation for anyone planning a long-term adoption.
Alternatives and the real difference in approach
The most direct alternative is the original veRL, which EasyR1 forked. The difference is scope: EasyR1 is a clean fork of veRL made to support vision language models. If your work is text-only, you should stay with veRL. For multimodal RL, another alternative is TRL from Hugging Face, which has a GRPOTrainer that supports VLMs to some degree. TRL takes a different approach: it is a higher-level library that integrates with the transformers Trainer API, whereas EasyR1 is a distributed training framework built on Ray and vLLM. EasyR1 offers a more direct path to large-scale multi-node training, but only if you accept the operational overhead of Ray and vLLM. The choice depends on your cluster size and your comfort with managing distributed systems.
Maintenance, licensing, and upgrade cost
EasyR1 is released under Apache-2.0, which is permissive and allows commercial use, modification, and redistribution without copyleft obligations. That is a low-license-risk choice for most organizations. The project is actively maintained, with a release in September 2025 and a last push in September 2026, so you can expect ongoing changes. The upgrade cost is real because the framework depends on fast-moving projects like vLLM and transformers. Each release of those libraries may force you to update EasyR1. The release notes are minimal, just titles like "RL Baselines" and "Multi-modal DAPO", so you cannot predict breaking changes. The Docker image is the mitigation: it pins a known-good environment. However, if you need to customize the training loop, you will be reading veRL's source code, not EasyR1's documentation, which is sparse. Budget time for debugging when you move beyond the example scripts.
Editorial conclusion
Adopt EasyR1 if you are already using veRL and need to run GRPO, DAPO, or Reinforce++ on Qwen-VL or Llama models with full or LoRA tuning, and if you have multiple high-memory GPUs. Do not choose it if you need a production-stable, broadly documented framework or if you are new to RL training, because the README assumes you know veRL's Ray and FSDP concepts. Before adoption, verify that your exact model and vLLM version are compatible, test the provided example scripts on a small model, and check the baselines.md file for reproducible results. The project is under active development, so plan for frequent changes and rely on the Docker image to avoid environment drift.
Frequently asked questions
What does EasyR1 change relative to veRL?
EasyR1 describes itself as a clean fork of veRL made to support vision language models, adding Qwen2-VL, Qwen2.5-VL and Qwen3-VL to a model list that also covers Llama3, Qwen2, Qwen2.5, Qwen3 and DeepSeek-R1 distill models. Its scaling story rests on HybirdEngine and the SPMD mode of recent vLLM releases.
Which reinforcement learning algorithms can EasyR1 run?
The README names GRPO, DAPO, Reinforce++, ReMax, RLOO, GSPO and CISPO. The examples directory adds qwen2_5_vl_7b_geo3k_sapo.sh, so SAPO ships as a runnable script without appearing in that list, while ReMax and RLOO are listed without a top-level example script.
How much GPU memory does EasyR1 need for GRPO full fine-tuning?
The table is marked as estimated. Its BF16 row lists 1*24GB at 1.5B, 1*40GB at 3B, 4*40GB at 7B, 8*80GB at 32B and 16*80GB at 72B, and the note under the table says BF16 needs worker.actor.fsdp.torch_dtype=bf16 with worker.actor.optim.strategy=adamw_bf16.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hiyouga-easyr1)Star history chart for your README
[](https://hysenlabs.com/projects/hiyouga-easyr1)Was this useful?