Silex's container image ships a placeholder session secret and defaults to the SaaS config
Silex is an online tool for visually creating static sites with dynamic data. With the free/libre spirit of internet, together.
At a glance
- What is it?
- A non-profit visual website builder exporting static HTML, licensed under the copyleft licence and run from a desktop shell built on Tauri. Its container image sets a session secret to a string that says to replace it, loads the hosted service's configuration by default, and enables only FTP connectors out of the box. The only published releases are canary builds, and the manifest version reads as a development placeholder.
- Who is it for?
- Silex suits someone who wants a visual editor that produces ordinary static files rather than a proprietary site format, and who is prepared to run the container themselves rather than use the hosted service. Before deploying it, check five things.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
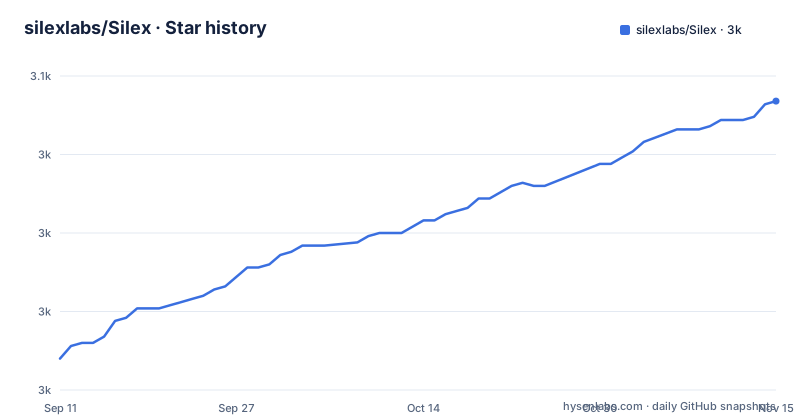
- silexlabs/Silex3,042 ★ · +82
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| silexlabs/Silex | 3k | 3k |
82 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The image ships a session secret that says to replace it
The container file sets about thirty environment variables, and one of them is the one to look at first. The session secret has the literal value replace this session secret in env vars, as a quoted default baked into the image.
That is a placeholder rather than a secret, and it is the kind that survives into production because nothing fails when it is left alone. A session secret is what signs the cookie that identifies a logged-in user, so every instance started from the same unmodified image is signing its cookies with the same string. Two people running it would each be able to present a cookie the other accepts.
The file does say what to do. A comment above the variable block points at a wiki page on hosting an instance and notes that the values can be overridden with the command-line option when running the container directly. So the instruction exists, in the right place, for someone reading it.
The same file also leaves the certificate-related variables empty: an SSL port, a private key, a certificate, and a flag for forcing HTTPS. The protocol default is plain HTTP and the host default is loopback, so the shipped defaults are a local development posture rather than a public one. The session secret is the one variable that is set to a non-empty placeholder rather than left empty, which is what makes it easy to miss.
Three body-size limits are also configurable, and the asymmetry is worth noting: the limit for form-encoded bodies is a tenth of the limit for text.
The image loads the hosted service's configuration by default
Self-hosting this project requires overriding two environment variables, and the container file says so in a comment near the end of its build steps.
The default configuration for the hosted service lives in a directory inside the server source, and it is loaded unless you point the two variables at your own files. So running the container without reading that comment gives you an instance configured the way the hosted service is configured, not the way your deployment needs.
That is the opposite of the usual arrangement, where a container defaults to something minimal and you add configuration. Here the defaults are the production ones, and the self-hosted path is the override.
There is a second inconsistency in the same area. The compose file builds using the container file at the repository root, because it names that file as the build argument with the context set to the root. The platform deployment definition at the root, for the one-click hosted option, names a different path for its container file, pointing into the server's deploy directory instead. Two entry points, two different paths, and no note reconciling them.
The compose file also carries a commented-out block for a content management system and its database, with credentials written into the comments. It is scaffolding for a local integration rather than anything active, but it means the file someone copies from contains example passwords.
Only FTP connectors are enabled, and two GitLab applications are preconfigured
The storage and hosting connectors are environment variables with comma-separated defaults, and the defaults are modest. Storage defaults to FTP alone. Hosting defaults to FTP plus direct download. Nothing else is enabled until you name it.
That is a defensible default for a project that hosts sites as static output, but it means the GraphQL content systems the feature list advertises, along with the object store option and the Git integration, all require explicit configuration before they do anything.
The GitLab variables are the most interesting part of the set. There are two complete sets of four variables, one prefixed with the service name and one with the service name plus a digit, each holding a display name, a domain, a client identifier and a client secret. Two sets means two separate OAuth applications, which is what you need when the hosted service talks to the public instance and a self-hosted instance talks to an internal one.
It also explains a requirement stated elsewhere in the documentation: the free hosted tier needs an account with that service for storage. So the two most prominent paths, the hosted editor and your own container, both end up authenticating against the same external identity service, and the credentials for it are supplied through environment variables rather than anything you can configure from inside the application.
The published releases are canaries and the manifest version is a placeholder
Three releases are visible and all three are canary builds of the same upcoming version. The newest canary is from September, the two before it from late July, five days apart. There is no stable release among them.
Alongside that, the package manifest gives the project a version of zero point zero point zero with a development suffix. So the artefact you would install from a registry is versioned as a development build while the published tags are pre-releases of a numbered version that has not shipped.
That combination is normal for an application that is not primarily consumed as a library. Nobody pins an application build the way they pin a library, and the hosted service runs whatever the continuous integration produced. It does mean there is no stable identifier to point at, and a reader trying to work out which version is deployed has three canary tags and a development placeholder to choose between.
The runtime floor is declared twice. The manifest requires a node version of twenty-four or newer, and a separate version-manager file at the root pins a node version for contributors. The container file matches by building from a node twenty-four base image. So three files agree, which is more than most projects manage, and it means the floor is a hard one rather than a suggestion.
The model context protocol server exists only in the desktop app, on a second port
The application listens on one port. The model context protocol endpoint listens on another, and the documentation is careful that the second one is not part of the hosted service.
The instructions are prefaced with a condition: once the desktop application is running, connect your tool to a loopback address on the protocol port. So the protocol server ships in the desktop build, which is marked alpha, and not in the hosted editor or in the container.
That is the opposite of how the feature is marketed. The section promoting prompt-driven site building describes the desktop app as the thing that will let you create and transform sites through prompts, and the protocol section is nested under it. The headline capability is therefore only reachable through the alpha channel, which the same document describes as still in progress.
The positioning is otherwise careful. The protocol is named as an open standard, and the choice of model is left to the reader: a local one for privacy, or any compatible client tool. Four client configurations are given, one of them a single command, and one of the four is for the tool this agent runs under. There is also a stated design constraint: the server is optimised for small local models, with a parameter size given as the floor.
The roadmap links point at a separate site, where a prompt library, a cookbook and a best-practices guide are promised as contributions rather than shipped.
Three toolchains, three compiler configurations and two container files
The repository is built with three languages and configured three separate times over.
The client is bundled by one tool, the server is compiled by a different one, and the public assets are copied by a script. The server compile is itself two passes: one to emit, and a second whose only job is to rewrite the import paths in what the first produced. The desktop application adds a filtered build of its own dashboard package, named separately from the main one.
Alongside that sits a Rust workspace with two members, one of which is the desktop application's native shell. Its comment explains that the desktop app opens the repositories holding the server's websites and that one version serves both. The workspace pins a single git library with its default features switched off, which for that library means the transports it would otherwise enable are not compiled in.
TypeScript is configured three times: a base configuration, one for the server release build, and one general. Three container files exist, one of which is named for verification rather than packaging, and one platform deployment definition at the root points at a build path that differs from the one the compose file uses.
Submodules are required to clone, the clone command carries a flag for it, and the container build filters its install to a single named package with the lockfile frozen rather than installing the whole workspace.
The contributor path is the shortest complete route in, and it starts by pulling more than one repository:
git clone --recurse-submodules https://github.com/silexlabs/Silex.git
cd Silex
pnpm install && pnpm build && pnpm start
The submodule flag is not optional here. The tree carries a submodule manifest, so a plain clone leaves the build missing whatever those references point at. After that the install, the build and the start run as one chain, and the application answers on a loopback port.
The keyword list repeats itself and names a competitor
The package manifest carries thirty-three keywords, which is close to the maximum the registry accepts and several times what it recommends.
Some of them repeat. One word appears three times as a standalone entry. Another appears twice. Several more are near-duplicates of each other rather than exact repeats: a designer variant, a webmaster variant and a two-word version of the latter all sit in the list independently.
Then there is the entries that are not describing the project. One is the name of a different static site generator, which this is not built on or compatible with in any documented way. Another is a phrase naming a specific commercial product as the thing to search for instead. Another is an instruction-like phrase matching how someone might type a search query.
None of that is unusual for a project that has been around long enough to have accumulated search terms, and keyword stuffing is a recognised practice on package registries. But it does mean the keyword field is not a description of what the software is, and reading it as one would give a misleading picture of the scope.
The rest of the manifest is conventional and honest: the description is one plain sentence, the author is a named person with a link, the licence is the copyleft one with an or-later suffix, and the bugs field points at a chat community rather than at an issue tracker.
One person appears in every contributor year, and the list is generated
The contributor section carries a marker comment saying it is auto-generated, and then lists people by year. The most recent year has fifteen names, and each earlier year has fewer.
One name appears in every year shown. The same person heads the 2026, 2025, 2024 and 2023 lists, and the surrounding text names that person as the maintainer, with the project owned by the non-profit. So the project's continuity across four years rests on one commit author, and the list itself makes that visible by repetition rather than by saying so.
The contributor list also exists twice. A separate thanks file sits at the repository root, and the readme carries its own generated section. Two places to update, one of them regenerated by a tool and one of them maintained by hand.
The two pull-quotes near the top of the document are unattributed. One calls the project the only open source alternative to a named commercial platform, and the other is a first-person claim about graphical precision with no name attached. Neither links to a source, and for a project that argues its case on ownership and transparency, uncredited testimonials are the least substantiated content in the file.
The rest of the ownership argument is specific and checkable: a non-profit with a stated legal recognition, no investors, finances on a funding platform, and a licence that includes every feature with no paid tier.
Editorial conclusion
Silex suits someone who wants a visual editor that produces ordinary static files rather than a proprietary site format, and who is prepared to run the container themselves rather than use the hosted service. Before deploying it, check five things. Replace the session secret in the image, because it ships with a placeholder string and any instance left as-is shares it. Set the configuration overrides so you are not running the hosted service's defaults, and note that the compose file and the platform deployment definition point at different Dockerfile paths. Decide which connectors you actually need, since only FTP and direct download are enabled by default. Treat the desktop application as alpha, because the model-context-protocol server exists only there, on a separate port from the application itself. And pin a specific build rather than a canary, since no stable release appears among the published tags.
Frequently asked questions
What licence is Silex under and what does it cost?
The copyleft licence with an or-later suffix, and the readme states it is always free with all features included and no premium tier. The project is owned by a non-profit recognised as being of general interest, with no investors and finances on a public funding platform.
How do I run Silex locally to contribute to it?
Clone with the flag that also pulls submodules, change into the directory, then run the package manager's install, build and start in one chain. The application then answers on a loopback port. Docker and production setups are covered by a separate self-hosting guide.
Is there a stable Silex release?
No stable release appears among the published tags. All three visible tags are canary builds of the same upcoming version, and the package manifest gives the project a version of zero point zero point zero with a development suffix.
What does the Silex container image need changed before production use?
At minimum the session secret, which ships with a placeholder string, and the configuration overrides, because the image loads the hosted service's defaults unless you point two variables at your own files. Only FTP and direct download connectors are enabled by default.
Does Silex work with WordPress and a GraphQL CMS?
The feature list names WordPress, Strapi, Squidex and any GraphQL API as content sources to bind components to, and the target audience section describes reading content from WordPress through GraphQL in place of a theme layer. No connector is enabled by default; they are named through environment variables.
Can I use an AI assistant with Silex?
Yes, through an open model context protocol server, but it ships in the desktop application rather than the hosted service or the container, and runs on a separate loopback port once that application is running. The documentation states the server is optimised for small local models.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/silexlabs-silex)Star history chart for your README
[](https://hysenlabs.com/projects/silexlabs-silex)Was this useful?