SIMDe: the ISA in full, and three release candidates for 0.8.4
Implementations of SIMD instruction sets for systems which don't natively support them.
At a glance
- What is it?
- A header-only C library that implements SIMD intrinsics portably, so SSE code runs on ARM and NEON runs on x86 with no emulator in between. Its release channel and its build setup both say more about the project than the feature list does.
- Who is it for?
- SIMDe is a good fit when you are porting numeric code across architectures and want one source of truth that still compiles to native instructions on the machine that has them. Two things to plan for.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
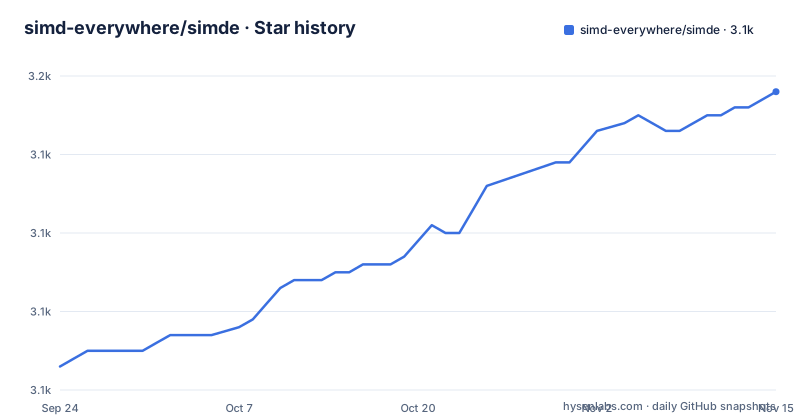
- simd-everywhere/simde3,148 ★ · +35
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| simd-everywhere/simde | 3.1k | 3.1k |
35 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three release candidates for 0.8.4 and no final
The release history explains how this project ships. The three most recent tags are all the same version: v0.8.4-rc1 on 2025-02-01, v0.8.4-rc2 on 2025-09-30, and v0.8.4-rc3 on 2026-02-22. No final 0.8.4 appears among them, while the most recent push to the master branch is dated 2026-09-30, seven months after the last candidate. Two things follow for anyone pinning a dependency. A release candidate is opt-in by name, so depending on the project means choosing a suffix deliberately rather than waiting for a stable tag, and the gap between candidates was seven months and then five, which is a slow cadence for a library that sits in other people's build trees. The repository is not archived, and the licence is MIT with a COPYING file at the root.
The whole instruction set, not the common denominator
The design position is stated as a difference from other layers, and it is the sentence worth reading twice. Most SIMD abstraction layers limit themselves to what every target can do, which produces a portable API and a slow one. SIMDe instead aims to expose the entire functionality of the underlying instruction set, trying to keep the porting effort small while leaving room to optimise where it matters. The consequence is visible in how a port proceeds. You get the build running almost immediately, then move the performance-critical sections onto native intrinsics one at a time. Because both can coexist, SSE and AVX code and NEON code live side by side in the same implementation, which is what makes the gradual approach practical rather than theoretical.
Native speed when the hardware has it
The promise is conditional and the condition is simple: where the hardware supports the instruction set natively, there is no performance penalty. SSE and AVX run at full speed on x86, NEON runs at full speed on ARM, and the same holds for the other extensions the project covers. When the hardware does not, the header-only implementation takes over, which is why calling an SSE function from ARM code is a supported operation rather than a portability trick. The second use is development rather than deployment: you can run NEON code on an x86 machine without an emulator, which shortens the edit and test loop while you are still writing the code. The project is explicit about the limit of that shortcut, saying you will eventually want to test on the actual hardware you are targeting, and SIMDe provides the easier path rather than a replacement.
Four routes to an accelerated implementation
Where a fast path exists, the README names the mechanisms rather than promising a benchmark. The first is using intrinsics from a different instruction set extension, with NEON implementing SSE given as the example, which is what lets one extension cover another. The second is compiler vector extensions and built-ins, naming __builtin_shufflevector and __builtin_convertvector as the two that matter. The third and fourth are compiler auto-vectorisation hints: OpenMP 4 SIMD and Cilk Plus on one side, and loop-specific pragmas on the other, split into GCC loop pragmas and clang loop hint directives. All four are opt-in signals to a compiler rather than code you write by hand, so the acceleration depends on the toolchain recognising them. A large number of functions are said to have accelerated implementations this way, with the stated focus still on complete portable implementations.
The online demo loads one amalgamated header
There is a way to try the library without installing anything, and its design reveals how the project is packaged. The online demo runs through Compiler Explorer using an amalgamated SIMDe header, meaning the entire library is concatenated into a single file for that page to load. The script that produces it, amalgamate.py, sits at the repository root rather than in a build directory, which confirms that the single-header form is a first-class output and not a convenience bolted on afterwards. For questions, the project points at an issue tracker and a mailing list, and the badges at the top of the README point at a Gitter room bridged over Matrix and at a Codecov coverage page, so coverage reporting is part of the project's own tooling.
Two build systems and five CI configurations
The root of the repository carries both a CMakeLists.txt and a meson.build with a meson_options.txt beside it, so CMake and Meson are both first-class build paths. Continuous integration is broader than that: there is an AppVeyor file for Windows, an Azure Pipelines file, a CircleCI directory, a Travis file, a GitHub directory, and a Drone file whose name ends in .disabled, which records a pipeline that was switched off rather than deleted. A docker directory sits alongside them, and codecov.yml at the root is where the coverage thresholds live. Also present are .editorconfig, .mailmap for attribution, an .all-contributorsrc for the contributor list, and CONTRIBUTING.md. The accumulation is consistent with a library whose consumers span build systems and whose own tests have to run everywhere.
NEON is complete, the x86 side is a long tail
The status section lists which instruction set extensions have complete implementations, and the shape of that list is the practical guide to what you can rely on. On ARM, the entry is NEON. On x86 the list runs from the oldest extensions forward: MMX, SSE, SSE2, SSE3, SSSE3, SSE4.1, and CRC32, then AVX, AVX2, F16C, FMA, GFNI, XOP, and SVML, followed by a run of AVX-512 subsets including VPOPCNTDQ, BITALG, VBMI, VNNI, and VP2INTERSECT, along with VPCLMULQDQ. Several entries link to a per-technology list in Intel's intrinsics guide, which is how you find the exact function name. The declared current focus is complete portable implementations, and a .no-test directory at the root marks the area where implementations exist without test coverage, which is the place to be careful.
Editorial conclusion
SIMDe is a good fit when you are porting numeric code across architectures and want one source of truth that still compiles to native instructions on the machine that has them. Two things to plan for. First, pin a specific release candidate rather than assuming a final 0.8.4 exists, since the recent tags are rc1 through rc3. Second, accept that coverage is broad but uneven: NEON is complete and the x86 side is a long list of extensions, so check the status page for the exact intrinsic you depend on before you commit to it.
Frequently asked questions
What is SIMD Everywhere (SIMDe)?
A header-only C library of portable SIMD intrinsic implementations. It lets you call SSE functions on ARM or NEON code on x86 from the same source, and there is no performance penalty where the hardware supports the native instruction set.
How does SIMDe differ from other SIMD abstraction layers?
It aims to expose the entire functionality of the underlying instruction set instead of limiting itself to the lowest common denominator, while trying to keep porting effort small and leaving room to optimise the sections that matter.
Can I try SIMDe without installing it?
Yes. An online demo runs an amalgamated SIMDe header through Compiler Explorer, and the script that produces that single header, amalgamate.py, is at the repository root.
Which instruction sets does SIMDe implement completely?
ARM NEON, and on x86 the MMX, SSE, SSE2, SSE3, SSSE3, and SSE4.1 families plus CRC32, AVX, AVX2, F16C, FMA, GFNI, XOP, SVML, and AVX-512 subsets including VBMI, VNNI, BITALG, VP2INTERSECT, VPOPCNTDQ, and VPCLMULQDQ.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simd-everywhere-simde)Star history chart for your README
[](https://hysenlabs.com/projects/simd-everywhere-simde)Was this useful?