PDFParser calls itself limited maintenance while v2.13.0-beta1 asks for testers
PdfParser, a standalone PHP library, provides various tools to extract data from a PDF file.
At a glance
- What is it?
- A small PHP library for pulling text and metadata out of PDF files, documented in 204 words that spend more room on a maintenance warning than on the parser. The repository itself carries the details the README leaves out: a Makefile with four targets and no aggregate, a toolchain installed as its own Composer project, and a sample corpus built around the files the library says it cannot handle.
- Who is it for?
- This is a parser with a stated scope, and the scope is text and metadata on ordinary, unlocked PDFs. If that is the job, the Composer line is short and the sample corpus will tell you more about what breaks than the feature list will.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
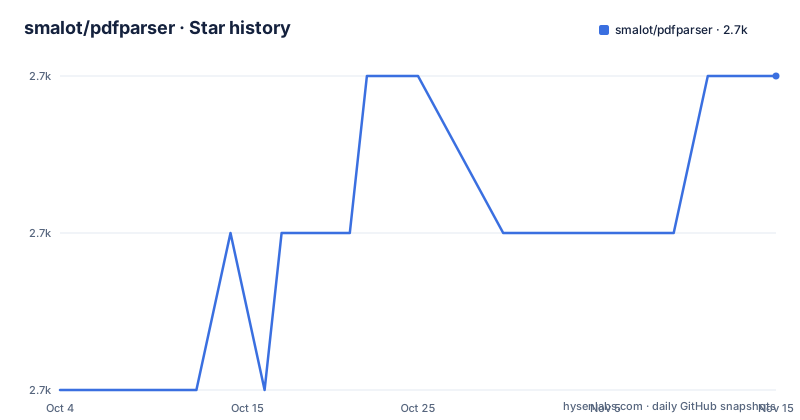
- smalot/pdfparser2,733 ★ · +2
| Repository | 2026-10-04 | 2026-11-15 |
|---|---|---|
| smalot/pdfparser | 2.7k | 2.7k |
2 Stars in the last 42 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The maintenance notice sits next to a beta asking for testers
The file opens with a maintenance status block that says the library is under limited maintenance, that it is kept compatible with supported PHP versions, and that community contributions may be accepted. Two things are then excluded in bold: there is no active feature development, and there is no guarantee that pull requests will be reviewed or merged in a timely manner. Contributors are sent to CONTRIBUTING.md with a threshold attached, anything beyond a small well scoped fix should read it first. The release history does not match that tone. The newest tag is v2.13.0-beta1, published on 25 September 2026, and its release name reads Call for testers! with bugfixes and performance gains attached. Performance work is not a small well scoped fix, so the beta sits against the notice the same file prints. The branch itself is not dead either: the last push to master is dated 22 September 2026. Read the two together and the picture is a library whose maintainers cap their promises in the README and keep shipping anyway.
Secured documents and forms are out of scope, and the samples hold both
The feature list ends with a sentence that reads like an apology: currently, secured documents and extracting form data are not supported. The sample corpus then contains exactly those two cases. There is samples/not_really_encrypted.pdf, a filename that concedes the encryption is not real, which is the right fixture for telling a genuinely secured document apart from one that merely looks locked. There is samples/corrupted.pdf for input that does not parse at all. There are also samples/SimpleInvoiceFilledExample1.pdf and samples/SimpleInvoiceFilledExample2.pdf, filled invoice forms, which is the case the second half of that sentence puts out of scope. Read as a pair, the sentence and the fixtures say the same thing from opposite ends. Text from ordinary pages is the supported path, and locked files, filled forms, and broken files are inputs the library is expected to survive rather than features it promises.
Sample filenames record which program wrote the PDF
A large part of the corpus exists to note which producer generated a file, because the internal structure of a PDF follows the tool that wrote it. Document1 appears from four sources: Document1_foxitreader.pdf, Document1_pdfcreator.pdf, Document1_pdfxchange.pdf, and Document1_pdfcreator_nocompressed.pdf, with Document2 and Document3 following the same naming from pdfcreator. A whole directory is organised on this axis as well, samples/grouped-by-generator/. Two filenames record a difficulty rather than a producer. Document-Word-Landscape-printedaspdf.pdf is a Word document exported through a print dialog, the route that shifts glyph positions and wraps lines by hand, and ImproperFontFallback.pdf names a font substitution problem outright. InternationalChars.pdf and XMP_Metadata.pdf cover the two claims on the feature list that need fixtures of their own, character encodings and metadata extraction.
Four Makefile targets and no aggregate to run them
The Makefile is four targets long, and none of them is called test and none depends on the others:
install-dev-tools:
	composer update --working-dir=dev-tools

run-php-cs-fixer:
	dev-tools/vendor/bin/php-cs-fixer fix $(ARGS)

run-phpstan:
	dev-tools/vendor/bin/phpstan analyze $(ARGS)

run-phpunit:
	dev-tools/vendor/bin/phpunit $(ARGS)
Each one takes $(ARGS), so a path or a flag passes straight through, but there is no install target that chains the setup step to the checks and nothing that runs the three checks together. A contributor therefore has to know the order without being told: the binaries have to exist under dev-tools/vendor/bin before any of the other three can do anything, and the file does not say so. Every path in it is prefixed with dev-tools/, which points at where the real dependency graph is kept and why the library's own composer.json plays no part in running the checks.
The toolchain is a second Composer project of its own
Everything the Makefile calls lives under dev-tools/ and is installed by a composer update run against that directory rather than against the library. The split has a consequence worth naming: the php-cs-fixer, phpstan and phpunit versions that decide whether a change passes are pinned in a different dependency set from the runtime dependencies the library ships to its users. Bumping one does not move the other, and a green local run says nothing about the versions a consumer ends up with. The root carries .php-cs-fixer.php for the style rules and phpstan.neon for the static analysis configuration, so the settings sit at the top while the tools that read them sit one level down. Two phpunit configuration files stand side by side, phpunit.xml and phpunit-windows.xml, which is the clearest sign in the tree that this library is expected to run its own tests on more than one operating system.
Composer is the documented path, and the fallback needs a rename
Two installation routes are offered and the first is a single line, composer require smalot/pdfparser, with the requirement that PHP 7.1 or newer is needed, a floor that has applied since v1. The second route is for anyone who cannot use Composer, and it points at a file in the repository root named alt_autoload.php-dist which includes all required files automatically when your own code includes it. The distribution suffix is the catch. The file does not ship under its bare name, so an include of alt_autoload.php fails until somebody copies it and drops the suffix, and neither the file nor the README says when that copy belongs in a project's ignore rules. Neither route mentions a runtime extension beyond PHP itself, so the decompression, charset handling and hexa and octal decoding the feature list claims all happen inside the library. The usage note and the custom configuration note in the doc folder carry the rest of the surface.
Metadata is claimed and one sample file carries the fixture
Seven items make up the feature list, and they describe a parser rather than a converter. Objects and headers are loaded and parsed, metadata such as author and description is extracted, text is taken from ordered pages, compressed documents are supported, MAC OS Roman charset encoding is supported, and hexa and octal encoding inside text sections is handled. The seventh item is not a capability but an escape hatch, create custom configurations, with a separate note in the doc folder explaining it. Nothing in the list mentions tables, images, or page layout, and no filename in samples/ suggests otherwise, because everything there is a text extraction fixture. The absence of any OCR path is consistent with that. A library that reads the text operators inside a PDF has nothing to say about a page that is a scanned image, which is a boundary the project states rather than hides.
Editorial conclusion
This is a parser with a stated scope, and the scope is text and metadata on ordinary, unlocked PDFs. If that is the job, the Composer line is short and the sample corpus will tell you more about what breaks than the feature list will. Check three things before depending on it. Read LICENSE.txt directly rather than relying on the metadata field, because the terms for a library embedded in a commercial product are decided there. Treat the v2.13.0-beta1 tag as untested, since its own release name is a call for testers. And plan for the maintenance notice, which rules out active feature development and refuses to promise that a pull request will be reviewed in a timely manner, so an upstream fix for a new document producer is not something to build a schedule around.
Frequently asked questions
What is smalot/pdfparser used for?
It is a standalone PHP package for extracting data from PDF files. It loads and parses objects and headers, extracts metadata such as author and description, and extracts text from ordered pages, including compressed documents and MAC OS Roman charset encoding.
How do you install smalot/pdfparser?
With Composer, using the line composer require smalot/pdfparser. PHP 7.1 or newer is required, a requirement that has applied since v1. If Composer cannot be used, the repository root ships alt_autoload.php-dist, which includes all required files automatically when included.
Does smalot/pdfparser handle encrypted PDFs and form data?
No. The project states that secured documents and extracting form data are not supported. The sample corpus still contains not_really_encrypted.pdf, corrupted.pdf, and two filled invoice forms, so those inputs exist as fixtures rather than as promised features.
What is the maintenance status of smalot/pdfparser?
The project text says the library is under limited maintenance, stays compatible with supported PHP versions, may accept community contributions, has no active feature development, and gives no guarantee that pull requests will be reviewed or merged in a timely manner. The newest release, v2.13.0-beta1, is a beta announced with a call for testers.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smalot-pdfparser)Star history chart for your README
[](https://hysenlabs.com/projects/smalot-pdfparser)Was this useful?