Mechanize keeps a Ruby script's session between requests
Mechanize is a ruby library that makes automated web interaction easy.
At a glance
- What is it?
- Mechanize is a Ruby library that holds cookies, redirects, link lists and visited-site history in one agent object, so a script can walk and post to a site without reimplementing HTTP state. It suits Ruby scripts that scrape or fill forms, and it deliberately does not run a browser.
- Who is it for?
- Adopt Mechanize when the target site answers plain HTTP and your script is already Ruby, and skip it for anything whose content appears only after JavaScript runs, because the library will hand you a page with the missing data and no error. Before committing, run one GET against the exact URL you need and compare its body against what a browser shows, since that single check decides the whole design.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 19 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
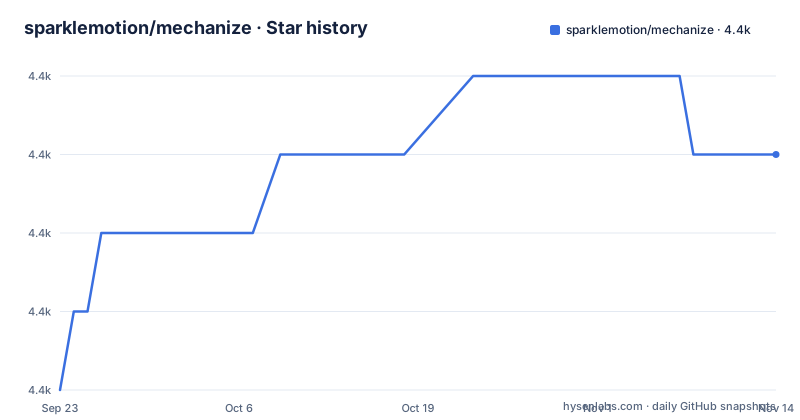
- sparklemotion/mechanize4,444 ★ · +3
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| sparklemotion/mechanize | 4.4k | 4.4k |
3 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One agent object holds the whole session
Most Ruby HTTP scripts fail in the same place: the third request to a site behaves differently from the first, and the author has to rebuild cookies by hand. Mechanize moves that state into a single agent object that persists across calls. It stores and sends cookies, follows redirects, can follow links and submit forms, populates form fields, and keeps a history of the sites it has visited. Nothing in that list needs a browser process, and nothing in it needs a session object passed from call to call. The history matters more than it first appears: a crawler wants to know which links it has already seen, and the library keeps that record for you instead of leaving it to a hash of visited URLs you write yourself.
The payoff is that a script reads as a sequence of intentions. Fetch a page, click a link, fill a field, submit, read the result. The bookkeeping between those steps is the library's job.
Ruby 2.6 and a dependency list that describes the parsing
Mechanize is distributed as a gem and its documentation lives at https://www.rubydoc.info/gems/mechanize/, which is where the project points readers who want the API reference. The stated floor is Ruby 2.6 or newer. Alongside it sit ten gems: addressable, domain_name, http-cookie, mime-types, net-http-digest_auth, net-http-persistent, nokogiri, rubyntlm, webrick and webrobots. The most recent release, v2.14.2, went out on 2026-10-26, and the license is MIT.
Read that list as a description of the mechanism rather than a shopping list. nokogiri is the HTML parser, so document handling is a real DOM rather than regex scraping. http-cookie and net-http-persistent own the cookie jar and the persistent connection pool. rubyntlm and net-http-digest_auth are there for sites behind NTLM or Digest authentication, which is uncommon and costs you two dependencies anyway. domain_name and addressable are URL handling. webrobots points to robots.txt support.
Setting up the checkout, since the README has no install line
The README gives no gem install command and no first-script example. For a user, that means the gem name is mechanize on RubyGems and the API reference is the rubydoc.info page above. The commands it does document are for people working on the library itself, and they are the only install steps written down.
From a checkout, bundler resolves the dependencies listed above:
bundle installThen the full suite runs as one rake task:
bundle exec rake testIf you are writing against Mechanize rather than in it, the same file points you to GUIDE.rdoc and EXAMPLES.rdoc for a walkthrough, and to Mechanize::TestCase for the built-in testing infrastructure.
The redirect and cookie layer decides what your script sees
Automatic redirect following is the quiet source of wrong pages. A script that asks for one URL and receives the body of another never learns the hop happened, so any assertion about the page you meant to fetch is really asserting about a different document. The README does not document a switch for turning redirect following off, which means a script author who cares about the hop has to detect it from the URL or from the history the agent keeps.
Cookie handling has the same shape. The jar is automatic. For most scraping that is exactly what you want.
Robots rules and site compatibility are the wrong-tool boundary
webrobots sits in the dependency list, so robots.txt support ships with the gem. The README does not document a configuration key for overriding it, and no option list appears anywhere in the file.
The second boundary is larger. Mechanize issues plain HTTP requests and parses what comes back. Anything rendered by JavaScript, anything behind a bot challenge, anything that only appears after a script runs in the page is simply absent from the response Mechanize sees. The examples directory lists spider.rb, proxy_req.rb, flickr_upload.rb and wikipedia_links_to_philosophy.rb, all of them HTTP-shaped work. Nothing there is a browser.
Where Capybara and a headless browser differ in approach
Capybara drives a real browser through a driver such as Selenium. That is the whole difference in approach: where Mechanize stops at the HTTP response, Capybara executes the page and reads the DOM afterwards. The cost follows from that. Mechanize runs in one Ruby process with no browser binary and no display, so a script starts quickly and a hundred-page walk is a hundred HTTP requests. Capybara needs a browser installed and running, and every page load pays for layout, scripting and rendering.
Choose Mechanize when the site answers with server-rendered HTML and the form flow is predictable. Choose a browser driver when the content you need does not exist until scripts run. Picking Mechanize for the second case produces a scraper that silently returns an empty page, not an exception.
The examples show the shape of the work, not the API
A directory of seven scripts is a better argument for what Mechanize is built for than its prose description is. spider.rb crawls outward from a starting page. wikipedia_links_to_philosophy.rb walks a link graph and stops somewhere. proxy_req.rb sends through a proxy. flickr_upload.rb uploads to Flickr.
That is the project's real range. Anything more elaborate than fetch, follow, fill and submit means writing your own request handling on top of an agent that was built for exactly those four moves.
Editorial conclusion
Adopt Mechanize when the target site answers plain HTTP and your script is already Ruby, and skip it for anything whose content appears only after JavaScript runs, because the library will hand you a page with the missing data and no error. Before committing, run one GET against the exact URL you need and compare its body against what a browser shows, since that single check decides the whole design. If the content is already in the HTML, the remaining risk is the automatic redirect and cookie layer, which the README never gives you a way to turn off.
Frequently asked questions
How do I install Mechanize for Ruby?
The README does not give a gem install command for users, so it does not document one. It points readers to https://www.rubydoc.info/gems/mechanize/ for the API reference, and the only install command it shows, bundle install, is for working on the library from a checkout.
Does Mechanize need a real browser?
No browser binary appears in the dependency list. Mechanize depends on nokogiri for parsing and on net-http-persistent for connections, so it works at the HTTP and DOM level and never executes page scripts.
What Ruby version does Mechanize require?
The README states Ruby 2.6 or newer. It also names ten runtime gems, including rubyntlm and net-http-digest_auth for NTLM and Digest authentication.
What does Mechanize track between requests?
It stores and sends cookies, follows redirects, can follow links and submit forms, populates form fields, and keeps a history of the sites it has visited.
How do I report a security issue in Mechanize?
The README asks for vulnerability reports at https://github.com/sparklemotion/mechanize/security and refers to SECURITY.md for the full policy. Ordinary bugs go to the issue tracker at https://github.com/sparklemotion/mechanize/issues.
Is Mechanize still being worked on?
The repository is not archived, and version 2.14.2 was released on 2026-10-26. The README carries no roadmap and no deprecation notice.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sparklemotion-mechanize)Star history chart for your README
[](https://hysenlabs.com/projects/sparklemotion-mechanize)Was this useful?