spatie/crawler: a PHP link crawler whose JavaScript mode borrows Chrome, and whose repository field is a documentation URL
https://spatie.be/docs/crawler
At a glance
- What is it?
- A PHP package that crawls links with Guzzle promises and, for JavaScript rendered sites, hands the work to Chrome through another package. It ships a fake method so crawl logic can be tested without HTTP, a callback checked before each request is scheduled, and a committed static analysis baseline that records what the analyser is allowed to ignore.
- Who is it for?
- spatie/crawler fits a PHP project that needs to walk a site, collect URLs or drive a crawl from callbacks, and especially fits one that wants to test that logic without touching the network. Four things to know before you adopt it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
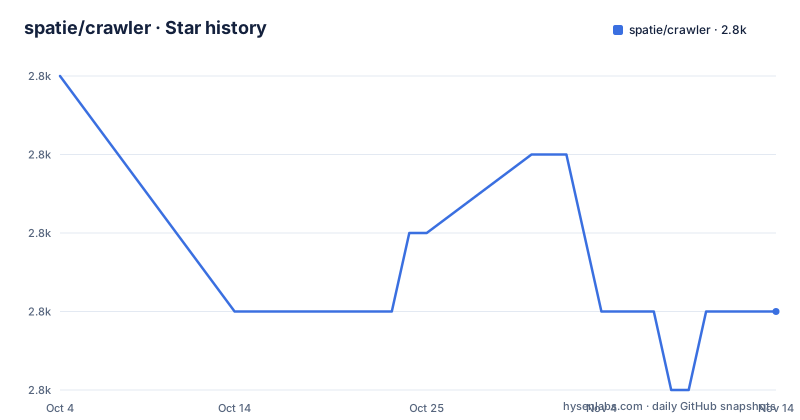
- spatie/crawler2,829 ★ · -3
| Repository | 2026-10-04 | 2026-11-13 |
|---|---|---|
| spatie/crawler | 2.8k | 2.8k |
-3 Stars in the last 40 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The description field is a documentation URL and the homepage is a blog post
Two pieces of repository metadata point away from the project itself. The description is a bare link to the documentation site, the text of the field being nothing but that address. The homepage field is an article, a blog post about building a crawler in PHP, rather than a project site or a repository mirror. Neither is wrong, and both are common, but they mean the metadata a package index or a search result shows does not describe what the package is; a reader has to open the README to learn that it crawls links on a website. The project itself keeps its documentation on an external site, with a link in the README, and it also carries a docs directory in the repository, so there are two documentation locations and the metadata points at neither.
JavaScript rendering is delegated to Chrome through another package
The feature list makes a promise and then names its dependency. Because the crawler can execute JavaScript, it can crawl JavaScript rendered sites, and under the hood Chrome and Puppeteer are used to power that, with the link pointing at Browsershot, a separate package from the same authors. Read strictly, this package does not contain a browser: rendering a page that needs it means driving an installed Chrome through that other project. That matters for deployment in two ways. A host without Chrome can still crawl ordinary pages through the Guzzle path, but the JavaScript path fails there, and the failure will look like a page with no links rather than a clear error. And the browser has to be present and compatible with the Puppeteer version in use, which is a moving target that this repository does not pin for you.
fake() lets you test crawl logic without one HTTP request
The testability story is the best designed part of this package. A crawler can be pointed at a map of URLs to HTML bodies instead of at a live site, which means the link extraction, the depth limiting and the internal-only filtering can all be exercised in a unit test with no network, no fixtures server and no flakiness:
Crawler::create('https://example.com')
    ->fake([
        'https://example.com' => '<html><a href="/about">About</a></html>',
        'https://example.com/about' => '<html>About page</html>',
    ])
    ->foundUrls();
That fake is also the cheapest way to understand the API, because the same call chain works in a test and in production: create with a URL, narrow the scope with internalOnly and a depth limit, then collect the found URLs as an array rather than reacting to each one in a callback.
The stop callback runs before a request is scheduled, not after one finishes
Stopping a crawl is expressed as a callback that receives the current crawler instance and is checked before scheduling each next request. The example shows the intended pattern, a flag captured by reference and flipped from the crawled callback:
$shouldStop = false;

Crawler::create('https://example.com')
    ->shouldStopCallback(function (Crawler $crawler) use (&$shouldStop) {
        return $shouldStop;
    })
    ->onCrawled(function (string $url) use (&$shouldStop) {
        $shouldStop = true;
    })
    ->start();
The placement is the detail that matters. Because the check happens before the next request is scheduled rather than after the last one completes, the crawl stops one request later than the callback that set the flag, which is the behaviour you want when the trigger is external state such as a rate limit or a schedule. It also means the callback is invoked repeatedly, so it should stay cheap, and that it receives the crawler itself, which is what lets it read progress rather than only a boolean.
A committed static analysis baseline records what the analyser ignores
The repository carries three files that describe its quality tooling. There is a PHPUnit configuration and a tests directory for the unit suite, and a command in the README that runs it. There is a static analysis configuration in its distributed form, plus a separate baseline file. A baseline is the interesting one: it is a committed record of the violations the analyser is currently allowed to report, which is a mechanism for adopting static analysis on an existing codebase without fixing everything first. It is also a standing debt, because a baseline that is never pruned becomes a place where real problems hide, and nothing in the README says whether this one is shrinking. The rest of the tree is conventional: an editor config, a gitattributes file, a changelog, a licence, the composer manifest, a docs directory and the source directory itself.
Version 9, with an upgrading guide sitting at the root
The current release line is 9.4, with 9.4.2 published on the same day as the last push, 9.4.1 about two weeks earlier and 9.4.0 two days before that. Two releases inside a minor line, days apart, is a normal shape for a mature package. The number itself is the more interesting part: this is the ninth major version, which in PHP ecosystem terms usually means a decade of breaking changes rather than one. The root of the repository carries an upgrading guide next to the changelog, which is the artefact that matters if you are moving from an older major, and the security reporting instructions point at a policy file through a relative path that resolves outside this repository, to the organisation's shared tree. Credits point the same way, to a contributors page one level up.
Funding is a paid product, a postcard, and a wall of postcards
The support section is unusually direct about how a free package pays for itself. It says the authors invest a lot of resources into their open source packages and that you can support them by buying one of their paid products. Then a second paragraph asks for something different: a postcard sent from your hometown, mentioning which of the packages you are using, with the address on their contact page and every postcard they receive published on a virtual postcard wall. It is an unusual funding model to state so plainly in a README, and it has a practical consequence for anyone reading the project. The package is MIT licensed and the code is free, but the money comes from elsewhere in the portfolio, so the crawler is a loss leader by design rather than a project with a funding problem attached to it.
Editorial conclusion
spatie/crawler fits a PHP project that needs to walk a site, collect URLs or drive a crawl from callbacks, and especially fits one that wants to test that logic without touching the network. Four things to know before you adopt it. The JavaScript mode is not self contained: it depends on Chrome and Puppeteer through a separate package, so a server without a browser can crawl static pages and nothing more. The callbacks are where the real work happens, and the stop callback fires before a request is scheduled rather than after one completes, which is what you want for rate limits but means the crawl will overshoot by one request. Version 9 is current and there is an upgrading guide at the root, so read it if you are moving from an older major. And the static analysis baseline is a record of known violations rather than a clean sheet.
Frequently asked questions
What is spatie/crawler?
A PHP package providing a class to crawl links on a website, using Guzzle promises to crawl multiple URLs concurrently. It can also crawl JavaScript rendered sites, with Chrome and Puppeteer powering that feature through the separate Browsershot package.
How do I test spatie/crawler without making HTTP requests?
Use the fake method, which takes a map of URLs to HTML bodies. A crawler pointed at that map can be asked for its found URLs, so link extraction, depth limits and internal-only filtering can be exercised in a unit test with no network involved.
How do I stop a spatie/crawler crawl early?
Register a shouldStop callback that receives the current crawler instance. It is checked before scheduling each next request, and the documented pattern is a variable captured by reference that the onCrawled callback sets to true.
Does spatie/crawler need Chrome installed?
For JavaScript rendered sites, yes. That capability is powered by Chrome and Puppeteer through Browsershot, a separate package, so a host without a browser can still crawl ordinary pages through the Guzzle path but cannot render them.
How is spatie/crawler tested and analysed?
The README gives one command, composer test, and the repository carries a PHPUnit configuration with a tests directory. Static analysis has a distributed configuration plus a committed baseline file, which records the violations the analyser is currently allowed to report.
How is spatie/crawler funded?
The README asks for support by buying one of the authors' paid products, and separately asks users to send a postcard naming which package they use, with the received postcards published on a virtual postcard wall. The package itself is MIT licensed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spatie-crawler)Star history chart for your README
[](https://hysenlabs.com/projects/spatie-crawler)Was this useful?