spatie/browsershot: save() picks the format and the chain picks the rest
Convert HTML to an image, PDF or string
At a glance
- What is it?
- The Spatie package wraps Puppeteer and headless Chrome in a fluent chain: input arrives through url(), html() or htmlFromFilePath(), the output format is decided by the extension you pass to save(), and the honest limits are the two dead branches the README points at when Puppeteer will not install.
- Who is it for?
- browsershot fits PHP code that already has a Chrome capable machine available, since it turns Puppeteer and a headless Chrome into a runtime requirement rather than something you can skip. It does not fit a host where Node cannot be installed, because the only escape route the docs name is the unmaintained 2.4.1 branch, and v1 sits on the abandoned PhantomJS binary.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
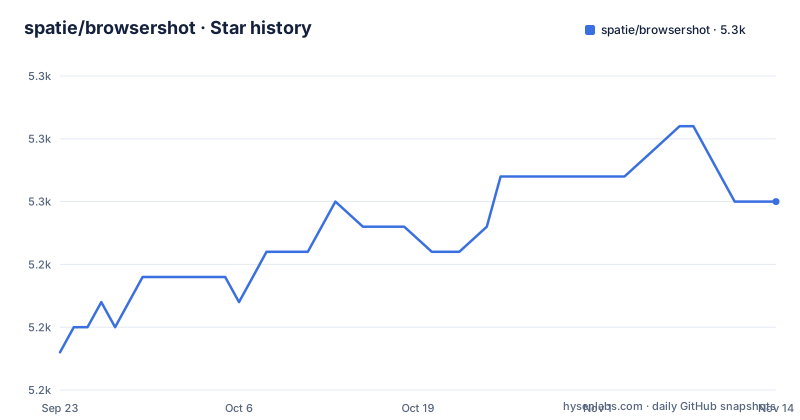
- spatie/browsershot5,250 ★ · +6
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| spatie/browsershot | 5.2k | 5.3k |
6 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The save path is the format switch
The README shows no separate pdf() or png() method. The package looks at the path you hand to save(), and a path ending in a pdf extension produces a PDF while anything else is written as an image. That is tidy until you build the filename from a variable and the extension comes out wrong.
use Spatie\Browsershot\Browsershot;

// an image will be saved
Browsershot::url('https://example.com')->save($pathToImage);
The same call with a pdf path flips the output:
// a pdf will be saved
Browsershot::url('https://example.com')->save('example.pdf');
Rendering is not done by PHP. The conversion happens behind the scenes in Puppeteer, which drives a headless build of Google Chrome, so what reads like a two line static call is really a browser launch, a navigation, and a file write. Budget for that: the call is cheap to write and expensive to run, and it inherits every problem the target page has.
url(), html() and htmlFromFilePath() are three doors into one chain
Input is where the chain offers real choices. url() takes a remote address, html() takes arbitrary markup as a string, and htmlFromFilePath() takes a path to an HTML file already on disk.
Browsershot::html('<h1>Hello world!!</h1>')->save('example.pdf');Browsershot::htmlFromFilePath('/local/path/to/file.html')->save('example.pdf');None of the three escapes Chrome. Whether the markup arrived as a string or a file, the page still has to be parsed and laid out by the headless browser, so local input saves you a network round trip and nothing more. One method breaks the pattern completely: bodyHtml() does not write a file, it returns the html of the body after JavaScript has executed, which is what you want when the deliverable is the post script DOM rather than a picture.
Browsershot::url('https://example.com')->bodyHtml(); // returns the html of the bodytriggeredRequests() returns the network log and nothing more
One method produces no image at all. triggeredRequests() returns an array of every request the page triggered, and each entry carries at least a url key you can loop over. This is the hook for a class of problem a screenshot never shows you: a page that looks right while quietly asking for something that is not there.
$requests = Browsershot::url('https://example.com')
    ->triggeredRequests();

foreach ($requests as $request) {
    $url = $request['url']; //https://example.com/
}
Read the shape before you build on it. The README example only reads a url, and the README does not show console errors, exit codes, or request status. So the array is a record of attempts, not a diagnosis. Code that tries to treat a missing entry as a failed render will be guessing, and code that assumes the list is complete will miss requests the page never issued.
newHeadless() is opt-in rather than the default
Chrome has shipped more than one headless mode, and the package does not assume you want the newer one. Calling newHeadless() inserts that mode into the chain ahead of save():
Browsershot::url('https://example.com')->newHeadless()->save($pathToImage);This matters because the two modes are not identical environments. Anything a page depends on, browser specific behaviour, window sizing, how the environment reports itself, can land differently between them, and the package leaves the choice to the caller rather than settling it once. That is a defensible position for a library wrapping a browser that keeps rewriting its own headless story, but it has a cost: a screenshot pipeline can change output on a Chrome upgrade without a single line of PHP changing. Record which mode a given asset was rendered under, and do not let the two mix in one directory.
composer test needs a global npm install and a poppler CLI
The test suite is where the environment stops being theoretical. Running it needs Puppeteer available to the machine, and the documented shortcut is a global install, plus the pdftotext CLI that ships with poppler-utils:
npm -g i puppeteer
brew install poppler-utils
composer test
The middle line is a real prerequisite, not decoration. The tests need pdftotext, which is part of the poppler-utils package, and the requirements behind it are documented in the spatie/pdf-to-text readme. The consequence lands on continuous integration: an image that has Composer and nothing else cannot run composer test, because two of the three prerequisites arrive from npm and from a system package manager rather than from composer.json. Pin both in the CI image before you wire the suite into a pipeline, otherwise the first run fails on the runner and not on your code.
The documented fallback is tag 2.4.1 and it is not maintained
The README names two escape routes and marks both as dead ends. If Node and Puppeteer cannot be installed, the suggestion is v2 of the package at tag 2.4.1, which takes a screenshot through the Chrome headless CLI instead of Puppeteer. That branch is explicitly not maintained any more, and the claim made for it is only that it should work pretty well. If headless Chrome itself is the thing that will not cooperate, the suggestion is v1, which sits on the PhantomJS binary, and PhantomJS is described as abandoned.
So the escape hatch is a frozen snapshot. A host that cannot install Node ends up on a rendering path pinned to an old tag, with no fixes flowing to it and no stated list of which Chrome versions it still understands. Note what those two paragraphs concede: this package expects you to own the browser runtime, and treats the alternatives as historical rather than maintained.
The reference lives on another site and one link points at v4
The README is a quick tour rather than a reference. It sends readers to the documentation site for the full API, and it links the testing requirements at a versioned path, spatie.be/docs/browsershot/v4/requirements, while the recent releases are 5.4.2, 5.4.1 and 5.4.0. That gap is easy to miss and awkward when you are chasing a requirement, because a page under a v4 path describes the setup for a major you are not running.
The repository itself carries `src/`, `tests/`, `phpunit.xml.dist`, `composer.json`, `CHANGELOG.md`, `LICENSE.md`, plus `bin/`, `art/`, `docs/` and a `.github/` directory. The license is MIT. Security bugs are asked for by mail to [email protected] rather than through the issue tracker, and contributions go through the shared spatie/.github CONTRIBUTING.md. Version 5.4.2 shipped on 2026-10-26, the same day as the last push to the repository.
Editorial conclusion
browsershot fits PHP code that already has a Chrome capable machine available, since it turns Puppeteer and a headless Chrome into a runtime requirement rather than something you can skip. It does not fit a host where Node cannot be installed, because the only escape route the docs name is the unmaintained 2.4.1 branch, and v1 sits on the abandoned PhantomJS binary. Before you commit, check three things: whether global Node and Puppeteer exist on the machine, which Chrome headless mode your pages were validated against, and what you will do when a render goes wrong, since the README shows a request list but no error report.
Frequently asked questions
dompdf vs browsershot
Nothing in this repository makes that comparison, and no benchmark is published here. What is documented is that spatie/browsershot renders through Puppeteer driving headless Google Chrome, and that a save path ending in a pdf extension writes a PDF while other extensions write an image.
gotenberg vs browsershot
The repository says nothing about gotenberg or any other external renderer. The only alternatives it names are its own older branches: v2 at tag 2.4.1, which screenshots through the Chrome headless CLI and is no longer maintained, and v1, which relies on the abandoned PhantomJS binary.
How do I run browsershot for the first time?
The README's instructions cover the test dependencies rather than a full install walkthrough. Puppeteer comes from a global npm install and pdftotext from poppler-utils, then `composer test` runs the suite, while the full API reference is hosted at spatie.be/docs/browsershot. The first render itself is one chain: `Browsershot::url('https://example.com')->save($pathToImage)`.
What does browsershot do when a page needs Chrome's new headless mode?
You opt in by calling newHeadless() on the chain before save(), for example `Browsershot::url('https://example.com')->newHeadless()->save($pathToImage)`. It is not the default, so a pipeline has to choose which mode it renders under and keep that choice consistent.
Can browsershot work on a server without Node or Puppeteer?
Not through the current code path, because rendering happens in Puppeteer with a headless Chrome. The fallback named for that case is v2 at tag 2.4.1, which uses the Chrome headless CLI, and it is stated to be no longer maintained even though it should still work.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spatie-browsershot)Star history chart for your README
[](https://hysenlabs.com/projects/spatie-browsershot)Was this useful?