Spider starts with HTTP and only opens Chrome when a page needs it
Get web data for AI agents and LLMs - fast, efficient, and reliable with Rust
At a glance
- What is it?
- A concurrency-first Rust crawler that streams pages as they arrive and takes concurrency limits, depth and delay through a builder rather than a config file. Its newest release is v2.52.2 from March, six months behind the last push, and thirteen of the twenty-three example programs carry Chrome in the filename.
- Who is it for?
- Spider fits teams feeding the open web into a RAG pipeline or an agent, and the streaming subscribe API is the part that changes how you write the consumer. Decide before you start whether you want the hosted path, because Smart mode routes through proxies and escalates to a stealth scrape on pages that resist, and that is a commercial service with its own key rather than a library setting.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
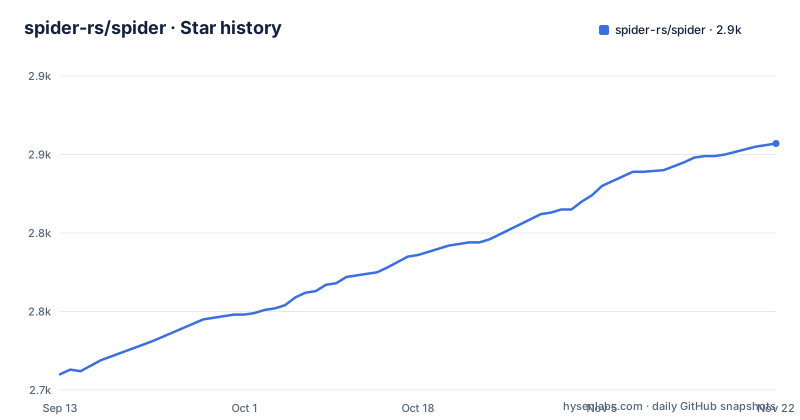
- spider-rs/spider2,857 ★ · +147
| Repository | 2026-09-13 | 2026-11-22 |
|---|---|---|
| spider-rs/spider | 2.7k | 2.9k |
147 Stars in the last 70 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The newest tag is v2.52.2 from March, six months behind the last push
The release record is a short, dated list. v2.48.2, titled Parallel Crawl Backends, was published on 2026-03-25, and v2.48.4 went out the same day at 21:01Z against 16:23Z for the rc-era pair. The newest published release is v2.52.2 on 2026-03-31, titled CLI authenticate for Spider Cloud. The last push to the repository was on 2026-10-01.
So roughly six months of commits sit above the newest tag, and the tag names themselves jump from 2.48 to 2.52 without the intervening versions appearing in the release list. If you pin a version, you are pinning to something published at the end of March, not to the state of the tree. A CHANGELOG.md sits at the repository root and is the place to check what moved after that date, since the README does not describe the unreleased state at all.
HTTP first, Chrome only on the pages that need it
The central design decision is that the crawler does not drive a browser by default. It runs HTTP-first and launches headless Chrome only when a page needs JavaScript, and both paths stream, so pages come back as they are fetched rather than batched at the end.
Two entry points follow from that. crawl() is the plain HTTP walk, and for JavaScript-heavy sites the chrome feature is enabled and crawl_smart() is called instead, which tries HTTP first and only launches Chrome where it is needed. The local example shows the consumption shape, a tokio task receiving from a subscription with a buffer of 16 and printing the status code and URL of each page, then unsubscribing after the crawl returns. The stated goal is that the same API drives one async task or a distributed worker fleet without the concurrency model changing between them.
Smart mode escalates to a stealth scrape on pages that resist
The hosted path is a feature flag and a config object. Depending on spider = { version = "2", features = ["spider_cloud"] }, a SpiderCloudConfig takes a key and a mode, with Smart described as proxy by default and stealth scrape when blocked. The README frames the reason plainly: the hard part of crawling at scale is not the code but the proxies, headless browsers and constant anti-bot churn, all of which the service runs behind the same API, so a local prototype moves to managed infrastructure with one config change.
That framing is worth weighing rather than absorbing. The engine's own vocabulary here is escalation: proxies first, a stealth scrape only where a page fights back. Against that, the builder carries with_respect_robots_txt as a plain option, along with with_subdomains and with_user_agent, so whether a crawl stays inside a site's stated boundaries is a decision you make in configuration rather than a default the engine enforces. A free API key is available without a card, so the cost of finding out is low.
Six install routes for one engine
The install table maps six audiences onto one codebase: cargo add spider for the Rust library, cargo install spider_cli for the command-line tool, npm i @spider-rs/spider-rs for Node.js, pip install spider_rs for Python, cargo install spider_mcp for an MCP server aimed at editors such as Claude and Cursor, and spider.cloud for managed crawling.
Only the first five are the open source artefact. The MCP server is the newest-looking surface in that list, and it matches the repository description, which frames the project as a way to get web data for AI agents and LLMs rather than as a general crawler. The stated uses follow the same line: feeding the open web into vector stores for RAG pipelines, monitoring sites for SEO and price changes, exporting pages as Markdown, JSON or WARC, and driving headless Chrome for AI browsing agents.
The workspace patches the crates.io spider with its own path
Cargo.toml declares nine published members in one workspace: spider, spider_worker, spider_cli, spider_utils, spider_agent, spider_agent_types, spider_agent_html and spider_mcp, plus examples and benches marked internal, under resolver 2. Then it does something unusual. A patch section redirects the crates.io spider to the local path, with a comment saying this unifies the external spider_transformations crate onto this workspace's spider instead of pulling a second copy from crates.io, removing a duplicate spider compile and keeping the whole tree on one patched, audited quick-xml.
The same comment notes that patch sections are local-only and ignored on publish. So the unification is a property of building this repository, not of what consumers get from crates.io, and a project depending on spider_transformations will resolve that dependency differently depending on whether it is inside this workspace. The rest of the tree follows the same shape: spider_worker/ for the fleet side, spider_agent*/ for the agent types, and spider_cli/ and spider_mcp/ as separate binaries.
Live network tests are opt-in through an environment variable
Two commands cover the whole suite, and the split between them is deliberate:
cargo test -p spider                  # unit tests
RUN_LIVE_TESTS=1 cargo test           # live network tests
Everything the default run exercises stays local, and anything that reaches the network waits for RUN_LIVE_TESTS=1 to be set in the environment. For a crawler that is the only sensible arrangement, since a default cargo test on a CI machine would otherwise depend on someone else's web server being up. The flip side is that a green default run says nothing about whether pages still parse, which is exactly the part most likely to rot.
The repository also carries default.nix, a .cargo/ directory, a release.sh at the root and a committed CLAUDE.md, so the build has a Nix path and a release script rather than living entirely in the Cargo manifests.
Thirteen of the twenty-three examples carry Chrome in the filename
The examples directory is where the real feature surface shows. Of the twenty-three Rust programs named for it, thirteen have Chrome in the filename, and they split into local and remote variants rather than being variations on one theme.
Local ones cover chrome.rs, screenshots with and without a config, a viewport example, web automation, a single-page example and one that sends to a browser. Remote ones are the more interesting group: chrome_remote.rs, chrome_remote_logrocket.rs and chrome_remote_tls.rs each attach to a browser somewhere else, with the names naming what is being pointed at. Alongside them sit cache_remote_skip_browser.rs, cache_chrome_hybrid.rs and chrome_proxy_dns_shortcircuit.rs, which imply caching, hybrid HTTP and Chrome, and a short-circuit for proxy DNS. Two filenames are tests rather than demos, chrome_nxdomain_test.rs among them.
Limits are builder arguments, not a configuration file
Every knob is a method on the builder, and the README's own example lists them with the value each one takes:
let mut website = Website::new("https://example.com")
    .with_limit(50)                    // concurrent requests
    .with_depth(10)                    // how deep to follow links
    .with_delay(500)                   // pause between requests (ms)
    .with_respect_robots_txt(true)
    .with_subdomains(true)
    .with_user_agent(Some("MyBot/1.0"))
    .with_stealth(true)
    .build()
    .unwrap();
with_limit is concurrency, with_depth is how far the crawler follows links, and with_delay is the pause between requests in milliseconds. with_subdomains decides whether the walk leaves the host it started on, and with_user_agent sets the identity string. There is no configuration file in this picture: the run is the code, which is convenient for tests and awkward for an operator who wants to change a limit without a rebuild. The full option reference lives in the Configuration docs on docs.rs.
Editorial conclusion
Spider fits teams feeding the open web into a RAG pipeline or an agent, and the streaming subscribe API is the part that changes how you write the consumer. Decide before you start whether you want the hosted path, because Smart mode routes through proxies and escalates to a stealth scrape on pages that resist, and that is a commercial service with its own key rather than a library setting. If you run it locally, set with_limit, with_depth and with_delay deliberately and turn on with_respect_robots_txt if your targets expect it. Note the release lag before pinning: the newest tag is v2.52.2 from 2026-03-31 while the last push was on 2026-10-01.
Frequently asked questions
How do I install the Spider crawler?
There are six routes: cargo add spider for the Rust library, cargo install spider_cli for the command-line tool, npm i @spider-rs/spider-rs for Node.js, pip install spider_rs for Python, cargo install spider_mcp for an MCP server, and spider.cloud for managed crawling.
Does Spider render JavaScript on every page it visits?
No. It runs HTTP-first and launches headless Chrome only when a page needs JavaScript. For JavaScript-heavy sites you enable the chrome feature and call crawl_smart(), and both the HTTP and Chrome paths stream pages as they are fetched.
Do I need a Spider Cloud account to crawl with Spider?
No, running locally needs no key and no service. The cloud path adds the spider_cloud feature plus a SpiderCloudConfig holding a key and a mode, where Smart routes through a proxy first and escalates to a stealth scrape only on pages that resist.
What do with_limit and with_depth control in Spider?
with_limit sets the number of concurrent requests and with_depth sets how deep the crawler follows links, with with_delay pausing between requests in milliseconds. with_respect_robots_txt, with_subdomains and with_user_agent sit in the same builder.
How do you run the Spider test suite?
cargo test -p spider runs the unit tests. Live network tests are opt-in and need RUN_LIVE_TESTS=1 set in the environment, so a default run stays local and makes no network calls.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spider-rs-spider)Star history chart for your README
[](https://hysenlabs.com/projects/spider-rs-spider)Was this useful?