LearnOpenCV is one directory per article, and its Code column is empty for recent posts
Learn OpenCV : C++ and Python Examples
At a glance
- What is it?
- LearnOpenCV is the code behind the LearnOpenCV.com blog, organised as one directory per article at the repository root. That suits reading one article and cloning the whole history to do it, and it means the README's own table of posts is the only index, with several recent entries carrying no code link at all.
- Who is it for?
- LearnOpenCV fits someone following one LearnOpenCV.com article who wants to see the C++ or Python behind it, and who is willing to read the article for its own dependency list. It does not fit a team looking for a maintained library to depend on, because it is a set of per-article example directories with no version contract, and the releases are topic snapshots named with dates rather than versions.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
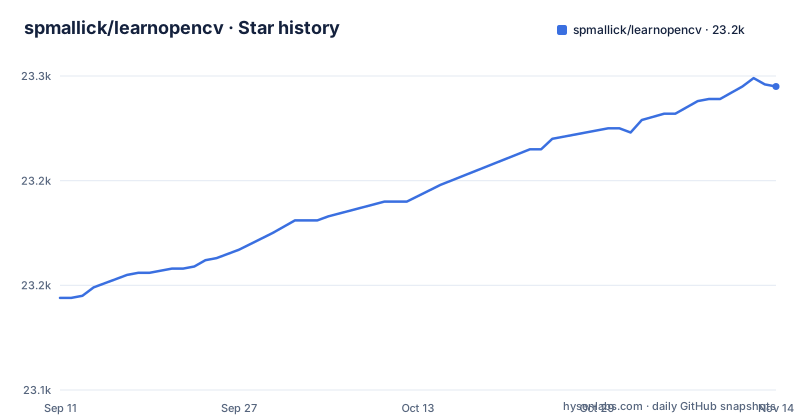
- spmallick/learnopencv23,246 ★ · +102
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| spmallick/learnopencv | 23.1k | 23.2k |
102 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The root is a hundred topic directories with no naming convention
Look at the top level and there is no project there. It is a .gitignore, a README, and a long flat list of directories named after article topics: Contour-Detection-using-OpenCV, Background-Subtraction, ConvexHull, CameraCalibration, ColorSpaces, BlobDetector, BatchNormalization, Colorization, AlphaBlending, ComfyUI, CI and then a couple of hundred more.
Each directory is an article's code, and whatever it needs, it brings with it.
The naming is inconsistent in a way that has practical effects. Some directories use hyphens, some underscores, some run words together. Automating anything over this root, sorting it, generating a table or matching a directory name to a slug, means handling three conventions at once.
The consequence for a reader is the main cost of the layout. To get one article's code you clone the entire history of a repository with a few hundred directories, and there is no way to fetch just that article's files except by checking out the one path you need.
The post table has a Code column, and recent rows leave it blank
The README's index is a two column table of blog posts and code, and reading it closely is the fastest way to understand what this repository is.
Most rows are marked Updated and link to a directory. SAM-3 has a code link, Object Tracking using OpenCV has one, Hough Transform, Otsu's Thresholding, Homography, Hu Moments, Color Spaces and Face Detection with OpenCV and Dlib all have one.
Then there are the rows with nothing in the second column at all. Train RF-DETR for Instance Segmentation with GPT-6 Astra has an empty Code cell. So does How 10x AI Engineers Train Models for Production. Those two are among the newest entries in the table.
So for a meaningful share of recent articles, the repository is not where the code lives. That matters if you are here to follow an article rather than to browse: the post list is the index, and one cell of it is often blank.
Releases are topic snapshots named with dates, not semantic versions
The release list has three entries and none of them is a version number.
The newest is sam-3-1-api-notebooks-2026.09.20, titled SAM 3.1: native tracking and Meta Model API notebooks. Before it are sam-3-1-video-tracking-2026.08.30 and a second pass on the same topic, sam-3-1-video-tracking-2026.08.30-r2.
The pattern is a slug of the topic, a date, and a revision suffix where a topic needed a second pass. There is no v1, no minor version, no compatibility statement, because a tag here marks the state of the tree on the day one topic's notebooks were finished.
The consequence is that you cannot pin this repository the way you pin a dependency. If you want the code as it was when a particular article was published, a tag named after an unrelated topic is the closest thing available, and the article's own date is a better reference than the tag.
Activity itself is current: the last push was on 2026-10-22, about a month after the newest release.
The README is half teaching archive, half consulting pitch
The first line is the honest description. This repository contains code for Computer Vision, Deep learning, and AI research articles shared on the blog LearnOpenCV.com.
The next section is a different register. LearnOpenCV is maintained by BigVision.AI, described as a computer vision and AI consulting company that helps organisations design, build, optimize and deploy production-ready AI solutions, with expertise in computer vision, deep learning, multimodal AI and edge deployment. It closes with an invitation to talk with their expert AI solution builders, and the link carries a utm_source parameter identifying the repository as the referrer.
That is not a criticism of the code, but it is a fact about what kind of artefact this is. It is a company's published example library with a documentation purpose, not a community dependency, and nothing in the repository is positioned as something you should import.
It also changes how you evaluate a directory here. Examples that accompany an article are written to be read once, which is a different standard from a library you are expected to call.
The primary language is a notebook, and the C++ examples need external tools
The repository's primary language is recorded as Jupyter Notebook, and the description promises C++ and Python examples. Both are true, and the dependency story sits in the articles rather than anywhere central.
The table names the tools per example. The barcode and QR code scanner uses zbar together with OpenCV. OCR text recognition uses Tesseract and OpenCV. Face detection compares OpenCV with Dlib. Stereo depth estimation and human pose estimation are described as C++ and Python pairs.
Each of those needs something installed that is not OpenCV and not Python: a barcode library, an OCR engine, a face-landmark library, plus whatever the deep learning examples in the deeper directories require.
In practice, you read the article, you install what that article names, and you run the code in the directory it points at.
Nothing is pinned, and the article titles reference specific versions
The oldest entries are OpenCV fundamentals. Read, Display and Write an Image, Cropping, Resizing, Color Spaces, Edge Detection, Convex Hull, Hu Moments, Rotation Matrix to Euler Angles.
The newest are not. The table includes Object Detection with OpenCV 5 in C++ covering YOLO26 pose and segmentation, a post on SAM-3, one on MiniCPM-o 4.5 described as a 9B model, one on VGGT versus VGGT-Omega for feed-forward 3D reconstruction, and one on training RF-DETR with GPT-6 Astra.
So the titles name a major version of OpenCV, several specific model releases and a specific large language model, and the README table does not state which versions each example expects.
The consequence for a reader is straightforward. Following a recent article may require a version of OpenCV or a model your environment does not have, and the README table does not tell you which version an article was written against.
There is no test suite to run, and quality is per directory
What is absent is as informative as what is there. There is no .github directory at the root.
There is a directory named CI in the listing, and in a repository with this many article topics it is far more likely to be an article about continuous integration than a pipeline definition, which is exactly the ambiguity a flat article-per-directory layout creates.
So there is no way to ask this repository whether its examples still work. Not by running a suite, and not by reading a badge, because nothing reports on the directories.
For an engineer, that sets the bar for using any of it. The value is in the code as published alongside an explanation, and the verification is yours: you run the example against the OpenCV and libraries you actually have, and if the article named a version you do not have, you find out at the first import error rather than from anything the repository told you up front.
Editorial conclusion
LearnOpenCV fits someone following one LearnOpenCV.com article who wants to see the C++ or Python behind it, and who is willing to read the article for its own dependency list. It does not fit a team looking for a maintained library to depend on, because it is a set of per-article example directories with no version contract, and the releases are topic snapshots named with dates rather than versions. Verify first whether the article you care about has a code directory at all, since the README's table leaves the Code cell empty for several recent posts.
Frequently asked questions
What is LearnOpenCV?
It is a repository containing code for Computer Vision, deep learning and AI research articles shared on the LearnOpenCV.com blog, with the description promising C++ and Python examples. Each article's code sits in its own directory at the repository root.
Does every LearnOpenCV blog post come with code?
No. The README's table has a Code column, and several recent entries leave it empty, including the RF-DETR instance segmentation post and the post on how AI engineers train models for production. Older entries are marked Updated and link to a directory.
How do you install the LearnOpenCV examples?
The README is organised as a table of blog posts and code directories rather than a setup guide. Individual articles name their own tools, such as zbar with OpenCV for the barcode and QR scanner, Tesseract and OpenCV for OCR, and Dlib for face detection, so the requirements live in each article rather than in the repository.
Who maintains LearnOpenCV?
The README states that it is maintained by BigVision.AI, described as a computer vision and AI consulting company, and that the repository holds code for articles shared on the LearnOpenCV.com blog. The same section carries a link inviting readers to discuss projects with that company's services.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spmallick-learnopencv)Star history chart for your README
[](https://hysenlabs.com/projects/spmallick-learnopencv)Was this useful?