Spring AI: the Spring Boot version pairing is the first thing to check
An Application Framework for AI Engineering
At a glance
- What is it?
- Spring AI applies Spring's portability and modular design to AI model providers and vector stores, with a portable API across both and model-specific escape hatches. The 2.x line requires Spring Boot 4.x, and the 1.1.x line is the one paired with Boot 3.5.x.
- Who is it for?
- Adopt Spring AI if your application is already a Spring Boot service and you want one portable API across model providers rather than a provider SDK per vendor.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
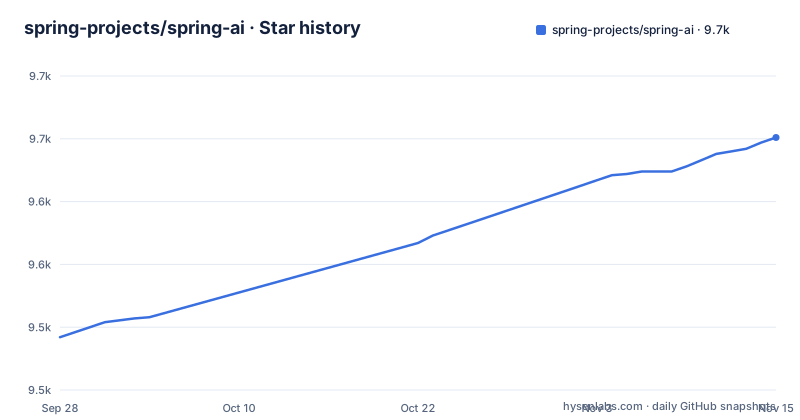
- spring-projects/spring-ai9,651 ★ · +159
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| spring-projects/spring-ai | 9.5k | 9.7k |
159 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Boot version pairing decides whether your build works, and it is stated in three lines
The getting-started section leads with compatibility rather than with a code sample, and that ordering is the most useful thing on the page.
Spring AI 2.x.x, on the main branch, pairs with Spring Boot 4.x. Spring AI 1.1.x, on its own 1.1.x branch, pairs with Spring Boot 3.5.x.
That is two version lines on two branches, tied to two Boot generations. The README does not say how a mismatch fails, so check the pairing first.
The recent releases are v2.1.0-RC1 and v2.0.2 on 2026-10-23 and v2.1.0-M1 on 2026-09-25, so the 2.x line is actively moving. The 1.1.x branch is where the Boot 3.5.x pairing lives.
What the README does not do is tell you when 1.1.x stops receiving fixes, so if you choose the older pairing for Boot compatibility, the end-of-support question is one you have to answer from the project's release policy rather than from this page.
Portability is the goal, and model-specific escape hatches are how it stays honest
The stated goal is to apply Spring ecosystem design principles such as portability and modular design to the AI domain, and to promote strongly-typed data structures and APIs as the building blocks of an application.
Portability shows up as a portable API across providers, and the provider list is long: Anthropic, OpenAI, Amazon Bedrock, Google, Ollama, Mistral AI, DeepSeek and more. Across model types the coverage runs to chat, embedding, text to image, audio transcription, text to speech and moderation.
The detail that makes portability usable is the access to model-specific features through chat options. A purely portable API that only exposes the intersection of what every provider can do would be portable and useless, because the differentiating capability of any given model sits outside that intersection. Exposing the escape hatch alongside the portable surface is what stops the abstraction from becoming a ceiling.
Both synchronous and streaming options are covered, which is stated rather than demonstrated in the overview. For a library whose selling point is that you can switch providers, that pairing matters: a streaming-only provider or a sync-only interface would each break the claim in practice.
The framing of the problem is also worth quoting, because it is narrower than the marketing around it usually is: connecting your enterprise data and APIs with the AI models. This is an integration layer for systems that already exist, not a framework for training or hosting models.
The vector store list and the metadata filter API are where portability is hardest
Twenty named vector store providers, and the same portability claim applies to them as to models: Amazon Bedrock Knowledge Base, Amazon S3, Apache Cassandra, Azure Vector Search, Chroma, Couchbase, Elasticsearch, GemFire, MariaDB, Milvus, MongoDB Atlas, Neo4j, OpenSearch, Oracle, PostgreSQL with PGVector, Pinecone, Qdrant, Redis, Typesense and Weaviate.
A list that long is a maintenance surface, not a feature. Each adapter tracks a provider's own API, and a provider that changes its behaviour produces a bug in this project's adapter rather than in your code.
The metadata filter API is called out as novel and SQL-like, and it is the piece to evaluate. Vector search almost always needs filtering by document metadata alongside the nearest-neighbour query, and the usual outcome is that each provider's filter syntax leaks into application code. A SQL-like filter that translates across the listed backends is the specific capability that would let you switch a vector store without touching queries, and if it holds up it is a stronger argument for this framework than the provider count itself.
The counter-consideration is that a lowest-common-denominator filter cannot express everything every provider supports. Provider-specific filter capabilities are where a portable layer gets thin, so the question for a specific project is whether your queries stay inside the portable subset.
The module layout tells you what the team considers separable
The repository root lists the modules, and the names are a map of the design. There is spring-ai-model for the abstractions, spring-ai-client-chat for the chat client, spring-ai-commons, spring-ai-rag, spring-ai-vector-store, and advisors/ for the advisor mechanism.
Then there are the ones that show where the boundaries are drawn. memory-repositories/ is separate from spring-ai-client-chat, which tells you conversation memory is a pluggable concern rather than something baked into the client. starters/ and auto-configurations/ are separate again, which is how Spring Boot auto-configuration is normally factored and is what lets start.spring.io offer a starter per model and per vector store.
Four modules are about testing and verification rather than runtime. spring-ai-test, spring-ai-integration-tests, spring-ai-spring-boot-testcontainers and spring-ai-spring-boot-docker-compose. Testcontainers support in particular tells you integration testing against real backends is a supported path rather than something you assemble.
Two more are worth naming. spring-ai-retry is its own module, which means retry behaviour around model calls is a designed concern rather than something every application reimplements, and that matters because a rate-limited model provider is a normal condition rather than an error. spring-ai-bom is a bill of materials, which is how you keep a dependency set with many providers on one version.
There are also two settings files at the root, commercial-settings.xml and release-train-settings.xml, alongside the ordinary settings.xml. Those are build and release plumbing rather than anything you use, but their presence is a useful signal that this project ships from a coordinated release train rather than module by module.
Structured output, tool calling and MCP are three different bets
Structured output maps model output to POJOs, and in a strongly-typed framework that is the capability that removes the largest source of integration code: parsing prose into an object. It depends on whatever structured-output support the provider offers, which is one of the places the portable API meets a provider difference.
Tool calling lets a model request execution of client-side tools, which the documentation frames as accessing real-time information as required. The interesting consequence is the security boundary it creates. A model deciding to invoke a function means your application is executing code chosen by a language model, driven by input that may be user-supplied or retrieved from a document. Nothing in this description describes a permission model, a confirmation step or an allowlist, so the control is yours to build.
MCP support is first class rather than a plugin, delivered through Boot starters and Java annotations, with STDIO, SSE and Streamable-HTTP transports. The description covers both directions: consuming MCP servers, and exposing Spring services to the AI ecosystem. That is a wider surface than most integrations take on, and it is the feature most worth deciding about deliberately rather than by default, because exposing a service to an MCP client means deciding what that client is allowed to reach.
The Advisors API sits alongside these and is described as encapsulating recurring generative patterns and transforming data sent to and from models. Conceptually it is an interceptor chain for prompts and responses, which is the natural place for logging, redaction or caching in an application that already has a filter chain it understands.
What the README does not tell you, and what to check before committing
Four gaps worth naming, each of which is a question to answer elsewhere.
Cost and latency are absent. The README mentions Observability only as providing insights into AI-related operations, and says nothing about token accounting, rate limits or what happens when a provider is degraded.
Capability parity is absent. The provider list and model-type list say what is supported, not which provider supports which model type at which feature level. The documentation links per capability are where that lives.
The upgrade notes exist as a separate document and are not summarised. With two maintained version lines and pre-release tags already in the 2.x stream, the notes are the thing to read before a Boot upgrade, not after.
The recent releases include v2.1.0-M1 and v2.1.0-RC1, a milestone and a release candidate. Pre-release tags are for early feedback, so pin a release rather than track main.
What you can verify locally is quick. The build needs no setup beyond the wrapper:
./mvnw clean installThat builds all modules, runs the unit tests and publishes to your local Maven repository, which is enough to see whether the module set compiles on your JDK before you invest in reading the API surface. The repository is not archived, was last pushed on 2026-11-02, and is licensed Apache-2.0 with the text in LICENSE.txt, and it lives under the spring-projects organisation.
Where Spring AI sits against LangChain4j and against a vendor SDK
LangChain4j is a common comparison for a Java team. This project centres on Spring's own design vocabulary: typed data structures, portable interfaces across providers, Boot auto-configuration and starters, and an interceptor-style advisor chain.
The practical question that separates them is whether your application is already Spring Boot. If it is, the auto-configuration, the starters and the existing dependency injection are not features you evaluate but ones you already have, and the portability story is the whole argument. If it is not a Spring application, adopting this framework to get provider portability means adopting Spring Boot to get it.
Against a vendor SDK, the trade is portability across providers versus direct access to one vendor's API. The counter-argument is that the escape hatches exist precisely so you can stop paying the portability premium when a specific model is better than the abstraction. A framework that lets you use the portable API for most calls and the vendor-specific option for the two calls that matter is a different proposition from one that forces a choice.
The third option is writing thin adapters over two or three providers yourself. It is a real amount of code, it grows every time a provider is added, and it is entirely reasonable when the provider set is stable and small.
Editorial conclusion
Adopt Spring AI if your application is already a Spring Boot service and you want one portable API across model providers rather than a provider SDK per vendor. Do not adopt it on the strength of the feature list without checking the Boot pairing first, because the 2.x line requires Spring Boot 4.x while the 1.1.x branch is the one that pairs with Boot 3.5.x. Before you commit, read the upgrade notes, run ./mvnw clean install to see the module set build cleanly on your machine, and decide deliberately whether MCP support and the Advisors API are requirements or features you are taking by default.
Frequently asked questions
What is Spring AI used for?
Spring AI is an application framework for AI engineering in Java, providing Spring-friendly APIs and abstractions for building AI applications. Its stated goal is to apply Spring's portability and modular design principles to the AI domain, connecting enterprise data and APIs with AI models through strongly-typed data structures.
Which Spring Boot version does Spring AI 2.x need?
Spring AI 2.x.x on the main branch requires Spring Boot 4.x, while Spring AI 1.1.x on the 1.1.x branch pairs with Spring Boot 3.5.x. The pairing is the first thing to check.
Does Spring AI support MCP?
Yes, as first-class support rather than a plugin, delivered through Boot starters and MCP Java annotations, with STDIO, SSE and Streamable-HTTP transports. It covers both consuming MCP servers and exposing Spring services to the AI ecosystem.
How do I build Spring AI from source?
Run ./mvnw clean install, which builds all modules, runs the unit tests and publishes the artifacts to your local Maven repository. The build does not require a separate Maven installation, and the project ships with a Maven wrapper at the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spring-projects-spring-ai)Star history chart for your README
[](https://hysenlabs.com/projects/spring-projects-spring-ai)Was this useful?