SqlKata QueryBuilder: new database compilers are declined by policy
SQL query builder, written in c#, helps you build complex queries easily, supports SqlServer, MySql, PostgreSql, Oracle, Sqlite and Firebird
At a glance
- What is it?
- SqlKata is a query builder for C# that produces SQL rather than objects, with execution support split into an optional second package. The API examples read like a chain of clauses ending in Get, First or Paginate, and the FAQ contains the most quotable sentence in the project: contributions that add a compiler for a new database are turned down on purpose.
- Who is it for?
- SqlKata fits a team that wants to generate SQL it can read, hand to a reporting tool, or store as text, and that does not want an object mapper deciding what its queries look like. The design is legible: a fluent chain that ends in a terminal call, writes that return affected row counts, and a database abstraction you can compile to a string without touching a connection.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 25 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
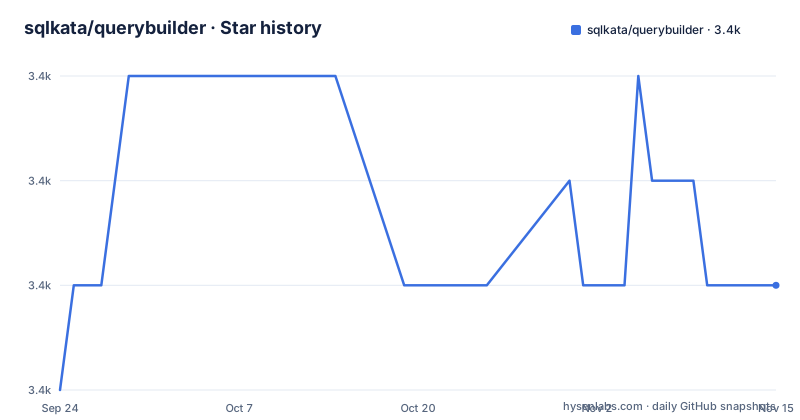
Star history
- sqlkata/querybuilder3,382 ★ · +1
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| sqlkata/querybuilder | 3.4k | 3.4k |
1 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two packages, and only one of them touches a database
The distribution is split in a way that matters for dependency hygiene.
$ dotnet add package SqlKata
$ dotnet add package SqlKata.Execution # (optional) If you want the execution support
The first package builds queries. The second runs them, and the readme says it executes queries with Dapper. The second line is marked optional, and the setup example says which package owns which type: the query factory that your code actually calls comes from the execution package, while the compiler is the part that turns a query into SQL text.
So there is a supported configuration in which a project uses this library purely as a SQL generator, with no connection anywhere in the process. That is what makes it usable in a reporting service, a migration script, or a tool whose output is a query string rather than a result set.
The claim in the introduction is that the library is framework-agnostic, and the packaging supports it: nothing in the two packages names an application framework, and the execution package delegates the data access to an existing micro mapper rather than owning a connection.
The terminal call is the one that decides what comes back
The examples are all one chain, and they differ in the last method.
Get returns everything the chain selects. First returns a single record. Paginate returns a page object rather than a flat list, and that page has a List property holding the rows and a Next method returning the following page, so paging is a chain of page objects instead of an offset argument.
Before the terminal call the chain is ordinary fluent composition: a table name, where clauses taking a column and a value, a conditional shorthand for a boolean column, ordering with a direction, a limit, a select list with an alias, and a join taking a target table and two column names. Where a related record should be attached rather than joined, an include takes another query and assumes a foreign key column on the table.
The results are read through dynamic properties rather than a mapped type. In the join example the loop reads a title and an aliased author name off each returned row, and in the include example the returned shape gains a nested object for the related record.
That is the whole API surface in one paragraph: build, terminate, read dynamically.
Conditionals are part of the chain, not a branch around it
One example is worth reading closely because it shows the intended way to handle a filter that only sometimes applies.
The code computes whether today is Friday, then passes that boolean into a When method on the query chain along with an action that adds an in-list condition on a category column. If the flag is false the action does not run and the query is unchanged.
This is a different shape from building the filter conditionally in your own code and appending it, and it is what makes the chain readable when a query has optional parts. The other shortcuts follow the same idea: a method for a boolean column that is set true, and an in-list method that takes an array of values.
The general form takes a column and a value, and the examples chain two of them to express a conjunction. Note what is absent: there is no lambda taking a query object, so the filtering vocabulary is the set of methods this library defines rather than anything you can express with an arbitrary predicate.
For a team that reads generated SQL often, that constraint is the trade. The vocabulary is small enough to predict the output.
Writes return a count, which is how you know it is not an ORM
The three write examples are as short as the read ones.
An insert passes an anonymous object of column and value pairs and returns the number of affected rows. An update adds a where clause to a single record and otherwise takes the same anonymous object. A delete takes a where clause and returns the count. The variable the examples assign is an integer, and the readme labels it as the affected count.
That single detail fixes the category. There is no change tracking, no unit of work, no lazy loading, no identity map and no migration tool anywhere in the examples. A row is written when you write it, and what comes back is a number.
The dynamic result access from the read side completes the picture: you get back something whose properties are resolved at runtime, which is convenient for a report and unhelpful for a domain model.
So the honest summary is that this is a query builder with an optional execution layer, deliberately short of the object mapping that an ORM exists to provide. If you want entities, this is the wrong category of library, and the readme says as much by not pretending otherwise.
The project declines new compilers, and says why
Two questions in the readme's FAQ set the policy for the database layer, and both answers are blunt.
The first is why a database is not supported. The answer is that supporting every available vendor is impossible, which is why the project focuses on the major ones, and readers are encouraged to create their own compiler for their database.
The second is whether new compilers are accepted. The answer is no, with the stated reason that accepting them would add overhead for the project contributors, and that the preference is to improve the quality of the existing compilers instead.
That combination is unusual and worth stating plainly, because it changes what contributing means here. Adding support for a database is not a pull request this project will merge, so anyone filling that gap maintains a compiler outside the repository, without upstream fixes, and without the review that would catch a dialect mistake.
The supported set named in the repository's own description is SQL Server, MySQL, PostgreSQL, Oracle, SQLite and Firebird. For anything else, the first line of the answer is the plan.
Three projects in one solution, and a folder that does not match the package
The repository is a single solution containing three projects.
One directory holds the query builder itself. A second holds the execution package with the factory type and the data access integration. A third holds the tests, and the solution file at the root ties them together.
The naming is where the confusion starts. The packages are published as SqlKata and SqlKata.Execution, while the directory holding the core library is named for the old project name, QueryBuilder. That directory name is what appears in stack traces, in file paths and in namespace paths, so anyone searching the repository for the package they installed will not find it under the name they know.
The rest of the root is contributor tooling: an editor configuration file, an editor directory committed for the people who work on it, a contributors configuration file for an automated contributor listing, and the usual repository and workflow directories.
Three projects is also the reason the tests live in their own project rather than beside the code. For a library whose value is the SQL it emits, a separate test project is where the dialect expectations would have to be written down.
Version four shipped as two tags fourteen minutes apart
The release history explains the version number better than the readme does.
The first entry is 4.0.1, dated the first of February 2025, and the second is 4.0.0, dated the same day fourteen minutes earlier. Before them, three years and three months back, is a 3.0.0 beta from October 2022.
So a major version was tagged and then immediately corrected, and the stable line before that was still a beta. There is no 3.x release in this list to upgrade from, which means the jump from a beta to 4.0 is the upgrade path the project actually offers.
The last recorded push to the default branch is dated 2026-04-10, which is more than a year after the newest tag, and the repository is not archived. So there are unreleased changes above 4.0.1, and the readme gives you no way to see them: the FAQ points at a personal account for release announcements and at a newsletter on the project site.
For a library at version four with no breaking changes for eighteen months, the practical question is whether you want the tag or the branch, and those are different code bases.
Funding is stars, upvotes and an open collection
The last section of the readme asks for three things, and it is worth knowing what is not on that list.
It asks for stars on the repository, a follow and an upvote on a product listing page, and a donation through an open collection. The header repeats the product listing request twice, once as a badge row and once as a paragraph asking readers to follow and upvote to encourage development.
There is no sponsorship tier, no paid edition, no enterprise feature and no support contract mentioned anywhere in the document. The library is MIT licensed, with the licence file at the root of the repository, and the commercial surface is a website.
That combination, a permissive licence with donation funding and a project site that is separate from the documentation, is a common shape for infrastructure libraries, and it has a practical implication: the roadmap is not something you can buy into, so if you need a dialect added you are writing that compiler yourself.
One detail in the examples is worth flagging for anyone copying them. The connection object in the setup sample is constructed with a placeholder string and a type name that is not part of the base class library, so treat that snippet as a shape rather than as code to paste.
Editorial conclusion
SqlKata fits a team that wants to generate SQL it can read, hand to a reporting tool, or store as text, and that does not want an object mapper deciding what its queries look like. The design is legible: a fluent chain that ends in a terminal call, writes that return affected row counts, and a database abstraction you can compile to a string without touching a connection. Three things to check before you commit. The execution package is separate, so a library that only needs SQL does not need a database driver. The supported database set is fixed by policy, and the project says outright that it will not accept a contributed compiler, which means an unsupported database is yours to maintain. And the release trail is uneven: a major version after a two year gap, a patch released minutes later on the same day, and then over a year of commits with no numbered release.
Frequently asked questions
What is SqlKata?
A SQL query builder written in C# with a unified API across supported databases, described as framework-agnostic and inspired by the Laravel query builder and Knex. Execution support is a separate optional package that runs the queries with Dapper.
Which databases does SqlKata support?
The repository description names SQL Server, MySQL, PostgreSQL, Oracle, SQLite and Firebird. The readme states that supporting every vendor is impossible, that the project focuses on the major ones, and that it does not accept contributions adding a new compiler, encouraging you to write your own instead.
How do I install SqlKata?
Add the SqlKata package for the query builder, and add the SqlKata.Execution package if you want the execution support. The query factory type your code calls comes from the execution package, so a project that only needs to generate SQL text can skip it.
Does SqlKata track entities like an ORM?
No. The write examples return the number of affected rows from insert, update and delete, and the read examples access result properties dynamically rather than through mapped objects. There is no change tracking, identity map or migration tooling in the examples.
How does SqlKata paginate results?
Paginate takes a page size and returns a page object with a List property holding the rows and a Next method returning the following page, so paging is a chain of page objects rather than an offset argument.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sqlkata-querybuilder)Star history chart for your README
[](https://hysenlabs.com/projects/sqlkata-querybuilder)Was this useful?