The author sells courses about the thing the library does
FusionCache is an easy to use, fast and robust hybrid cache with advanced resiliency features.
At a glance
- What is it?
- FusionCache is a hybrid cache for .NET that sits on top of the framework's own distributed cache interface and adds resiliency features the base abstraction lacks. Its documentation is thorough, its author links his paid courses from the same page, and the claim of Microsoft using it in production rests on one blog post.
- Who is it for?
- FusionCache suits a .NET team that already runs a distributed cache and wants stampede protection, fail-safe behaviour and observability without changing how calling code retrieves values, or that wants a local cache today and a second level later without a rewrite. Four things to check before you adopt it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
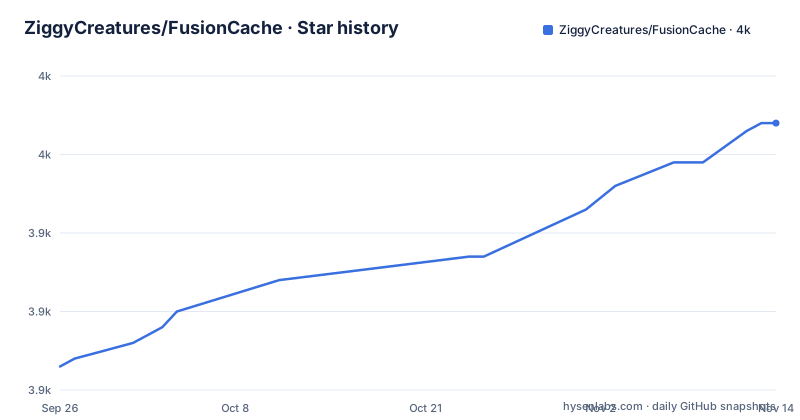
- ZiggyCreatures/FusionCache3,954 ★ · +31
| Repository | 2026-09-26 | 2026-11-14 |
|---|---|---|
| ZiggyCreatures/FusionCache | 3.9k | 4k |
31 Stars in the last 49 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It works as a drop-in second level because it targets an interface, not a product
The architectural decision that makes this library practical is stated in one sentence: being a hybrid cache means it can transparently work as either a normal in-memory cache or as a two-level cache where the distributed second level can be any implementation of the framework's standard distributed cache interface. That is the whole design in a nutshell. Because the second level is expressed as an interface rather than a named backend, you can point it at whatever distributed cache you already run, or run without one at all and have it behave as a plain local cache. The same code path serves both, which means the L1-plus-L2 configuration is not a different mode you have to test separately. The claimed benefits follow from that shape rather than from anything exotic: better cold starts, because a warm second level answers before the local one fills, better horizontal scalability since the shared tier absorbs the load, and more resiliency because a node restart does not empty the cache. The README also notes compatibility with Microsoft's own newer hybrid cache abstraction, and describes that as a separate integration rather than a replacement, so the library sits alongside the framework's direction rather than against it.
The fail-safe feature is the interesting one, because it deliberately serves stale data
Most cache features on the list make things faster or more available. This one makes a different trade, and it is worth understanding what you are agreeing to. The fail-safe mechanism avoids transient failures by reusing an expired entry as a temporary fallback. So when the factory or the distributed cache fails, instead of throwing, the cache returns a value it already knows is out of date. That is a deliberate availability-over-freshness decision, and it is the kind of feature that should be opt-in with clear documentation rather than on by default, because for some data an expired value is worse than an error. It sits in a group of three resiliency features, the other two being automatic protection against a cache stampede, both for a single node and across multiple, and self-healing for the whole cache. The stampede protection is the one you are most likely to want on by default, since the failure it prevents, many concurrent requests all missing and all calling the factory at once, is a common and self-inflicted outage. The README does not say which of the three are enabled by default, so that is worth checking in the options documentation before you rely on any of them.
The Microsoft production claim is one blog post, and the award is from 2021
Two credibility claims sit near the top of the README and they are worth separating carefully. The first says the library is used in production on real-world projects with high volumes for years, and is used by Microsoft itself in a product, linking to a general availability announcement for a database-oriented API builder service. The second says the project received a Google Open Source Award, linking to an announcement blog post from September 2021. Both are real and both are checkable, but the framing does more work than the evidence. A general availability blog post is a product announcement, not a statement about what caching library a service uses, so the Microsoft claim rests on the reader's willingness to take a link as evidence. The award is from a specific year and is now several years old, which tells you about a moment rather than about the current state of the project. What the release history actually supports is more useful: three releases in the last month, a minor version two weeks before the newest patch, and a last commit on the same day as the newest release. That cadence is a better signal of maintenance than either claim.
Two paid courses about caching are linked from the documentation page
The getting-started section routes readers through a series of documentation pages, and then the next section is titled Courses and links two of them, one on getting started with caching in this language and one on a deeper treatment. The courses are on a paid platform, the links carry a referral parameter naming the author, and the section says plainly that if you like the library's documentation you may like the courses. The author is also candid that the courses are not about this library but about caching in general, from foundations to advanced topics, and that he condensed more than twenty years of experience into them. All of that disclosure is above board, which is the main thing. What is worth noting for an evaluator is the shape of it: the same page that is the library's front door is also the shop window for the author's courses, and the library's documentation is described as being of similar quality to paid material. That is a compliment to the docs and a reminder that the docs are also marketing. If you are assessing the library, read the options page and the core methods page directly rather than starting from this page and following the path it steers you toward.
A fail-safe plus a stampede guard plus eager refresh is a lot of machinery behind one call
Count the features grouped under performance and scalability and you get seven, several of which alter when and how work happens rather than merely speeding it up. Soft and hard timeouts mean a slow dependency will not slow down your application and, in the README's phrasing, no data will be wasted. Eager refresh starts a non-blocking background refresh before the expiration point. Conditional refresh is described as the caching equivalent of a conditional HTTP request. Background distributed operations move distributed work off the request path. The backplane notifies other nodes about changes so they stay in sync. And the two-level design is in the same group. Each of those is individually reasonable and together they are a substantial amount of machinery operating underneath what looks like a single cache lookup. The design intent is that none of it is visible to calling code, and the adaptive caching feature exists precisely to reduce configuration where you cannot know entry options in advance because they depend on the value itself. The cost of that transparency is that when something behaves unexpectedly you are debugging a layer you did not know was there, which is why the observability features, logging, distributed tracing, and tagging, exist as a named group rather than an afterthought.
The project has a solution file in the new format and pins its toolchain
The repository is small and tidy, and three entries in it say something about how the project is maintained. There is a single directory-level build properties file rather than one per project, which is the usual way to share version numbers, target frameworks and analyzer settings across a solution without repeating them. There is a global settings file for the SDK, which pins the toolchain version so that every contributor and every build server compiles against the same compiler. And the solution file uses the newer extension-based format rather than the classic one, which is the format recent tooling produces by default. There is also a dedicated benchmarks directory and a tests directory at the root, so performance claims and correctness are both treated as things to check continuously rather than occasionally. The source directory is a single one, which suggests the library ships as one package rather than being split into a core assembly and a set of extension packages. For a library whose selling point is a drop-in replacement for the framework's own abstraction, one package is the right shape, since the alternative would mean assembly version conflicts with anything else that references the caching interfaces.
The feature list is truncated mid-word, which tells you the file is maintained by hand
The last item in the plugins entry breaks off in the middle of a word, and the plugins documentation link is dangling as a result. That is a small thing, and it is also the most reliable signal in this README about how the file is produced: every other line is carefully formatted with an emoji, a bold link and a one-sentence explanation, which is not what a generated file looks like. It is a person writing prose in Markdown and occasionally saving mid-thought. The same applies to the surrounding content. The talks section says the author has been invited to conferences and podcasts over the years and points at a separate personal repository for the recordings and slides, with the word sometimes attached to whether the slides are available. The introductory paragraphs explain the project's origin as an attempt to consolidate experience with many kinds of caching, and the phrasing is first person throughout. None of this is a defect. A library README maintained by its author rather than generated from templates will read better and will occasionally be cut off mid-sentence, and for documentation that is genuinely good, that trade is usually worth making.
Editorial conclusion
FusionCache suits a .NET team that already runs a distributed cache and wants stampede protection, fail-safe behaviour and observability without changing how calling code retrieves values, or that wants a local cache today and a second level later without a rewrite. Four things to check before you adopt it. Decide on the fail-safe deliberately, because it serves expired entries during transient failures and that is the right trade for some data and the wrong one for others. Read the options documentation rather than trusting defaults, since the README does not say which of the resiliency features are on by default. Confirm your second-level implementation satisfies the standard interface, because that is the whole integration surface. And note the provenance claims are a single product announcement and an award from 2021, so read the recent release cadence instead as your signal of maintenance.
Frequently asked questions
what is fusioncache
It is a hybrid caching library for .NET that can operate either as a plain in-memory cache or as a two-level cache whose distributed second level is any implementation of the standard distributed cache interface. It adds resiliency features such as cache stampede protection, a fail-safe that reuses expired entries during transient failures, self-healing, soft and hard timeouts, and eager refresh, plus logging, distributed tracing and tagging for observability.
is fusioncache free
The library itself is released under the MIT licence and is available as a package. Separately, the author sells two paid courses about caching in general on a course platform, and those are linked from the library's documentation page with a referral parameter. Those are separate purchases, not a paid tier of the library.
fusion cache vs redis
The README does not position this against any named product, and it does not need to. The distributed second level is expressed as the framework's standard cache interface rather than a specific server, so it can sit in front of Redis or any other implementation without the library changing. What it adds over using that interface directly is the layer above: stampede protection, fail-safe behaviour, timeouts, eager refresh, a backplane for multi-node notification, and observability.
fusion cache vs memory cache
It is designed to be a drop-in for both roles. In single-level mode it behaves as an ordinary in-memory cache; adding a distributed second level makes it two-level without changing how calling code uses it. The stated benefits of the second level are better cold starts, better horizontal scalability, more resiliency and better overall performance, since a node restart no longer empties the cache.
How do I delete a FusionCache entry or whole cache?
There is a documented clear capability described as being able to clear an entire cache, including when a shared second level is in use, a cache key prefix is set, and similar scoping concerns. There is also a tagging feature, where tags are associated with entries so that a group of them can be expired at once, which is usually the better tool when you only want to invalidate part of a cache.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ziggycreatures-fusioncache)Star history chart for your README
[](https://hysenlabs.com/projects/ziggycreatures-fusioncache)Was this useful?