zotero-AI-Butler: a beta Zotero plugin that summarizes papers through your own API key
Zotero AI Butler: calls an LLM to automatically read papers in your Zotero library closely and summarize them as Zotero notes. Supports major LLM platforms. Just drop papers into Zotero as usual, and the butler reads and condenses each one into notes so you can fully understand a paper in ten minutes.
At a glance
- What is it?
- A Zotero plugin that reads newly added PDFs and writes Markdown notes back onto the item, using whichever model provider you configure. Its primary documentation is in Chinese, its settings list four providers while its model table lists six, its development defaults point at an older Gemini than the one it recommends, and its releases have been beta since 2026-07-29.
- Who is it for?
- zotero-AI-Butler suits a Zotero user who already has a model API key and wants summaries to arrive without asking, and who reads the Chinese documentation or the English copy beside it. Three things to check before you install it.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
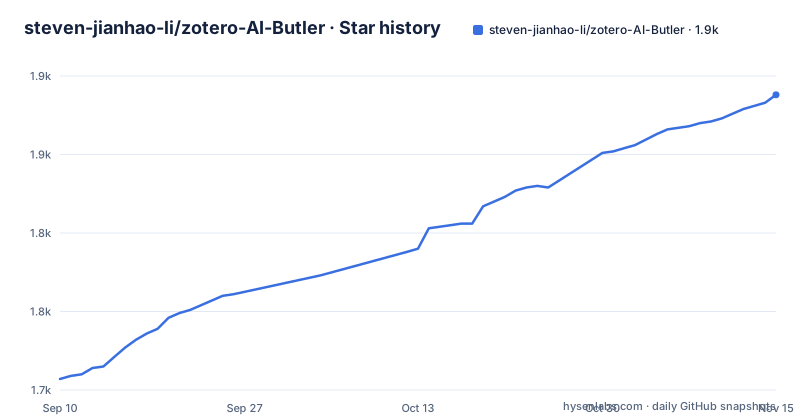
- steven-jianhao-li/zotero-AI-Butler1,888 ★ · +181
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| steven-jianhao-li/zotero-AI-Butler | 1.7k | 1.9k |
181 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The main README is in Chinese, with an English copy beside it
The documentation situation is stated in the second line of the file. The language line reads Simplified Chinese, with a link to `README-EN.md` for English, and that English file is checked in next to the Chinese one at the top level of the repository. The repository description is Chinese as well.
The rest of the page is written in a marketing register, with pain point lists about having too many papers to read and forgetting them two days later, and a claim that the plugin will let you understand a paper in ten minutes. The feature sections underneath it are much more concrete, and they are what the article below is drawn from.
One metadata oddity is worth knowing. The homepage recorded for the repository points at the releases page rather than at the documentation. The actual configuration and usage documentation lives on a separate site under the author's GitHub Pages, linked from a line near the top, so the repository's own metadata does not take you to the docs.
There is also a citation trail: a `CITATION.cff` file at the top level and a Zenodo DOI badge, and the page asks that you cite or acknowledge the plugin in a paper if it helps your research. That is a scholarly tool aiming at academic use rather than a general note taker.
Four providers in the settings, six rows in the model table
The quick settings panel describes API configuration for four platforms: OpenAI, Gemini, Anthropic, and OpenAI-compatible endpoints, with third party services such as SiliconFlow named as an example. A test connection button verifies a key after you paste it.
The provider table further down lists six. On top of those four it adds Volcano Ark with the Doubao model `doubao-seed-1-8-251228`, described as offering two million free tokens a day, and Ollama with `llama3.2`, described as a local or LAN model service that handles PDFs through text extraction or MinerU.
So the settings copy and the table disagree about scope, and the gap is meaningful rather than cosmetic. One of the two extra rows is the only one in the whole table that keeps your paper on your own machine, since Ollama runs locally. The other is the row with the most generous free allowance.
The recommended model in the table is `gemini-3-pro-preview`, chosen for multimodal strength and PDF comprehension, with OpenAI listed as `gpt-5` and Anthropic as `claude-opus-4-5-20251101`. The OpenAI-compatible row is described as the older Chat Completions format.
Everything is documented as free in the sense that the plugin itself has no paid channel: the cost is whatever your provider charges you.
The development defaults are a model generation behind the recommendation
The committed `.env.example` is the most precise document in the repository, and it does not agree with the prose. It sets a default provider and one triple per provider:
AIBUTLER_PROVIDER=google
GEMINI_MODEL=gemini-2.5-pro
The same file also carries `OPENAI_MODEL=gpt-5` and `ANTHROPIC_MODEL=claude-sonnet-4-5-20250929`, plus an `*_API_URL` placeholder for each provider, which is what makes custom endpoints and OpenAI-compatible services possible. So the developer defaults are Gemini 2.5 Pro and Claude Sonnet 4.5, while the feature table recommends Gemini 3 Pro Preview and lists Claude Opus 4.5.
That gap matters for anyone reproducing a reported behaviour, because the model you develop against and the model the page tells you to use are not the same one, and the plugin's output quality depends heavily on which you picked.
The same file carries the developer plumbing. Three `ZOTERO_PLUGIN_` variables point at the Zotero binary, the development profile and the data directory, each with a comment explaining how to create it, and an optional kill command override for custom setups. There is also a `GITHUB_TOKEN`, described as needed only if you publish releases locally rather than through CI.
Three ways to start work, and one of them overwrites your note
The right-click menu is the immediate route. You choose the entry that summons the butler on a specific item, the task enters the queue, and a detail view shows the model's response as it happens.
The same menu has a second entry for reading a paper again with more rounds of conversation, in either a stitching mode that concatenates the answers or a summary mode where the model distils them at the end. The documentation is explicit that this forces an overwrite of the existing AI note. There is no mention of keeping the old version, so a second pass is a replacement rather than an additional note.
Automatic cruising is the hands-off route and it is off by default, the stated reason being to minimise the impact on Zotero's performance. You turn it on in the dashboard under interface settings, and once enabled the plugin waits for Zotero to finish metadata retrieval on a newly dropped PDF before it starts. The setting persists across restarts.
Batch processing is for the backlog. A scan finds every paper without an AI note, arranged by your Zotero directory structure, and you tick the ones you want and add them to the queue, where they are processed in the background at the speed you configured.
A producer and consumer queue with a rate limit you set
The task queue page is where all analysis state lives: pending, running, completed and failed. The page names the design outright, saying all paper analysis runs on a producer and consumer model. The dashboard is reached from Zotero's own settings under a dedicated tab, or from the right-click menu on any item.
The consumer side is deliberately slow. One setting controls how many papers are processed per minute, and the reason given is to avoid hitting API limits. That is the right instinct for a plugin that talks to a metered endpoint, and it also means the queue drains at a rate you choose rather than as fast as your key allows.
The PDF itself goes by one of two routes. Multimodal mode encodes the PDF as Base64 and uploads it, which lets a vision capable model see the original page and is described as stronger on images, formulas and tables. Text extraction mode is for models without image input, and the Ollama row says local models use text extraction or MinerU. The plugin claims lossless extraction of formulas, figures and complex layouts, including PDFs that are nothing but images.
One inconsistency in that dashboard section is worth flagging. It says the dashboard contains four main pages and then describes three: the overview with statistics, the task queue, and quick settings.
No proxy, your key, your provider, and one community workaround
The privacy statement at the top of the page is specific. This is a third party open source Zotero plugin, it does not provide any large model proxy service, you have to obtain and configure your own API key, and the plugin never collects, stores or uploads your personal data, your papers or your key. Every request goes directly from your local device to the model provider you configured.
That claim is consistent with the rest of the documentation, and it has a consequence worth being explicit about. In multimodal mode the entire PDF is Base64 encoded and sent to the provider, so the provider receives the paper, not just a summary request. Choosing the OpenAI-compatible option, or Ollama on your own machine, is the only lever the plugin gives you over that.
The page also recommends Gemini 3 Pro for summarising papers, and then addresses the obvious obstacle with a link to a discussion in the repository. That discussion points at `gcli2api`, a community project, and describes deploying it to get a personal, effectively unlimited free Gemini 3 Pro allowance. It is an unofficial path built on a different project, and the page presents it as a configuration tutorial rather than as an integration.
Elsewhere the plugin asks to be cited, and states that all prompts are customisable, with templates for research background, method, experiments and conclusions, and a live preview showing variable substitution such as `{{title}}` and `{{authors}}`.
Beta releases since 2026-07-29, and a build that checks its own translations
Every recent release is a pre-release: `v4.0.3-beta.8` on 2026-07-27, then `v4.1.0-beta.1` and `v4.1.0-beta.2` on 2026-07-29, the last two about eighty minutes apart. The last commit to the repository is dated 2026-09-28, so there have been roughly two months of work since the newest tag was cut, and it is still a beta.
The build scripts show what the project treats as a release gate. `build` runs the plugin build and then `tsc --noEmit`, so a type error fails the build. A `prebuild` script runs `scripts/check-i18n.mjs` and a `postbuild` runs `check-i18n-build.mjs`, meaning the localisation state is checked both before and after. Tests go through `zotero-plugin test --exit-on-finish`, and the `pretest` hook generates an environment setup file first.
Five separate script names call those same two i18n checkers, including `i18n:check`, `i18n:check:build` and `test:i18n`. That duplication suggests the checks were bolted onto different entry points rather than composed once, which is harmless and slightly untidy.
The plugin also ships a `scaffold:provider` script that creates a new provider through `create-provider.mjs`, which is the maintenance path for adding an eighth backend when the table catches up with the settings panel.
Editorial conclusion
zotero-AI-Butler suits a Zotero user who already has a model API key and wants summaries to arrive without asking, and who reads the Chinese documentation or the English copy beside it. Three things to check before you install it. That you can live with a pre-release line, since every tagged release is a beta and the newest is dated 2026-07-29. Which provider you point it at, because in multimodal mode the full PDF is uploaded as Base64 to whichever service you configure, and only the local Ollama path avoids that. And that re-running the multi-round re-read will overwrite the note already attached to an item.
Frequently asked questions
What does zotero-AI-Butler do with my papers and my API key?
It runs no proxy service and asks you to bring your own key. The project states it never collects, stores or uploads your data, papers or key, and that requests go straight from your local device to the provider you configured.
Which language models can zotero-AI-Butler use?
The table lists Google Gemini with gemini-3-pro-preview as recommended, OpenAI gpt-5, Anthropic claude-opus-4-5-20251101, an OpenAI-compatible legacy Chat Completions path, Volcano Ark doubao-seed-1-8-251228 with two million free tokens daily, and Ollama llama3.2 on a local or LAN service.
Does re-running zotero-AI-Butler on a paper erase the old note?
The multi-round re-read option does. Choosing it from the right-click menu, in either the stitching or the summary mode, is documented as forcing an overwrite of the existing AI note.
Is automatic scanning of new papers on by default in zotero-AI-Butler?
No. It is off by default to minimise the impact on Zotero's performance, and you enable it in the dashboard under interface settings. Once on, the plugin waits for Zotero to finish metadata retrieval on a newly added PDF, and the setting survives a restart.
How does zotero-AI-Butler send a PDF to the model?
Either as a Base64 multimodal upload, which lets a vision capable model see the original page and is described as stronger on images, formulas and tables, or through text extraction for models without image input. Local Ollama models use text extraction or MinerU.
How is zotero-AI-Butler licensed and built?
AGPL-3.0-or-later. The build runs the plugin build followed by tsc --noEmit, with i18n checks running before and after it, and tests run through zotero-plugin test --exit-on-finish. A scaffold:provider script creates a new model provider.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/steven-jianhao-li-zotero-ai-butler)Star history chart for your README
[](https://hysenlabs.com/projects/steven-jianhao-li-zotero-ai-butler)Was this useful?