ai-coding-guide: 92 articles, and the recommended tool has 39 of them
Possibly the most complete Chinese-language AI-coding CLI tutorial for beginners: 92 polished articles covering Claude Code and Codex.
At a glance
- What is it?
- A Chinese tutorial set for Codex and Claude Code, published as an index of links to a hosted site rather than as files you can read in the repository. The article counts are internally consistent, which makes the framing the interesting part: the title, the description, and the stated main recommendation all point at the tool with fewer articles.
- Who is it for?
- What this repository is, in practice, is a landing page: two README files, a license, three directories, and an image, with every article link pointing at an absolute URL on a hosted site. That has a cost, since the tutorial cannot be read or searched offline and cannot be diffed when a tool changes, and it means a fork is not a fork of the content.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 79 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 19, 2026, and from our analysis. They are not legal advice.
Star history
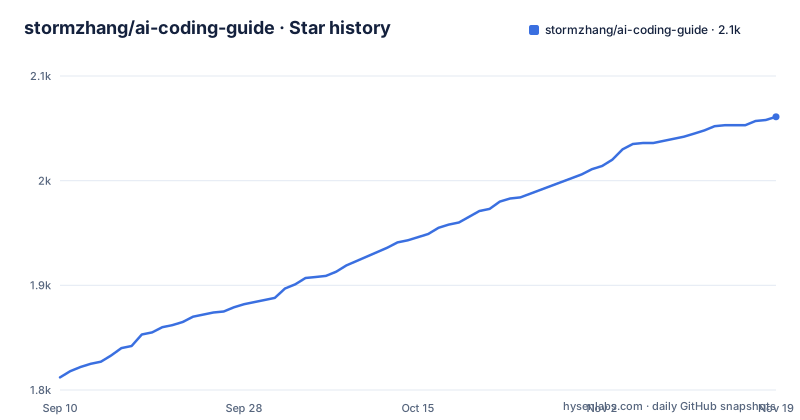
- stormzhang/ai-coding-guide2,061 ★ · +249
| Repository | 2026-09-10 | 2026-11-19 |
|---|---|---|
| stormzhang/ai-coding-guide | 1.8k | 2.1k |
249 Stars in the last 70 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
All ninety-two articles are absolute URLs, not files in the repository
Every article in the contents listing is a link of the form `https://coding.stormzhang.ai/claude-code/01-what-is-claude-code` or the equivalent under `/codex/`. Not one points at a path inside the repository.
That tells you what the repository is for. The top-level entries are a license, a Chinese README, an English README, a `.gitignore`, three directories named `claude-code/`, `codex/`, and `deepseek-harness/`, and a single image. There is no site generator configuration, no build script, and no framework manifest at the root.
So the repository is a signpost to a hosted site, and the tutorials themselves are reachable only through that site. A reader who clones the repository gets a table of contents with nothing behind it, and a fork carries the index rather than the ninety-two articles. That is a real difference between a documentation repository and a documentation website with a repository attached, and the tree makes it clear which one this is.
The language switch at the top of the page swaps `README.md` for `README.en.md`. Both are front pages; whether the English one points at a separate English site is not visible from what is shown, since the Chinese file's links all use the one host.
The article slugs are in English while the prose is Chinese, which is a deliberate choice that keeps the URLs language-neutral and makes a future English site a host change rather than a link rewrite.
The recommended tool has fourteen fewer articles than the one it replaced
The heading names Codex first and describes the Claude Code material as included. The repository description does the same, and the header calls Codex the main recommendation while saying Claude Code is retained.
The counts run the other way. The Claude Code section is fifty-three articles and the Codex section is thirty-nine, so the retained tool has fourteen more, and the Claude Code contents block is presented first in the table of contents with its full list expanded.
The arithmetic in the header is right, at least: ninety-two articles, made up of thirty-nine for Codex and fifty-three for Claude Code, at roughly five hundred and twenty thousand words. Both labelled lists agree with those figures where they are visible, with the Claude Code block running from 01 to 53 in sequence and the Codex block starting at 01.
One qualification on the fifty-three. The final entry, on making video with Remotion, is marked as elective reading. So the numbered sequence is fifty-three long while the core path is fifty-two, which means the headline count includes an article the author does not put on the main path.
What the split suggests is a course in mid-migration rather than two parallel tracks, with the older material kept intact and the newer one being written. That reading is consistent with the article titles, where the Codex list spends its early entries on entry points, concepts, install, pricing, and third-party models.
One of the two fact-checking baselines is a translated page
The first of the five stated differences is that official documentation is the source of truth, and it names two places: the official Codex documentation and the official Claude Code documentation. Everything described as a feature, a command, or a default behaviour is said to be checked against them, with an explicit commitment to not copy third-party guesses and not rely on rumour.
The Codex link points at the developer documentation root. The Claude Code link points at a path ending in a Chinese locale marker, which is the Simplified Chinese version of the documentation rather than the English one.
That is a small detail with a large consequence for a guide whose central claim is verification. Checking a translation is a weaker guarantee than checking the source text, because the translation is a second text that can be stale, abbreviated, or quietly different from the original, and a discrepancy in it becomes a discrepancy in the article. It also means a reader who wants to check the guide's citations has to read Chinese official documentation to do it.
The two tools are on different documentation domains as well, one under the OpenAI developers domain and one under a Claude-specific documentation host, so a reader following both links is visiting two separate documentation properties rather than one.
Nothing in the visible text says whether the English Claude Code page was also consulted, and the claim of not copying third-party sources is about third parties rather than about translations of first-party material.
Five editorial rules, and the two with numbers in them are the real content
The five differences are worth separating, because two of them are vague and three are testable.
The testable ones carry thresholds. Every hands-on step is supposed to include a complete command plus the expected output, so a reader can tell whether their run matched. Every article is supposed to contain at least three first-person accounts of a mistake or a judgement, with specific detail and real numbers rather than opinion-shaped phrasing. The illustrations are capped: eighty-one original SVG and PNG diagrams in one dark engineering style, with no text piling up and no diagram exceeding ten nodes.
The node cap is the most unusual rule here, and it is a real design constraint. Ten nodes is enough for a pipeline sketch and not enough for a full architecture diagram, so it forces every illustration to make one point rather than to be a reference. The first-person minimum is a similar constraint on prose, and it is aimed at a specific failure mode, which is articles that read as documentation when they should read as experience.
The other two are structural. Every new concept is introduced in three parts, a scenario that motivates it, an everyday analogy, and a real situation where it applies. And the whole is aimed at readers who are not comfortable with a command line.
That combination is the transferable part of the project. The articles are about two tools whose interfaces change, but a ten-node diagram limit does not go out of date.
The first six articles are onboarding and billing, not technique
Reading the Claude Code contents in order, the opening six entries are: what it is, installation, how it works, whether to use a subscription login or an API key and how to switch between them, connecting third-party and domestic models, and the subscription plans and their billing.
Only two of those six are about how the tool works. Three are about getting in and paying for it, and one is a decision guide rather than a capability description.
The Codex list has the same shape in a compressed form: what it is and its four entry points, core concepts, installation and login, subscription and billing, connecting DeepSeek and other domestic models, and running the first task.
That ordering is a statement about the reader. The audience is described as people starting from zero, and the first thing a person starting from zero has to solve is not how the agent loop works but which account to create, whether to use a subscription or a key, and what it costs. A reader who already has both tools configured will find articles four and six skippable, which is worth knowing before starting.
It also means the billing articles are load-bearing rather than incidental. Every later article assumes a working login, and the choice made in article four determines what the rest of the material assumes.
No version anchor on ninety-two articles about tools that ship often
There are no published releases, and the last commit is dated 2026-09-02. So the content carries no version marker at the repository level, and no article states which release of either tool it describes.
The article titles show how much of the material is tied to specific surface area rather than to concepts. There are dedicated entries for output styles, hooks, slash commands, checkpoints, plugins, settings files, the CLI reference, environment variables, the agent SDK, and a chapter on voice mode. There are separate entries for VS Code, JetBrains, desktop, web and cloud, and Chrome integration. The Codex list has its own entries for the CLI, IDE extensions, cloud, worktrees, sandbox approval, a configuration file, a memory system, and migration from the other tool.
Those are all moving targets. A permissions chapter, a hooks chapter, and a CLI reference chapter are all describing defaults that a vendor can change without a major version. A guide organised this way decays at the rate of the tools it documents, and the repository gives a reader no way to tell which articles are current and which have been overtaken.
There is a change log file at the root, which is the natural place a reader would look for that signal. What the visible text does not show is whether it tracks corrections to individual articles, which is the thing that would answer the question.
A harness directory the index never explains
Three directories sit at the root: `claude-code/`, `codex/`, and `deepseek-harness/`. The first two are named after the two tools the contents listing covers.
The third is not. Nothing in the visible text refers to it, no heading mentions it, and neither of the two article sections is titled after it. The closest the index comes is the Codex article on connecting DeepSeek and other domestic models, which is one lesson in a thirty-nine article list and is a guide to configuration rather than a harness.
A directory named after a harness rather than after a lesson usually means runnable code, and the repository's primary language is recorded as unknown, which is what you would expect if the top level is two READMEs, a licence, a gitignore, three directories and an image with no dominant file type of its own.
So there is something in the repository that is not prose, it is named for a model provider, and the landing page does not point at it. Whether that is a gap in the index or a deliberate omission cannot be told from what is shown, and a reader following the ninety-two links will not encounter it.
The repository description is also the only place with an unguarded superlative, describing the set as possibly the most complete on the internet, in quotation marks, which reads as the author hedging their own marketing claim rather than asserting it.
Editorial conclusion
What this repository is, in practice, is a landing page: two README files, a license, three directories, and an image, with every article link pointing at an absolute URL on a hosted site. That has a cost, since the tutorial cannot be read or searched offline and cannot be diffed when a tool changes, and it means a fork is not a fork of the content. Read the five editorial rules as the actual product, because they are the part that transfers: a bounded diagram, a fixed structure per concept, and a requirement that personal claims carry measured numbers. Verify any figure against the tool's own current documentation before acting on it, since the guide tracks features that ship often and carries no version anchor to tell you how fresh a given article is.
Frequently asked questions
What is stormzhang/ai-coding-guide?
A Chinese-language tutorial set for AI coding command-line tools, MIT licensed, read online at coding.stormzhang.ai. The repository description calls it 92 refined articles of roughly 520,000 words, split into 39 Codex articles and 53 Claude Code articles.
How many articles does ai-coding-guide contain?
The header states 92 articles, made up of 39 for Codex and 53 for Claude Code. The Claude Code contents block runs from 01 to 53, with the Remotion video article marked as elective reading, so the core path is 52.
How does ai-coding-guide check its information?
It states that features, commands, and default behaviour are checked against the official Codex documentation and the official Claude Code documentation, without copying third-party guesses or relying on rumour. The Claude Code link points at the Simplified Chinese version of that documentation.
Is the ai-coding-guide website stored in the repository?
The top-level entries are a license, two README files, a gitignore, three directories, and one image, with no site build configuration at the root. Every article link points to an absolute URL on coding.stormzhang.ai rather than a path inside the repository.
What rules does ai-coding-guide set for its illustrations?
It claims 81 original SVG and PNG illustrations in a unified dark engineering style, with no text piling up and no diagram exceeding ten nodes. Other stated rules are three or more first-person accounts with real numbers per article, and a complete command plus expected output for every hands-on step.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stormzhang-ai-coding-guide)Star history chart for your README
[](https://hysenlabs.com/projects/stormzhang-ai-coding-guide)Was this useful?