ai-engineering-toolkit is two files, and its best feature is a licence column
A curated list of 100+ libraries and frameworks for AI engineers building with LLMs
At a glance
- What is it?
- ai-engineering-toolkit is a curated list rather than a toolkit: the repository holds a licence file and a README, nothing else, and the README is a long set of tables covering vector databases, orchestration, PDF extraction, RAG and more. What makes it more than a link dump is that every row records a description, an implementation language and a licence, which turns a reading list into something you can filter on.
- Who is it for?
- Use this list the way its structure invites, as a filter: pick your constraint first, whether it is a licence you are allowed to ship, a language your team already runs, or a category such as PDF extraction, and read across the row rather than down the column. That is the one thing it does that a plain awesome list does not, and it is why the file is worth bookmarking even though the tools will change.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
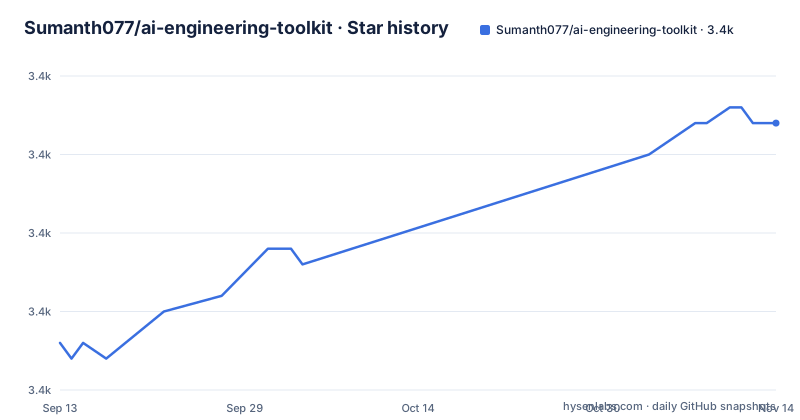
- Sumanth077/ai-engineering-toolkit3,402 ★ · +14
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| Sumanth077/ai-engineering-toolkit | 3.4k | 3.4k |
14 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is a licence file and a README, and that is all
Before reading a single row, the shape of the thing is worth stating plainly. The tree at the root of this repository contains two entries: LICENSE and README.md. There is no source directory, no build configuration, no test suite, no continuous integration file, and no releases published on the platform. The project records no primary language, which is what you would expect when there is nothing to compile. The introduction promises battle-tested tools, frameworks, templates and reference implementations, and every one of those lives somewhere else, which means the value on offer is editorial judgement rather than anything you can install from here. The MIT badge at the top links to the licence text on opensource.org, and the licence file at the root matches it, so the terms of the list itself are unambiguous even though the terms of the things it lists vary widely.
Every row carries a language and a licence, which is the actual contribution
The distinguishing feature of the tables is their fourth column. Each one is headed Tool, Description, Language and License, so a row is a decision record rather than a bookmark. Read across the licence column in the visible sections and the spread is instructive: MIT for LangChain, LlamaIndex, DSPy, Semantic Kernel, Langflow, Flowise and Promptflow; Apache-2.0 for Qdrant, Chroma, Milvus, Deep Lake, Haystack, RAGFlow and Dify; BSD-3 for Weaviate and Verba; Commercial for the two managed services, Pinecone and Vectara; and AGPL-3.0 for one entry discussed below. The language column is just as uneven, with Python carrying most of the list, Go appearing for the vector databases, Rust for Qdrant, C++ with Python for FAISS, TypeScript for the visual builders, and a C#, Python and Java entry for Semantic Kernel.
A copyleft parser sits next to a permissive wrapper around it
Two rows in the PDF extraction table are worth reading together. PyMuPDF, also referred to by its fitz name, is listed as a lightweight, high-performance parser for text and image extraction and manipulation, implemented in Python and C, and its licence column reads AGPL-3.0. Every other entry in the visible tables is MIT, Apache-2.0, BSD-3 or Commercial, so this is the one row where the terms pull in a different direction from the rest. Directly beneath it sits PyMuPDF4LLM, described as a wrapper around PyMuPDF for LLM ready text, tables and image extraction, written in Python and licensed Apache-2.0. A permissive wrapper sitting on top of a copyleft core is a normal thing to find in this ecosystem, and it is exactly the kind of detail the licence column exists to surface before you take the dependency rather than after.
The table of contents omits a section the body contains
The contents list is the map to the whole document, and comparing it with the sections underneath reveals a mismatch. It promises tooling for AI engineers broken into vector databases, orchestration and workflows, RAG, evaluation and testing, model management, and data collection and web scraping, then agent frameworks, then a development and optimization group containing open source inference, safety and security, app development frameworks, local development and serving, inference platforms and structured generation, and finally contributing. That is a dozen headings. The body instead opens with vector databases, then orchestration, then a PDF extraction tools section that appears in no heading on the list at all, then RAG. So one substantial category is reachable only by scrolling, and a reader working from the contents alone would conclude the document never covers document parsing, which is a strange gap in a list aimed at people building retrieval pipelines.
Libraries, managed services and no-code builders share the same table
The claim is a list of libraries and frameworks for AI engineers, and the rows do not all fit that description. Pinecone is a managed vector database reached through an API and SDK and is marked Commercial, and Vectara is a managed RAG platform with APIs for retrieval and generation, also Commercial, so those two are services you pay someone else to run rather than dependencies you install. Langflow is a visual no-code platform for building and deploying workflows, Flowise is a drag-and-drop interface for creating chains and agents, and Dify combines RAG pipelines, agent capabilities, model management and observability in one UI, so those are applications rather than libraries. At the other end of the table sit FAISS, a C++ and Python library for similarity search, and Docling, a toolkit for converting documents into structured JSON and Markdown with layout, table and code recognition. Useful set, but it is a catalogue of five or six different kinds of thing.
The homepage is a newsletter, so the list is a snapshot of one
The project's declared homepage is a Beehiiv address, aiengineering.beehiiv.com, and the header links a subscribe page on the same domain. So the maintained artefact is a newsletter, and the repository is where a copy of its content lives. That explains a few things about the document: the descriptions are written to be read rather than copied into a config, one line each, occasionally in the voice of the vendor rather than the curator, as with Quivr described as a second brain for generative work and Weaviate as an open source vector database with a GraphQL API. It also explains the absence of structure you would want in a reference, such as any statement of when a row was last checked or what a supersession looks like. Nothing in the file records a review date per entry.
The document's own copy editing is thin, which is worth knowing
A list this size accumulates typos, and two are visible in the opening. The description carries a stray comma, reading a curated, list of one hundred plus libraries and frameworks, and the tagline above it promises to build better LLM apps faster and for production in a single breath. The section headings carry emoji, which is a choice rather than an error, and the tables are consistently four columns wide, which is not. None of this affects the facts, and it is worth separating that judgement from the content, because the row descriptions themselves are accurate and specific enough to be useful: Deep Lake is described as an AI native data lake with versioned datasets optimised for embeddings and multimodal storage, Milvus as a cloud native vector database for scalable similarity search, and DSPy as a framework for algorithmically optimising language model prompts. The prose around the tables is weaker than the tables.
Editorial conclusion
Use this list the way its structure invites, as a filter: pick your constraint first, whether it is a licence you are allowed to ship, a language your team already runs, or a category such as PDF extraction, and read across the row rather than down the column. That is the one thing it does that a plain awesome list does not, and it is why the file is worth bookmarking even though the tools will change. Two cautions. Treat the licences as a starting point rather than an answer, because a table cell records what a project declares, not what your legal review will conclude, and because at least one entry is a copyleft library and another is a permissive wrapper around it. And treat the list itself as a snapshot, since the repository has no releases, the last push in this tree is dated 2026-05-11, and the project's own homepage is a newsletter rather than a documentation site, so the newest additions are more likely to appear there first.
Frequently asked questions
What is Sumanth077/ai-engineering-toolkit?
A curated list of more than a hundred libraries, frameworks and services for people building with large language models, arranged in tables that record each tool's description, implementation language and licence. The repository itself contains only a LICENSE file and the README, and it is MIT licensed with no GitHub releases.
What categories does the ai-engineering-toolkit list cover?
The table of contents names vector databases, orchestration and workflows, RAG, evaluation and testing, model management, data collection and web scraping, agent frameworks, and a development and optimization group covering open source inference, safety and security, app development frameworks, local development and serving, inference platforms and structured generation. The body also contains a PDF extraction section the contents never lists.
Does the ai-engineering-toolkit list record licences?
Yes. Every table has Tool, Description, Language and License columns, and the licences shown include MIT, Apache-2.0, BSD-3, AGPL-3.0 and Commercial, the last for managed services such as Pinecone and Vectara.
Where is the ai-engineering-toolkit maintained?
The repository holds a LICENSE and a README with no code and no releases, and the last push in this tree is dated 2026-05-11. The declared homepage is a newsletter at aiengineering.beehiiv.com, with a subscribe link in the header, so that is where the maintained copy lives.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sumanth077-ai-engineering-toolkit)Star history chart for your README
[](https://hysenlabs.com/projects/sumanth077-ai-engineering-toolkit)Was this useful?