The repository is EnterpriseAgentFramework and everything in it is ReachAI
ReachAI is an enterprise-grade agent development platform that quickly and securely brings AI to existing business systems, enabling AI to query data, fill out forms, and execute business tasks directly within OA, ERP, CRM and other systems.
At a glance
- What is it?
- ReachAI is a Java and TypeScript platform for putting an AI assistant inside existing OA, ERP and CRM pages, built on a capability model where business methods are annotated Java, page actions are registered contracts, and workflows execute a fixed graph spec. The README is in Chinese, the repository is named after neither, and no release is published.
- Who is it for?
- The interesting engineering decision here is the separation between an agent that plans and a workflow that executes a version-pinned graph, with publish validation rejecting a workflow the runtime cannot actually run. That is more defensible than letting the model improvise every call, and the capability annotations with side effect levels and required roles give you something to authorize against.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
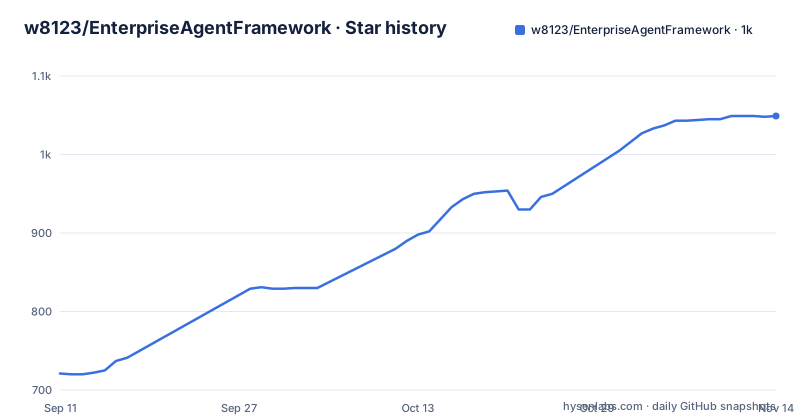
- w8123/EnterpriseAgentFramework1,049 ★ · +328
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| w8123/EnterpriseAgentFramework | 721 | 1k |
328 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The project is ReachAI and the repository is not named after it
The repository name and the product name do not match. The path is a generic phrase about an enterprise agent framework, every heading and table inside uses a different name, and the manifest identifier in the sample capability class is a third thing again, following a company-scoped package path. The first block quote on the page is not about the product at all: it is a notice for open source application verification, stating that the author owns the repository and that the account used for the application is tied to a partially masked address in a Japanese mail provider domain. It sits above the product description and is mentioned nowhere else. The body of the documentation is Chinese, several linked reference files have Chinese names, and there is no homepage field and no published release, so the source tree is the entire distribution.
Page automation is a registered contract, not a simulated pointer
The approach to the existing web interface is the claim most worth checking, because inferred pointer coordinates are where browser-driving agents usually break. The stated method is an embed for the chat entry plus a page bridge that explicitly registers which filters, navigations, reads and form operations the current page permits, exposed to the model as callable actions. Cross-page movement uses a described navigation and target-page-ready protocol, and any operation that changes real business data still goes to a backend capability or a business API rather than through the page. The claim is that the model never infers where to click. Two artefacts back it: a TypeScript file inside the admin frontend whose name ends in page bridge, and a reference document in the repository. The frontend module is worth opening before trusting the claim, since the action registry lives there.
The graph spec executes and the canvas file only describes
The split between an agent that plans and a workflow that executes is framed as a deliberate trade: fixed workflows are stable but cannot cover new requests, and fully dynamic planning is flexible but leaves cost, speed and consistency uncontrolled. The runtime path is laid out in a short block in the page: an agent moves to a published configuration version, then to a supervisor responsible for intent understanding, task planning, workflow selection and limited replanning, then selects zero, one or several authorized workflows offered as tools, and the runtime executes a version-pinned graph specification before aggregating results into a trace. Two supporting details make this more than a diagram. The graph spec holds the executable semantics while the canvas file holds nothing but layout, and publishing checks executor support up front so a workflow cannot be drawn and then fail to run.
Every scan candidate carries six fields, one of them a question
The inventory process is split into two verifiable stages, which is the honest answer to undocumented legacy systems. A page map runs first and identifies pages, routes, components and API dependencies without inferring business value from names, which is a deliberate rule against guessing. Only after a developer selects pages does read-only analysis run, and that is the stage that recommends candidates, at most three at a time. Each candidate records six fields: a confirmed fact, a technical inference, an open question, code references, an implementation reference and acceptance criteria. Having a dedicated field for what is not known alongside a separate one for what is guessed is what separates this from a list of suggestions. Those same six fields are what a reviewer has to sign off on before implementation begins.
Capabilities are annotated methods with a write level and required roles
For systems that can be modified, the integration point is a Java annotation. The sample on the page registers a method under a namespaced purchase name, with a title and description in Chinese, a module, a declared side effect level of write, and a required role. It also takes a parameter annotation carrying a description and a required flag:
@ReachCapability(
    name = "purchase.createApplication",
    title = "创建采购申请",
    description = "创建采购申请草稿,提交前需要用户确认",
    domain = "purchase",
    module = "application",
    sideEffect = ReachSideEffectLevel.WRITE,
    requiredRoles = {"PURCHASE_APPLICANT"}
)
That declaration is the authorization surface: the platform knows the operation name, the domain, whether it writes and who may call it before any model has seen it. An SDK compatible with JDK 8 and a Spring Boot 2 starter scan annotated methods and Spring MVC interfaces, report instances with signatures, store capability snapshots, compute field-level diffs, and let a developer apply or ignore each one to build the catalog. Systems that cannot be changed use the scanning path instead.
A task closes only when code, service and business result all pass
Requirements become standardized engineering tasks handed to whichever coding tool the team uses, and the closing condition is the interesting rule. Tools report progress, questions and delivery evidence continuously, and a task is not done until the code, the running service and the real business acceptance all pass. The platform verifies four things on an ongoing basis: whether the client is connected and what state the task is in, whether the code is wired up, the service is running and the SDK callback forms a closed loop, whether the embedded chat, the page actions and the actual business result pass acceptance, and whether the session, trace, workflow and release version involved in that acceptance all refer to the same thing. That last check catches a class of bug where a passing result came from a version other than the one recorded.
Writes, submissions and approvals need a human confirmation
One rule runs through the whole document and is worth stating on its own. The assistant combines the current login identity, the page state and business context to understand a request, and it calls only the business capabilities already granted to that user, so an operation is bounded by the human who triggered it. Page-level filtering, navigation and form actions run through registered page actions; real data reads and writes go through a backend capability or a business API; and anything involving a write, a submission or an approval must be confirmed by the user before it executes. The operations centre reports per project the agents, run samples, identifiable users, token usage, technical completion rate, outstanding risk items and each business system's contribution, which is how a manager is meant to judge adoption before drilling into a version or a trace.
The screenshots are numbered out of order and the modules are many
Seven screenshots are embedded and their file names run out of sequence. The operations dashboard is number 01, project management and project overview are 02 and 03, and the page access center and AI coding acceptance pair are 04 and 06, while the image numbered 05 appears later on the page, after 06 has already been shown. The names are prefixed with a version directory, which suggests the set was reorganised by hand at some point. The root is similarly unpolished: two editor and run configuration directories sit next to a Maven manifest, with separate SQL, data and deployment directories. Services for capabilities, control, knowledge, models and runtime each have their own directory, alongside a shared common module, a runtime contract module, a managed executor worker, a capability SDK and a Spring Boot starter. The unit of deployment is a module, not the project.
Editorial conclusion
The interesting engineering decision here is the separation between an agent that plans and a workflow that executes a version-pinned graph, with publish validation rejecting a workflow the runtime cannot actually run. That is more defensible than letting the model improvise every call, and the capability annotations with side effect levels and required roles give you something to authorize against. What to verify before adopting it: no releases are published and there is no homepage, so the source tree is the whole distribution; the README is Chinese; and the dependency on JDK 8 compatibility and a Spring Boot 2 starter tells you the target is legacy estate rather than new build. Run it against a demo system first, since it writes through your business APIs.
Frequently asked questions
What is ReachAI used for?
It puts an AI assistant inside existing OA, eHR, procurement and CRM pages so staff can query data, fill forms and process business tasks in natural language without switching systems. The existing pages, identity, permissions, interfaces and business rules stay in place.
How does ReachAI keep an AI assistant from writing data unchecked?
The assistant only calls capabilities already granted to the logged-in user, and operations involving a write, a submission or an approval must be confirmed by the user before execution. Capability declarations carry a side effect level and a set of required roles.
What does a ReachAI scan candidate include?
Six fields: a confirmed fact, a technical inference, an open question, code references, an implementation reference and acceptance criteria. The scan stage itself does not infer business value from names, and at most three candidates are recommended per pass.
Does ReachAI drive the existing web pages like a computer use agent?
Not by its own description. Page interactions go through an explicitly registered action contract for filters, navigation, reads and forms, using a described navigation and ready protocol, and anything that changes real data is routed to a backend capability or business API.
Which Java versions does the ReachAI SDK target?
The SDK is described as compatible with JDK 8 and ships with a Spring Boot 2 starter, which together are aimed at systems that cannot move to a current stack. Systems without code changes are handled by the scanning path instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/w8123-enterpriseagentframework)Star history chart for your README
[](https://hysenlabs.com/projects/w8123-enterpriseagentframework)Was this useful?