Swetrix marks session replays as a Cloud feature, then lists them in the self-hosted edition
📈 Open source, privacy-first web analytics — a cookie-less Google Analytics alternative with built-in error tracking and performance monitoring. Self-host it or use our cloud. Get started for free!
At a glance
- What is it?
- Swetrix is an AGPL-3.0 cookieless analytics project that ships two tracker packages on independent version lines, bundles error tracking and session replays with the traffic stats, and self-hosts onto ClickHouse, Redis, and an S3 bucket. Its own feature list and its self-hosting list disagree about which of those features you get.
- Who is it for?
- Swetrix fits a site owner who wants to drop a small script, get traffic, errors, and performance in one place, and would rather not operate a database. Three things to check before you commit to a mode.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
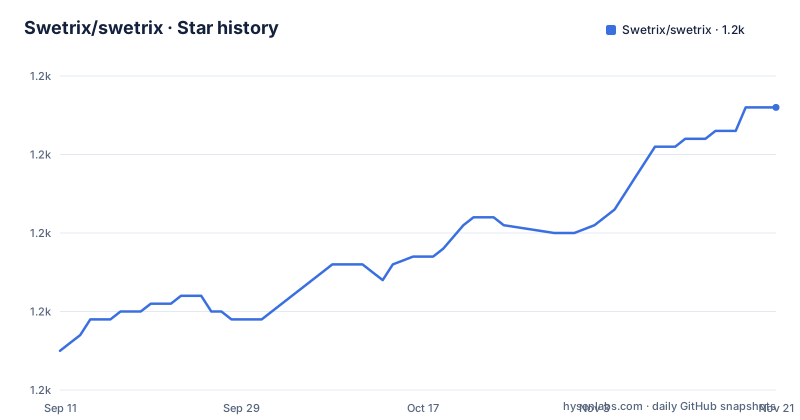
- Swetrix/swetrix1,226 ★ · +31
| Repository | 2026-09-11 | 2026-11-21 |
|---|---|---|
| Swetrix/swetrix | 1.2k | 1.2k |
31 Stars in the last 71 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two tracker packages carry independent version lines
The three most recent releases are scoped packages, not application releases: tracker-node at 3.5.0 and tracker-js at 4.7.0, both on 2026-09-26, and tracker-js at 4.6.1 on 2026-08-29.
So there are two trackers moving on their own schedules, and they are not at the same major version. The browser tracker is on 4, the Node tracker is on 3, and each bumps when that package changes. Nothing in the release list is a tag for the server or the web application, so the version of the platform you are running is not something the tag list tells you.
That split matches the repository layout. The top level holds backend/, web/, packages/, and docs/, and the trackers are the parts of that tree other people install directly. A self-hoster updating the analytics backend from a branch rather than a tag has no release signal for that component at all.
The node tracker at 3.x and the browser tracker at 4.x also means the two halves of the same instrumentation have been on different major lines through the same releases.
The feature list says no cross-device tracking, the table says user profiles
The opening description is emphatic: cookieless, GDPR-compliant, no cookies, no consent banner, no cross-device tracking, all data anonymised.
Then the comparison table against Google Analytics 4 and Plausible has a row labelled user profiles and identified users, and it gives Swetrix a check while marking both of them with a cross.
Both statements are in the README. Read strictly, they describe different things: a cookieless, hash-based way to distinguish one visitor's sessions from another's within a time window is not the same as identifying a person across devices, and neither is the same as storing a profile. But the table row uses the word identified, which is the word a data protection officer would ask about, and the row is presented as a capability comparison rather than as a definition.
Nothing else in the visible text resolves it. There is no sentence saying what a user profile contains or how long it lasts, and no statement of whether one can be reconstructed from the stored fields.
That is the question to put to the project before you rely on either claim. A cookieless dashboard can be genuinely anonymous and still let you count returning visitors, and the two facts are easy to confuse when a marketing table puts them side by side.
Session replays are marked Cloud, then shipped in the self-hosted edition
The feature list annotates some entries with a Cloud tag. Network intelligence is one. Session replays is another. Revenue and MRR analytics and Ask AI are listed in the same way further down.
The self-hosting section then says the Community Edition ships the same core analytics: privacy-friendly traffic stats, custom events, sessions, session replays, funnels, performance, and error tracking.
Session replays appear in both lists. That is a direct contradiction, and the surrounding text supports the self-hosted side rather than the Cloud side: there is a separate documentation page for session replay storage setup, and the deployment instructions say to configure a private S3-compatible bucket for replay recordings. You cannot need a bucket configuration guide for a feature you cannot run.
So the Cloud tag on session replays should be read as a pricing or hosting note rather than as an availability boundary, and the reliable list of what the self-hosted edition includes is the self-hosting paragraph.
Network intelligence, revenue analytics, and Ask AI are not in that paragraph at all. Those three are the ones to verify, because absence from the self-hosting list is the only evidence available that they are Cloud only.
Self-hosting wants ClickHouse, Redis, and an object store, not one container
The deployment description is short enough to read in one breath: deploy the API and UI with Docker, connect ClickHouse and Redis, and configure a private S3-compatible bucket for replay recordings.
Three stateful dependencies before the analytics starts. ClickHouse is the analytical store that a dashboard with real-time filtering and funnels would need. Redis is the layer for the live path. Object storage is for replay video, kept in your own bucket rather than the vendor's, which is the point of a private S3-compatible configuration.
So the self-hosted edition is closer to running a small data platform than to running a single binary. That is normal for this class of tool and it is the main operational difference between the two modes, and it is worth pricing honestly before choosing.
The two documentation links given are the self-hosting guide and the session replay storage setup. The comparison table that would enumerate every other difference between Cloud and the Community Edition begins right after those and is cut off partway through its header, so the full feature-by-feature list is not readable there.
Cloud-only means ISP, organisation, and usage type, which is bot detection by enrichment
Network intelligence is the feature that most clearly reads as a hosted capability rather than a self-hosted one.
It breaks traffic down by ISP, by organisation, by usage type across residential, business, hosting, and cellular, and by connection type, with the stated purpose of spotting bot and datacenter traffic.
That is the interesting part. Cookieless analytics can tell you where a request came from and how it behaves, but distinguishing a datacenter from a home connection needs an external classification of the address. An ISP lookup with a hosting-range list is the mechanism, and hosting ranges change, which is the kind of data that wants maintaining by whoever runs it.
So the feature that makes cookieless traffic data more useful against bots is also the feature that needs a maintained external dataset. If you self-host and bot traffic matters to you, that is the gap to plan around, and it is one the self-hosting description does not mention at all.
The other two Cloud-marked items, revenue and MRR analytics and Ask AI, are closer to the platform's own data, so whether they can be self-hosted is more plausibly a matter of interface work than of external data.
AGPL, bootstrapped since 2021, with Hetzner in Germany and a UK company
The licensing and the funding are both stated directly. The project is AGPL-3.0, open source since 2021, bootstrapped, and funded entirely by subscribers. The cloud is priced from $19 per month after a free trial, and the subscription is described as directly funding maintenance and development of the open-source project.
That is a coherent arrangement for an analytics product: the code is copyleft so nobody can fork a closed version, and the hosted version pays for the work.
The geography is specific enough to matter for a privacy claim. It is made in the United Kingdom and hosted on Hetzner in Germany, and the cloud is described as GDPR-compliant and hosted in the EU. The comparison table leans on exactly that: the EU-hosted row gives Swetrix a check and marks Google Analytics 4 with a warning for sending data to the US.
So the data residency argument is part of the product pitch, which means a self-hoster is making the same argument with their own infrastructure and their own jurisdiction. The AGPL terms apply either way; the EU residency claim only applies if you are on the cloud.
A gitmodules file and a CONTRIBUTING.MD in the wrong case
The top level of the repository holds .github/, .gitignore, .gitmodules, .vscode/, CODE_OF_CONDUCT.md, CONTRIBUTING.MD, LICENSE, README.md, and four source directories: backend/, packages/, web/, and docs/.
The .gitmodules file means at least one dependency is a submodule rather than content in the tree. Combined with docs/ being a top level directory, the documentation site is the likely candidate, which means a clone without submodules has no site, and a fork has to decide whether to track the upstream submodule.
The casing is a smaller version of the same sloppiness. The code of conduct is CONTRIBUTING's neighbour at CODE_OF_CONDUCT.md in lowercase, while the contributing guide itself is CONTRIBUTING.MD in uppercase. On a case-insensitive filesystem that is invisible; on Linux it is two different files, and a link written for one will not find the other.
Neither of these is a design decision. Both are the kind of detail that tells you the repository is maintained by a small number of people doing real work at speed rather than being kept tidy by process.
Editorial conclusion
Swetrix fits a site owner who wants to drop a small script, get traffic, errors, and performance in one place, and would rather not operate a database. Three things to check before you commit to a mode. Which edition you can actually use, because the self-hosting list and the feature list mark different features as Cloud only, and the table that would settle it is not readable in full. What your infrastructure can absorb, since the self-hosted path wants ClickHouse, Redis, and object storage for replays rather than a single container. And whether your data model needs identified users, because the anonymised, cookieless, no-cross-device-tracking description and the user profiles row in the comparison table are not obviously the same claim.
Frequently asked questions
What is Swetrix and what makes it different from Google Analytics?
It is a cookieless, GDPR-compliant web analytics platform that works as a privacy-respecting alternative to Google Analytics, with no cookies, no consent banner, no cross-device tracking, and anonymised data. It adds error tracking, performance monitoring, session replays, funnels, and custom events in the same product.
Can I self-host Swetrix, and what does it need?
Yes, as the Community Edition, which ships traffic stats, custom events, sessions, session replays, funnels, performance, and error tracking. The deployment uses Docker for the API and UI, plus ClickHouse, Redis, and a private S3-compatible bucket for replay recordings.
Is Swetrix open source and how is it funded?
It is AGPL-3.0 and has been open source since 2021. It is bootstrapped and funded entirely by subscribers, with the cloud priced from $19 per month after a free trial, and subscriptions described as directly funding maintenance and development.
Does Swetrix offer user profiles or identified users?
The comparison table against Google Analytics 4 and Plausible lists user profiles and identified users as supported, while the opening description states no cross-device tracking and anonymised data. The visible text does not say what a user profile contains or how long it lasts.
Where is Swetrix hosted and how is it tracked?
The project is made in the United Kingdom and the cloud runs on Hetzner in Germany, described as GDPR-compliant and hosted in the EU. The two tracker packages are published separately as tracker-js and tracker-node, currently at 4.7.0 and 3.5.0.
Which Swetrix features are cloud only?
The feature list marks network intelligence, session replays, revenue and MRR analytics, and Ask AI as Cloud features. Session replays are also listed in the self-hosting paragraph with a separate storage setup guide, so that tag reads as a hosting note rather than an availability boundary, while network intelligence is absent from the self-hosting list.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/swetrix-swetrix)Star history chart for your README
[](https://hysenlabs.com/projects/swetrix-swetrix)Was this useful?