libcimbar, camera-readable barcodes with a 33MB ceiling and a Reed Solomon floor
Optimized implementation for color-icon-matrix barcodes
At a glance
- What is it?
- libcimbar is the C++ encoder behind cimbar.org, a color icon matrix barcode format that pushes files through a monitor and a phone camera without any network. Frames carry fountain-coded and zstd-compressed data, so loss is tolerated, but the file protocol stops at 33MB compressed and the PNG pipeline will happily fill your disk.
- Who is it for?
- Adopt libcimbar when the machines genuinely cannot talk, when the payload is small enough to survive the 33MB compressed ceiling, and when losing a frame is acceptable rather than fatal. Skip it for bulk transfer, for unidirectional one-time secrets, and for any workflow that assumes a native Windows build is as dependable as the Linux one.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
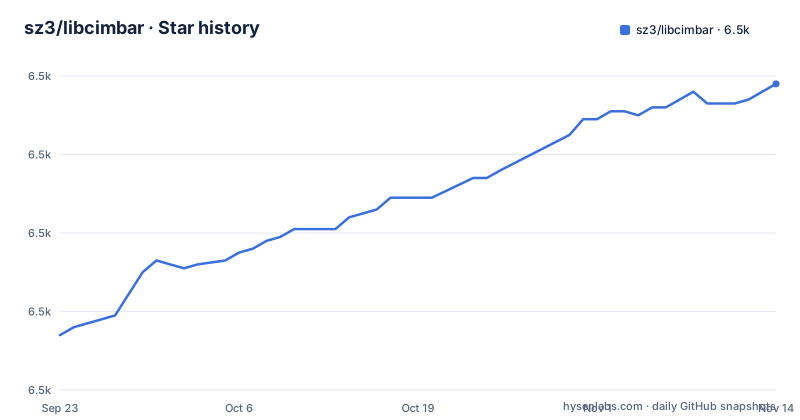
- sz3/libcimbar6,538 ★ · +64
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| sz3/libcimbar | 6.5k | 6.5k |
64 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Bits ride in the tile position and the tile color
cimbar is described as a high density 2D barcode format, and the encoding scheme has two degrees of freedom per cell. Data lives in a grid of colored tiles, where bits are encoded by which tile is picked and by which color draws it. Picking a position and picking a color are separate channels, which is where the density comes from, and it is also why the format depends on a camera rather than a laser: a reader has to resolve both the geometry and the hue of every cell.
On top of that sits Reed Solomon error correction, applied to the data because video to digital decoding is lossy by nature. The project expects sub 1% error rates and corrects them. That number is the practical floor of the whole design: a transfer is a stream of screen frames photographed by a phone, and the error correction budget exists so that ordinary camera noise does not turn into a failed file.
Fountain codes make missing and reordered frames a non event
The file protocol is a separate layer on top of the symbol format. It is built on fountain codes, through the wirehair library, plus zstd compression. A file of up to 33MB after compression is encoded as a series of cimbar codes, and the output can be images or a live video feed.
Because the encoding is rateless, once enough distinct frames have been decoded successfully the file reconstructs and decompresses. The documentation is explicit that this holds even when frames arrive out of order, when some are corrupted, and when some never arrive at all. That is the property that makes an optical link practical: a phone camera drops frames, loses focus, catches a hand in front of the lens, and the decoder does not need a retransmit channel because there is nothing to acknowledge. Nothing here is bidirectional, and nothing retries.
850 kilobits per second between a monitor and a phone
The headline figure the project gives is 850 kilobits per second, about 106 KB per second, sustained using nothing but a computer monitor and a smartphone camera. Two details are worth holding onto. First, the payload crosses an air gap on purpose: no internet, no Bluetooth, no NFC, and every bit travels through the camera lens. Second, a figure that depends on a camera pointed at a screen is a property of the optical setup, not of the CPU, so the number you get will follow your refresh rate, your focus and your room lighting rather than your hardware.
The project calls the format experimental, and the README invites you to try it yourself or take the author's word that it works. Treat the figure as an order of magnitude for planning, not a benchmark.
The encoder is a web page, the decoder is an Android app
The two halves live in different repositories. The encoder runs in a browser: it compiles to asmjs and wasm, which is why cimbar.org needs nothing but a modern web browser. For offline use you can install cimbar.org as a progressive web app, or download the latest release of `cimbar_js.html`, save it locally and open it.
The decoder is a separate cell phone app at github.com/sz3/cfc that reads the animated barcode through the phone camera. That split has a consequence the platform list makes plain: the wasm build is encoder only, and the arm64 Android target is decoder only. So the browser story is complete for producing bars and the phone story is complete for reading them, but neither side covers both directions, and the wasm path has no reader at all.
Building on Linux needs three system packages before cmake
OpenCV and GLFW, plus the OpenGL ES headers, have to be installed first. Everything else is vendored in the source tree. On Ubuntu and Debian that is one command:
sudo apt install libopencv-dev libglfw3-dev libgles2-mesa-devThen the build itself:
cmake .
make -j7
make install
Build products land under `./dist/bin/` by default. The vendored list is long enough to be worth skimming before you start: base, catch2 for the tests, concurrentqueue, cxxopts for the command line tools, fmt, intx, libcorrect, libpopcnt, PicoSHA2 for testing, stb_image for the embedded PNGs, wirehair, and zstd. Two of those names, wirehair and zstd, are the protocol described above, so the dependency list is effectively the data path in list form.
The Windows build names three targets and ships their DLLs
Native Windows goes through Visual Studio with the Desktop development with C++ workload, CMake 3.14 or newer, and vcpkg. You set `VCPKG_ROOT` to the vcpkg checkout and configure from PowerShell:
cmake -S . -B build-windows -A x64 "-DCMAKE_TOOLCHAIN_FILE=$env:VCPKG_ROOT/scripts/buildsystems/vcpkg.cmake"
cmake --build build-windows --config Release --target cimbar_send cimbar_recv cimbar_recv2 --parallel
cmake --install build-windows --config Release
One sender and two receivers get built, `cimbar_send` and `cimbar_recv` plus `cimbar_recv2`, and the executables land with their runtime DLLs under `./dist/bin/`. The included `vcpkg.json` pulls OpenCV, GLFW and ANGLE during configuration, which is why that file exists in the tree. The project states plainly that native Windows is supported on a best efforts basis and that things may be more buggy, with primary development aimed at Linux and Android.
Encoding writes one PNG per frame and the disk pays for it
The command line is four invocations. Encoding takes an input file and an output prefix:
./cimbar --encode -i inputfile.txt -o outputprefixDecoding reads the generated images and writes into a directory:
./cimbar outputprefix*.png -o /tmpA series can also arrive on stdin, which is what makes a pipe between two processes workable:
echo outputprefix*.png | ./cimbar -o /tmpAnd a file can go straight to an animated window instead of to disk:
./cimbar_send inputfile.pdfThe warning attached to encoding is the one operational fact to carry away: large input files may fill up your disk with PNGs. At roughly 106 KB per second of transfer you are asking the encoder to write an image stream that is larger than the file you started from, and there is no documented frame budget or cleanup step.
A pure frontend wrapper pushes past 33MB without touching the C++ tree
The 33MB ceiling belongs to the built-in file protocol, and the project points at a community answer rather than patching it. cimbar-bigfile is a pure frontend wrapper that splits a file into multiple parallel `encode_id` streams of 10 to 15 MB each, and it ships a `manifest.json` for SHA256 verified reassembly. It supports files above 100MB and needs no changes to libcimbar or to the cfc app.
Read that as an architectural statement. The C++ encoder is the hard part and it stays as it is; the multi stream fan out lives in the browser, and integrity is checked through a SHA256 manifest at reassembly. The trade is that you now depend on a tool outside the repository for anything larger than 33MB, and the reassembly step is yours to trust.
Editorial conclusion
Adopt libcimbar when the machines genuinely cannot talk, when the payload is small enough to survive the 33MB compressed ceiling, and when losing a frame is acceptable rather than fatal. Skip it for bulk transfer, for unidirectional one-time secrets, and for any workflow that assumes a native Windows build is as dependable as the Linux one. Verify three things first: that your receiver can run a decoder (the Android app or the Linux command-line build), because the decoder does not exist in the wasm build, that your disk can hold the PNG expansion of your input, and whether the parallel encode_id wrapper you need is already doing the splitting for you.
Frequently asked questions
Is a barcode binary?
In cimbar the payload is binary, and it is encoded twice over per cell: bits are encoded by which tile is chosen and by which color is chosen to draw the tile. Reed Solomon error correction is applied on top, because decoding the video back to data is lossy, and the project expects sub 1% error rates and corrects them.
How fast can libcimbar transfer a file?
The project states a sustained rate of 850 kilobits per second, about 106 KB per second, using a computer monitor and a smartphone camera. No internet, Bluetooth or NFC is involved; every bit goes through the camera lens.
How large a file can libcimbar send?
The built-in file protocol encodes files of up to 33MB after compression into a series of cimbar codes, using fountain codes and zstd. Larger transfers need the community cimbar-bigfile wrapper, which splits the file into parallel encode_id streams of 10 to 15 MB and verifies reassembly with SHA256.
Do I need to install anything before building libcimbar on Linux?
OpenCV, GLFW and the OpenGL ES headers must be installed first; every other dependency is in the source tree. On Ubuntu and Debian the install is sudo apt install libopencv-dev libglfw3-dev libgles2-mesa-dev, followed by cmake, make and make install.
Can libcimbar run entirely in a browser?
The encoder can. It compiles to asmjs and wasm, so cimbar.org works in any modern browser, and for offline use you can install the site as a progressive web app or download cimbar_js.html from the latest release and open it locally. Reading the barcodes is a separate matter: the decoder is the Android app in the sz3/cfc repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sz3-libcimbar)Star history chart for your README
[](https://hysenlabs.com/projects/sz3-libcimbar)Was this useful?