Telegram Media Downloader runs as a robot or a one-shot script on one config.yaml
Based on Dineshkarthik's project. A cross-platform Telegram media downloader with a web UI to view download progress, bot-command-triggered downloads, and support for downloading restricted media from private groups you've joined. Downloads media files from a Telegram conversation, chat or channel, up to 2GiB per file.
At a glance
- What is it?
- Telegram Media Downloader is a Python script that copies media out of Telegram chats, channels and groups, either as a long-running bot or as a single pass. Everything is driven by one config.yaml, and the web page that shows progress is told to bind to every interface on a remote host.
- Who is it for?
- Telegram Media Downloader fits a reader who wants one config file driving both a long-running bot and a single pass over several chats, and who is willing to install the Telegram client from a fork branch rather than a pinned release. It does not fit a packaged desktop app, a browser extension or a signed binary: the repository is a Python script, a Dockerfile and a compose file, and the newest tag is v2.2.5 from January 2025 even though the last push is dated 2026-03-04.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
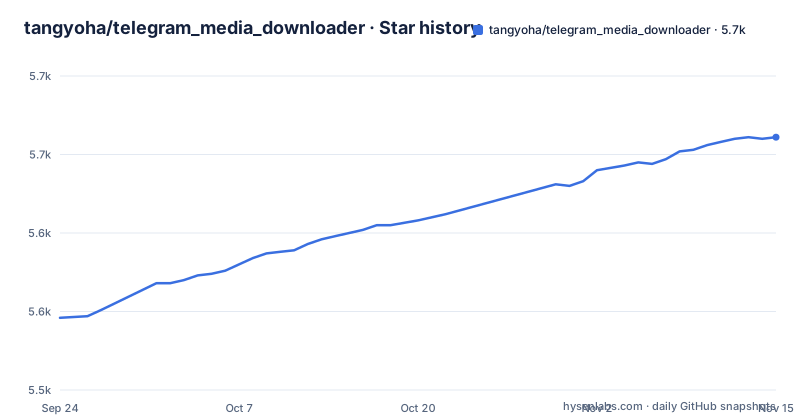
- tangyoha/telegram_media_downloader5,661 ★ · +115
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| tangyoha/telegram_media_downloader | 5.5k | 5.7k |
115 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
make install, pip3, or three wget calls: three ways in
Three install paths are given, and they cost different amounts of work. On a *nix system with make available it is a clone and one target:
git clone https://github.com/tangyoha/telegram_media_downloader.git
cd telegram_media_downloader
make install
On Windows, which has no make built in, the same clone is followed by pip3 install -r requirements.txt. The Docker path pulls a published image and then copies three configuration files by hand:
docker pull tangyoha/telegram_media_downloader:latest
mkdir -p ~/app && mkdir -p ~/app/log/ && cd ~/app
wget https://raw.githubusercontent.com/tangyoha/telegram_media_downloader/master/docker-compose.yaml -O docker-compose.yaml
wget https://raw.githubusercontent.com/tangyoha/telegram_media_downloader/master/config.yaml -O config.yaml
wget https://raw.githubusercontent.com/tangyoha/telegram_media_downloader/master/data.yaml -O data.yaml
Both docker and docker-compose have to be installed first, and the notes name config.yaml and docker-compose.yaml as the files you open with vi afterwards. The first run is meant to stay in the foreground: you type your phone number and the code that arrives, then you exit.
The robot keeps running; the one-shot tool does not
Two default running modes are supported. In the first, the robot stays up and the commands download or forward are issued from it, which needs a bot_token in config.yaml. In the second, the tool downloads as a one-time download tool and exits, so the first mode follows a chat over time and the second makes a single pass over what is in the chat list. Both read the same config.yaml, so the chats, media types, file formats, save path and folder prefix are shared between them. A web page at localhost:5000 shows what a run is doing, and the pinned dependencies behind the stack are flask 2.2.2, Werkzeug 2.2.2 and flask-login 0.6.2, next to rich 12.5.1, loguru 0.6.0, PyTgCrypto 1.2.6, ply 3.11, ruamel.yaml 0.17.21, pycryptodome 3.18.0 and requests 2.32.3. The repository description credits Dineshkarthik's project as its base and states a ceiling of 2GiB per file.
web_host: 0.0.0.0 is the whole remote-access note
For a machine that is not the one at your desk, the only instruction given is to configure web_host: 0.0.0.0. That value binds the web page to every interface. flask-login is in the pinned dependencies, so the code has some form of session handling. If the host sits on a network other people can reach, check who can see the page. The Docker route repeats the choice: docker-compose.yaml maps port 5000 to port 5000 and marks that line as what you need to edit, which means the default publishes the page on the host.
chat_id: four URL shapes and one -100 rule
Before anything downloads, config.yaml needs a chat_id, and the documented way to get one is to open the chat in web.telegram.org on the legacy path and read the p parameter:
https://web.telegram.org/?legacy=1#/im?p=u853521067_2449618633394
https://web.telegram.org/?legacy=1#/im?p=@somename
https://web.telegram.org/?legacy=1#/im?p=s1301254321_6925449697188775560
https://web.telegram.org/?legacy=1#/im?p=c1301254321_6925449697188775560
A u followed by digits and an underscore gives the plain id, so the first line yields 853521067. An @ gives the username itself, somename in the second. The third and fourth start with s and c, and there the rule is to take the digits after the letter and add -100 to the front, turning 1301254321 into -1001301254321. A bot route exists too: @username_to_id_bot resolves almost any user, chat, public or private channel and bot id, from a username, a forwarded message or a pasted joinchat link. The project states it can pull from private groups you have already joined, including resources whose downloading is restricted there.
The sample config and the key reference disagree about ids_to_retry
The printed sample stops mid-setting: upload_drive: is followed by the comment # required and then the fragment enable_upl, while the key reference names the option enable_upload_file, so the line as shown is not the key you are meant to type. The same file also carries the comment note we remove ids_to_retry to data.yaml directly above an empty ids_to_retry: [] list, yet the key reference says of that key to leave it as it is and explains it as the place where the downloader keeps track of skipped downloads so they can be picked up during the next run. data.yaml is fetched only in the Docker route. The rest of the sample is the part worth copying:
api_hash: your_api_hash
api_id: your_api_id
chat:
- chat_id: telegram_chat_id
  last_read_message_id: 0
  download_filter: message_date >= 2022-12-01 00:00:00 and message_date <= 2023-01-17 00:00:00
ids_to_retry: []
media_types:
- audio
- document
- photo
- video
- voice
- animation #gif
file_formats:
  audio:
  - all
  document:
  - pdf
  - epub
  video:
  - mp4
save_path: D:\telegram_media_downloader
file_path_prefix:
- chat_title
- media_datetime
last_read_message_id is the resume cursor: leave it at 0 on the first run and it is rewritten with real numbers after a successful execution, and the reference says not to change it. The download_filter value is an expression over message_date, with a filter page in the wiki for the syntax and gen_filter_cache.py at the repository root for the cache.
file_formats covers three types, media_types covers six
media_types decides what is fetched at all, and the support table names audio, document, photo, video, video_note and voice. The sample config lists a different set: audio, document, photo, video, voice and animation, the last one commented as the gif type. So video_note appears in one list and animation in the other, and neither one explains what happens when a type from the other list is asked for. file_formats narrows the choice further, and only for audio, document and video; the default is all, which downloads all files. The sample limits document to pdf and epub and video to mp4. Below that, save_path is the root directory for everything, and file_path_prefix builds subfolders from chat_title, media_datetime and media_type, where the order of the list is explicitly not fixed and the items combine at will, so two configs carrying the same entries can produce different trees. chat_title falls back to the chat id when a chat has no title.
The Telegram client comes from a fork branch, and rclone rides along
requirements.txt does not take its Telegram client from PyPI. The first live line is an archive of a branch on a fork:
https://github.com/tangyoha/pyrogram/archive/refs/heads/patch.zipThe two lines above it are commented out and point at a v2.0.69 tag and a master_v2.0.69_1 branch, so the client you get is decided by whatever that branch points at, and the file carries no hash to check the download against. The rest is pinned exactly:
PyYAML==5.3.1
rich==12.5.1
PyTgCrypto==1.2.6
loguru==0.6.0
Werkzeug==2.2.2
flask==2.2.2
ply==3.11
ruamel.yaml==0.17.21
flask-login==0.6.2
pycryptodome==3.18.0
requests==2.32.3
aligo 5.4.0 sits commented out at the end. The Dockerfile adds a second moving part: it installs rclone from the Alpine package manager and copies the binary to /app/rclone/rclone, which a comment says matches the code default, then starts the container with python media_downloader.py. docker-compose.yaml mounts $HOME/.config/rclone into the same path, so whatever the upload_drive option needs comes from your own rclone configuration rather than from the image. Upgrading an existing install means running the Windows install command again, pip3 install -r requirements.txt from the project directory.
Four Python version statements, and no tag since v2.2.5
The repository makes four different statements about Python. The support table says Python 3.7 and above, setup.py declares python_requires as ~=3.7, its classifiers stop at 3.11, and the Dockerfile builds on python:3.11.9-alpine. The same setup.py imports setup from distutils.core, takes its version from utils.__version__, declares py_modules as media_downloader, and labels the project Development Status :: 5 - Production/Stable. That label is worth reading next to the tag history: v2.2.3 shipped on 2023-10-30, v2.2.4 on 2024-07-15 and v2.2.5 on 2025-01-06, while the last push to master is dated 2026-03-04 and the repository is not archived. Work has landed in 2026 without a release, and the one version plan linked in the documentation is issue 2 for v2.2.0, left behind by v2.2.5. The files around the script are ordinary: media_downloader.py at the root, gen_filter_cache.py beside it, module/, utils/ and tests/, a media_downloader.spec packaging spec, mypy.ini, pylintrc, a .pre-commit-config.yaml and a dev-requirements.txt.
Editorial conclusion
Telegram Media Downloader fits a reader who wants one config file driving both a long-running bot and a single pass over several chats, and who is willing to install the Telegram client from a fork branch rather than a pinned release. It does not fit a packaged desktop app, a browser extension or a signed binary: the repository is a Python script, a Dockerfile and a compose file, and the newest tag is v2.2.5 from January 2025 even though the last push is dated 2026-03-04. Before pointing it at a chat, check what web_host: 0.0.0.0 exposes on the machine it runs on, and read the ids_to_retry comment in the sample config so you know which file keeps the downloads that were skipped.
Frequently asked questions
How do I use telegram media downloader?
Put api_id, api_hash and a list of chats in config.yaml, choose media_types, and run media_downloader.py. The robot mode also needs bot_token and takes the commands download or forward, and the web page at localhost:5000 shows the progress of a run.
Which media types can Telegram Media Downloader fetch?
The support table names audio, document, photo, video, video_note and voice. The sample config.yaml lists audio, document, photo, video, voice and animation instead, and file_formats narrows audio, document and video further, with all as the default value.
Where does Telegram Media Downloader keep files and session data on Docker?
docker-compose.yaml mounts ./downloads/ to /app/downloads/, ./config.yaml, ./data.yaml, ./log/, ./temp/ and ./sessions/ to their matching paths, and your own rclone configuration directory. The first run stays in the foreground and asks for your phone number and the code.
How do I find a chat_id for Telegram Media Downloader?
Open the chat in web.telegram.org on the legacy path and read the p parameter: a u prefix gives the numeric id, an @ gives the username, and an s or c prefix means taking the digits and adding -100 in front. The bot route is @username_to_id_bot, which resolves users, chats, channels and bot ids.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tangyoha-telegram-media-downloader)Star history chart for your README
[](https://hysenlabs.com/projects/tangyoha-telegram-media-downloader)Was this useful?