TanStack DB is a client store in beta, with five framework examples
The reactive client store for your API.
At a glance
- What is it?
- TanStack DB describes itself as a reactive client store for an API and is currently in beta, with a first release post framing it as an embedded client database for TanStack Query. The repository is a pnpm workspace with five example applications, changesets for releases, and a test script list that names the things that usually break: oracles, minified builds, mangled members and documentation links.
- Who is it for?
- TanStack DB suits a team already using TanStack Query that has endpoint sprawl and slow interactions in a data heavy screen, and that wants collections and live queries rather than another cache. It does not suit a project that needs a stable API today, since the project says it is in beta.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
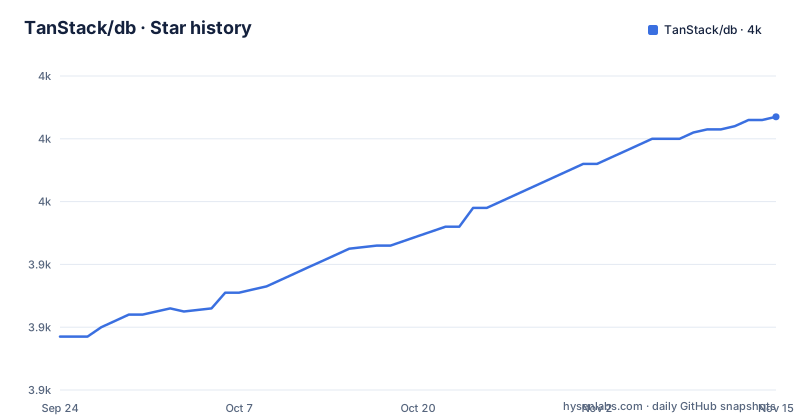
- TanStack/db3,987 ★ · +70
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| TanStack/db | 3.9k | 4k |
70 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is a client store, and the post calls it an embedded database
The one line description is the reactive client store for an API, and the status line above it says the project is currently in beta with a link to a release post for detail. The title of that post is more informative than the description, because it frames the project as an embedded client database for TanStack Query, which places it as a layer underneath an existing data fetching library rather than beside it. That relationship is also how the ecosystem section describes the two projects: the query library is listed for async state and caching, and this one sits as the store that holds what has been fetched. So the honest summary is a synchronised, normalised cache with a query layer on top, and the beta label applies to that combination rather than to a rendering library.
Three problems, and the third is the one that changes an app
The feature list is three bullets and they are ordered by how much they change an application. The first is about data loading: load data into normalised collections to avoid endpoint sprawl and network waterfalls, which is a statement about the shape of your API calls rather than about the database. The second is client performance, claimed as sub-millisecond live queries with real-time reactivity, which is the read path. The third is the interesting one, described as taking the network off the interaction path with instant optimistic writes. That last bullet is the difference between a cache and a store: once writes are applied locally and synchronised, an interaction does not wait for a round trip, and the paragraph under the list repeats the claim in the same order, ending with the assurance that the backend stays simple no matter how much data you load.
Five example applications decide the binding you will actually use
The examples directory is the compatibility statement, and there are five of them, which is more than a library usually keeps current. There is a React example, a Solid example, an Angular example, one for React Native and one for Electron. That spread matters for a project in beta, because it tells you the reactivity layer is not tied to one renderer, and it tells you which surfaces are actually being exercised by the maintainers. The electron example is the odd one out, since a desktop shell is not a browser, and its presence suggests the store is expected to work outside a page. The versioning script makes the same point from the other side, because it updates the example dependencies after a release rather than leaving them to age.
Releases are changesets, and versioning also fixes the examples
The release path is the conventional changeset workflow, and the version script is longer than a publish command. It runs the versioning step, then runs a TypeScript script whose name says what it does, updating the example dependencies, and then installs without a frozen lock file. The reason to do that is that examples in a monorepo carry hard version references to the packages beside them, so a version bump in the core package would otherwise leave the examples pointing at a version that no longer exists. The changelog generator is also configured, pointing at a compact GitHub based format, so the release notes are generated from the changeset descriptions rather than written by hand. The practical consequence for a consumer is that the published version moves often, which the recent tags bear out: three releases on the same day across two packages, one of them a collection package at a very different version number from the framework binding.
The test scripts name the failures that actually happen
Most of the interesting scripts in the root manifest are about breaking in specific ways. One runs oracles in the core package and in the query integration package, which is the property-based testing harness rather than a hand written expectation. One runs the tests against the minified build, which catches the class of bug where a build step renames something a test depended on. One script is named after checking mangled private members, and a private member mangling check is a real hazard for a library that ships types. One verifies documentation links by walking them, and one runs a monorepo consistency tool with two packages explicitly excluded for a dependency conflict. So the list reads like a post mortem of a category of bugs: property violations, minifier surprises, name mangling, dead links and version skew.
The root holds planning files and a domain map
The top level of the repository contains more than a monorepo skeleton, and a few entries are worth knowing about before you dig in. There is a domain map file, which in a project with this many packages is the place where the boundaries between them are recorded. There is a notes directory, an artifacts directory, and three files that read like working documents rather than documentation: a skill specification, a feedback file for a tree generator, and a reconciliation note with a ticket number in its name. There is an agent instructions file, a change set directory, a hook directory for git, and a documentation generator configuration. None of that is documented in the README, and together it says this is a project being built in public with its scratch work committed, which is consistent with a beta label and a first release post rather than a mature package.
Partners are named in the README, not in a dependency list
The README carries a partners table with four companies, and it is worth separating that from a technical claim. Two of the four are infrastructure providers, one is a data platform and one is a tool vendor, which is the usual shape for a project that wants to be in the same conversation as the services a developer is already using. The file then asks for more partners, with a mail link and the word about pushing the boundaries, so the section is an invitation rather than a list of integrations. Nothing in the repository says any of these partners is required, and the dependency story is still the ordinary pnpm workspace with a lock file at the root. The section matters to a reader mainly as a signal about who is investing attention in the project during beta.
Sub-millisecond is a claim in a bullet, not a measurement
The feature list states sub-millisecond live queries, and the closing sentence of the same section claims the app stays fast no matter how much data you load. There is no benchmark, no hardware description and no dataset in the file to support either, which is not a criticism so much as a reading instruction: these are design intentions that the project is asking to be measured against. The observable evidence of activity is elsewhere. The last push to the default branch is dated 2026-10-03 and the repository is not archived, and the release tags show two different version lines moving on the same day, one for a framework binding in its third patch of a zero major and one for a collection package at a much higher patch number, which is the version-scheme consequence of a monorepo where packages are versioned independently rather than in lockstep.
Editorial conclusion
TanStack DB suits a team already using TanStack Query that has endpoint sprawl and slow interactions in a data heavy screen, and that wants collections and live queries rather than another cache. It does not suit a project that needs a stable API today, since the project says it is in beta. Before adopting, read the release post the README links, count how many of your screens are actually read heavy, and remember that the sub-millisecond figure in the feature list is a claim in the README with no benchmark attached.
Frequently asked questions
What is TanStack DB?
A reactive client store for an API, currently in beta. The release post the README links describes it as an embedded client database for TanStack Query, and the project claims it avoids endpoint sprawl and network waterfalls through normalised collections, offers sub-millisecond live queries, and takes the network off the interaction path with instant optimistic writes.
Is TanStack DB production ready?
The README says the project is currently in beta and links a release post for detail, so treat the API as moving. The activity signals are real, with the last push to the default branch in early October 2026 and three releases published on the same day across two packages.
What frameworks does TanStack DB have examples for?
Five: React, Solid, Angular, React Native and Electron. The examples live in the examples directory, and the release script updates their dependencies after a version bump so they do not point at versions that no longer exist.
What is the difference between TanStack DB and TanStack Query?
The README describes them as two layers of the same stack: the query library is listed for async state and caching, and DB is the reactive client store that holds what has been fetched. The release post is titled as an embedded client database for TanStack Query, which frames DB as sitting underneath Query rather than replacing it.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- November 2–8, 2026: Next.js 16.4.5, AI SDK 7.0.165, TanStack AI 1.2dev.to · Nov 8, 2026 · 5 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tanstack-db)Star history chart for your README
[](https://hysenlabs.com/projects/tanstack-db)Was this useful?