Tencent ncnn: from a PyTorch export to two files and named blobs
ncnn is a high-performance neural network inference framework optimized for the mobile platform
At a glance
- What is it?
- ncnn is a C++ inference framework for phones, embedded boards and desktops with no third-party runtime dependencies. Its quickstart gives you a converter and two files, and leaves the runtime library to you.
- Who is it for?
- Adopt ncnn when you are shipping inference into an Android, iOS, HarmonyOS, WebAssembly or embedded target and want a runtime with no third-party dependencies, and accept that you must convert the model with pnnx first. Do not choose it for a CUDA datacentre workload, since the only GPU backend the README names is Vulkan, and do not expect training to happen in it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
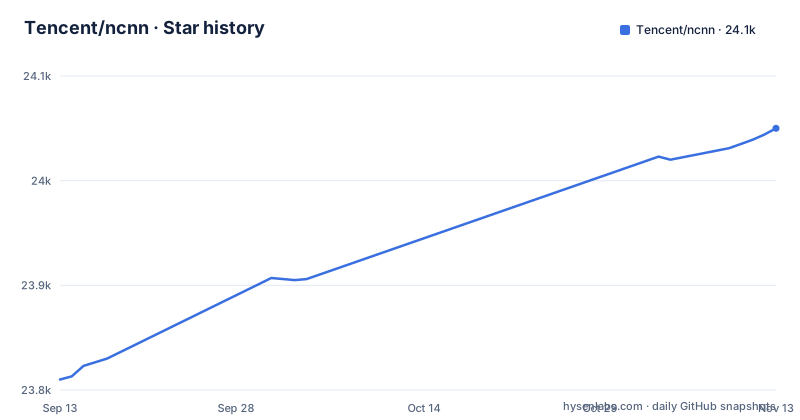
- Tencent/ncnn24,050 ★ · +240
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| Tencent/ncnn | 23.8k | 24.1k |
240 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
in0 and out0: a model is two files with named blobs
A converted ncnn model is not a directory of operators you import. It is a pair of files, model.ncnn.param and model.ncnn.bin, where the param file names the blobs and the bin file carries the weights. Inference then looks like this:
#include "net.h"

ncnn::Net net;
net.load_param("model.ncnn.param");
net.load_model("model.ncnn.bin");

ncnn::Mat in(224, 224, 3);

auto ex = net.create_extractor();
ex.input("in0", in);

ncnn::Mat out;
ex.extract("out0", out);
The blob names in0 and out0 are chosen at conversion time and they are the handle you address the graph with. The Python binding mirrors that sequence and wraps a numpy array in ncnn.Mat:
import numpy as np
import ncnn

net = ncnn.Net()
net.load_param("model.ncnn.param")
net.load_model("model.ncnn.bin")

x = np.zeros((3, 224, 224), np.float32)
mat = ncnn.Mat(x)

ex = net.create_extractor()
ex.input("in0", mat)

ret, out = ex.extract("out0")
print(np.array(out).shape)
Watch the layouts. The C++ sample allocates ncnn::Mat in(224, 224, 3) while the Python sample wraps an array shaped (3, 224, 224). The call names are identical on both sides, so a port between them can be wrong in the one place neither snippet checks, the memory order of the input tensor.
pip3 install pnnx gets the converter, not the runtime
The beginner path the README recommends is PyTorch -> pnnx -> ncnn, and the first command is:
pip3 install pnnxThat installs the converter, which lives in tools/pnnx inside this repository, and it is meant to run inside a PyTorch environment. The export step takes a module in eval mode plus a sample input tuple and writes the two ncnn files:
model = Model().eval()

x = torch.rand(1, 3, 224, 224)
pnnx.export(model, "model.pt", (x,))
What that command does not give you is the ncnn library. The C++ library is either built from source or downloaded as a prebuilt archive from the releases page, and the Python binding lives under python/. Everything after it needs a compiled ncnn matched to your platform and to your GPU backend, which is a different kind of afternoon.
Prebuilt archives repeat the platform name, and only some have a Vulkan twin
Every release publishes archives whose names encode the target. In 20261020 you can see ncnn-20261020-android.zip beside ncnn-20261020-android-vulkan.zip, ncnn-20261020-ios.zip beside ncnn-20261020-ios-vulkan.zip, and pairs for harmonyos, macos, mac-catalyst, tvos, linux, windows, webassembly, watchos and visionos, with separate shared builds for android and harmonyos. The date prefix is the release tag, so pinning 20261020 pins an exact build rather than a promise.
Two gaps in that naming are worth planning around. watchOS and watchos-simulator appear without a vulkan variant while android, ios, macos and tvos have one, so for a watch target there is no GPU archive to pick. Simulator builds are also distinct from device builds, so the iOS device archive is not the one you link into a simulator target. Getting this wrong is the ordinary way people misuse the project, and the archive name is the only warning you get before the link fails.
CPU and Vulkan are the only backends the README names
The README's opening names two backends: CPU and Vulkan GPU, and the build instruction list targets phones, desktops and embedded boards rather than datacentre cards. That is a deliberate trade with a consequence worth stating. On Android or a Raspberry Pi you get GPU acceleration with no vendor runtime to ship, because Vulkan is already there and ncnn itself has no third-party runtime dependencies. On an NVIDIA workstation the GPU route the README names is Vulkan.
The architecture list explains why. Linux, Windows, macOS, Raspberry Pi3 and Pi4, POWER, Android, NVIDIA Jetson, iOS, WebAssembly, AllWinner D1 and Loongson 2K1000 are the platforms the wiki carries build instructions for, which is a fair statement of where this library expects to work.
setup.py takes the build target from environment variables
Cross compiling ncnn does not happen through flags on the setup.py command line. The build script reads a fixed set of environment variables before it does anything else: Vulkan_LIBRARY, CMAKE_TOOLCHAIN_FILE, PLATFORM, ARCHS, DEPLOYMENT_TARGET, five OpenMP variables, ENABLE_BITCODE, ENABLE_ARC, ENABLE_VISIBILITY, and EXTRA_CMAKE_ARGS, which is split on whitespace. On top of that, the install command class adds exactly one user option, vulkan=, with the help text Enable the usage of Vulkan.
That shape matters in CI. A build is reproducible only if the entire environment is pinned, and a single missing variable does not fail loudly, it changes the result: no CMAKE_TOOLCHAIN_FILE leaves the toolchain to whatever CMake picks on the host. The repository layout backs this up with cmake/, toolchains/, glslang, build.sh, build-android.cmd, package.sh and codeformat.sh, plus .clang-format and .astylerc for the C++ sources. Script the environment, not only the command.
The version string is the day you built it
setup.py carries no version number. It opens CMakeLists.txt, pulls NCNN_VERSION_MAJOR and NCNN_VERSION_MINOR out of the text with a regular expression, and appends the current date formatted as %Y%m%d. Two binaries compiled from identical source on different days therefore report different versions, which is awkward the moment you compare a device build against a server build in a log or a bill of materials.
The release tags follow the same habit: 20260113, then 20260526, then 20261020, roughly four to five months apart, each covering android, ios, macos, linux, windows, webassembly, watchos, tvos and visionos, with harmonyos added from 20260526. The repository is not archived and its last push was on 2026-10-04, so work is still landing, and the default branch is master. That is a moving target rather than a release line, so record the archive you shipped instead of the branch you cloned.
examples/ covers nineteen models and ships weights for one
examples/ is the best catalogue of what runs on ncnn: arcface, fasterrcnn, rfcn, retinaface, mobilenetssd, mobilenetv2ssdlite, mobilenetv3ssdlite, shufflenetv2, squeezenet, nanodet, nanodetplus_pnnx, p2pnet, simplepose, scrfd, scrfd_crowdhuman, peleenetssd_seg, piper, ppocrv5 and rvm. The names tell you the field: face detection and recognition, OCR, pose, crowd counting, voice, generic object detection.
What the directory does not hold is weights. The only model data checked in is squeezenet_v1.1.bin with squeezenet_v1.1.caffemodel beside it, and ppocrv5 ships a dictionary header, ppocrv5_dict.h, rather than a model. Every other example expects you to bring a .param and .bin, so the first real task after installing the runtime is producing a converted model with pnnx. There is also a benchmark/ directory at the root.
LICENSE.txt, and questions that go to chat rooms
Two loose ends before something depends on this. Licensing first: a LICENSE.txt file sits at the repository root, while the license field GitHub reports for the project reads NOASSERTION, which is what the index says when it has no license name to hand you. The file's presence tells you terms exist, not what they permit, so open it before ncnn goes into a product you ship.
Second, where a question goes. CONTRIBUTING.md is at the root, and the README routes technical discussion to chat rather than to a tracker: three QQ groups, one of them on MLIR and one created on the grounds that pnnx is underrated, plus a Telegram group at t.me/ncnnyes and a Discord channel. A question that needs to survive, such as a conversion failure on a specific layer, belongs in an issue on the repository with the archive name and the pnnx output attached.
Editorial conclusion
Adopt ncnn when you are shipping inference into an Android, iOS, HarmonyOS, WebAssembly or embedded target and want a runtime with no third-party dependencies, and accept that you must convert the model with pnnx first. Do not choose it for a CUDA datacentre workload, since the only GPU backend the README names is Vulkan, and do not expect training to happen in it. Before committing, open LICENSE.txt, because the license field reads NOASSERTION, and pin a dated archive such as 20261020 rather than the master branch, since setup.py stamps the version with the build date.
Frequently asked questions
What is NCNN used for?
Running already trained deep learning models on phones, PCs, browsers and edge devices. It is an inference framework with no third-party runtime dependencies, running on CPU and Vulkan GPU backends, and it is used inside Tencent applications including QQ, Qzone, WeChat and Pitu. The pnnx tool converts PyTorch and ONNX models into the ncnn format.
How do you install the ncnn runtime?
The README links prebuilt archives per platform on the releases page, such as ncnn-20261020-android.zip and ncnn-20261020-android-vulkan.zip, and links a wiki page covering builds for Linux, Windows, macOS, Raspberry Pi, Android, iOS, WebAssembly and others. pip3 install pnnx installs only the converter.
What files does a converted ncnn model consist of?
Two files: model.ncnn.param and model.ncnn.bin. You load them with load_param and load_model, then address the graph by blob name through an extractor, with ex.input("in0", ...) and ex.extract("out0", ...) in the README's C++ and Python samples.
What license is ncnn released under?
A LICENSE.txt file is present at the repository root, but the license field in the project's GitHub metadata reads NOASSERTION, so no license name is reported there. Read LICENSE.txt for the actual terms before you redistribute ncnn.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-ncnn)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-ncnn)Was this useful?