TheAlgorithms C-Plus-Plus: one objective, several implementations, no canonical pick
Collection of various algorithms in mathematics, machine learning, computer science and physics implemented in C++ for educational purposes.
At a glance
- What is it?
- A tree of C++17 algorithm implementations with no external libraries and a self-check inside each program, aimed at educators and students. Useful as readable reference source, useless as a dependency you can pin.
- Who is it for?
- Adopt it when you are teaching an algorithm, want a readable reference implementation with nothing to install, or need a starting point you can paste into a scratch file. Do not adopt it as a library: there is no tagged release to depend on, no stable API across files, and the same objective can have several implementations with nothing marking one as the reference.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 42 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
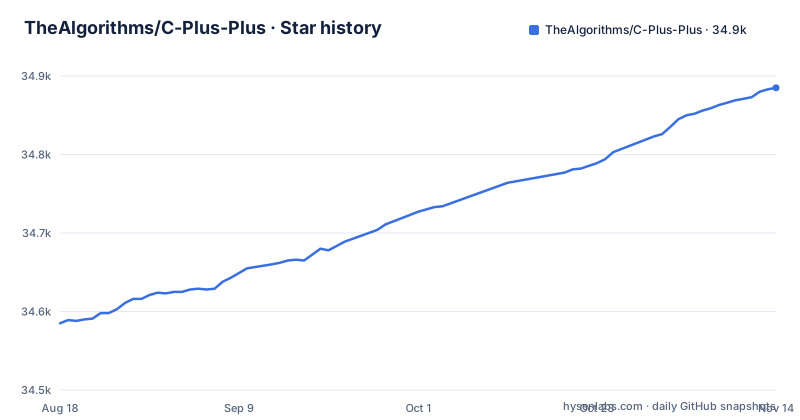
Star history
- TheAlgorithms/C-Plus-Plus34,885 ★ · +300
| Repository | 2026-08-18 | 2026-11-14 |
|---|---|---|
| TheAlgorithms/C-Plus-Plus | 34.6k | 34.9k |
300 Stars in the last 88 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One objective can have several implementations, and none is marked canonical
Reading TheAlgorithms C-Plus-Plus starts with a decision the repository refuses to make for you. The overview says plainly that you may find more than one implementation for the same objective, differing by strategy and optimization. Open sorting/ or graph/ looking for one technique and you can land on several files, with nothing in the tree marking one as the reference, because the folders are organised by algorithm family rather than by problem. That choice makes sense for teaching, where reading two sorts side by side is the entire point. For someone who wants to copy one function into a project it becomes work: you read the candidates yourself, and the only correctness signal a file carries is the self-check its author put inside that program. The repository documents no shared suite across files, so passing one tells you nothing about its neighbour.
No external libraries means the machine_learning folder has no linear algebra under it
Every file here is atomic. The stated rule is that each source uses STL classes and needs no external library to compile and run, and that is what lets a single .cpp file be copied out of the tree and built on its own. The same rule sets the ceiling. In machine_learning/ and numerical_methods/ there is no tensor library, no BLAS and no autograd, so a linear algebra routine in those folders is readable hand written code rather than a call into a tuned kernel. Two consequences follow. The first is that what these files cost is comprehension rather than throughput: you can follow every line, but a production program wants the library. The second is that reuse is a copy and adapt job. The overview says the modular implementations and the open source licensing let the functions be used in other applications, and for a single function that holds. For a codebase that wants a pinned, versioned algorithm library, a folder of standalone programs is the wrong shape, since there is no header to include and no version string to depend on.
The build matrix covers three desktop compilers, not the ESP32 and Cortex targets
Portability is the claim the README leans on hardest. Strict adherence to the C++17 standard is what lets the code move to embedded targets such as ESP32 and ARM Cortex with little to no changes. The test matrix tells you what that claim is checked against: source codes are compiled and tested for every commit on the latest versions of three operating systems, Windows, macOS and Ubuntu, using MSVC 19 2022, AppleClang 15.0.15 and GNU 13.3.0 respectively. Neither embedded target appears in that list. So the portability claim rests on the language standard the files follow, not on anything the continuous integration demonstrates, and an ARM or ESP32 user inherits an untested assumption. Strict adherence to C++17 also means the files are not free to reach for newer language features, and those three compilers are the only toolchains where a fix gets verified.
MIT covers the code, CC BY-SA 4.0 covers the generated documentation
Two licences sit on one tree and they do not cover the same thing. The code is MIT, which is the one that matters if you lift a function into a product, and the practical obligation is to carry the copyright and the licence notice along with the copy. The generated documentation carries a different licence, CC BY-SA 4.0, and the documentation page states that itself. A share-alike term on documentation does not reach back into the MIT code, though pasting explanatory text from the site into your own internal docs is a different question from copying a .cpp file, and the two places to look are LICENSE for the code and the licence line on the documentation site. That documentation is generated from the repository source codes directly, so there is no separate docs tree to fall out of date. The other side of that arrangement is that page quality equals comment quality, and a thin comment produces a thin page that nobody notices.
Thirty topic folders, DIRECTORY.md, and no build command anywhere
There is no install step, and the README does not give a build command. This is a repository you read and copy from rather than a package you add to a project, so the useful question is where the code sits. It sits in about two dozen topic folders at the root: math/, sorting/, graph/, dynamic_programming/, machine_learning/, physics/, ciphers/, numerical_methods/, range_queries/, strings/ and the rest, with DIRECTORY.md acting as the index. The generated documentation at TheAlgorithms.github.io/C-Plus-Plus carries the same files, and its Files menu lists every documented file, so you can browse the documented files by name when you do not know which folder a function belongs to. Sitting around the code are the pieces contributors need and users do not: CMakeLists.txt, .clang-format, .clang-tidy, scripts/, .vscode/ and a doc/ folder. If you want to see one of these programs work, the documented check is the self-check inside the program itself, which makes the compiler on your machine the only setup step involved.
No GitHub releases, so a commit hash is the only version reference
The repository has no GitHub releases, so nothing in it carries a version number you can depend on. The last push to master was on 2026-10-03, which tells you the tree is being worked on and nothing at all about whether a particular file was reviewed carefully. If you vendor a file, the only reference you get is a commit hash, and there is no changelog to read when you want to know what moved in it. For a one-off read of a sorting routine that is harmless, since the copy you keep is the whole dependency. For anything you plan to track over time it means re-reading the file on every pull or freezing your own copy and drifting from upstream. The root does carry .gitpod.yml and .gitpod.dockerfile, and the README links a Gitpod badge, which is the closest the project comes to a ready made environment. What sits inside that environment is defined by those two files, and the README does not enumerate its toolchain.
Against the standard library, the trade is specification against visibility
For sorting, searching and data structures the honest comparison is with the C++ standard library, which these files themselves call. The standard library is specified, versioned with your toolchain, and covered by guarantees you can rely on without reading its source. A file in sorting/ gives you the opposite trade: the algorithm in front of you, in the language, with the reasoning visible, which is the point when you are learning it or when you need to change one step. The gap closes fast as your reason changes. If you need a guaranteed implementation, take the standard library. If you need to watch the algorithm run, this repository is the better read. The same split applies in machine_learning/ and numerical_methods/, where the alternative is a linear algebra library with tuned kernels and a documented interface, and what you get here is loops you can follow line by line. Neither choice is wrong, and the mistake to avoid is shipping a teaching file on a production path because it happened to be the first result.
Editorial conclusion
Adopt it when you are teaching an algorithm, want a readable reference implementation with nothing to install, or need a starting point you can paste into a scratch file. Do not adopt it as a library: there is no tagged release to depend on, no stable API across files, and the same objective can have several implementations with nothing marking one as the reference. Before you rely on a file, open CodingGuidelines.md and REVIEWER_CODE.md, which sit at the repository root, and check that the copy you took has the self-check you expect.
Frequently asked questions
Do TheAlgorithms C-Plus-Plus files need any libraries to compile?
No. Each source is atomic and uses STL classes, and no external libraries are required for compilation and execution. That is what lets you copy a single file into your own project and build it on its own.
How do I get the code from TheAlgorithms C-Plus-Plus?
There is no install command, since this is a repository of programs rather than a package. The source lives in the topic folders at the root, indexed by DIRECTORY.md, and the same files are published as generated documentation at TheAlgorithms.github.io/C-Plus-Plus with a Files menu listing every documented file.
Which C++ standard and compilers do TheAlgorithms C-Plus-Plus target?
The files adhere strictly to C++17 and are compiled and tested on every commit across Windows, macOS and Ubuntu, using MSVC 19 2022, AppleClang 15.0.15 and GNU 13.3.0. That matrix does not include the embedded targets such as ESP32 and ARM Cortex that the portability claim names.
Can I reuse a TheAlgorithms C-Plus-Plus implementation in a commercial project?
The code is MIT licensed, so keep the copyright and licence notice with anything you copy out of it. The generated documentation is under CC BY-SA 4.0, a separate licence that applies to the docs rather than the source, so check LICENSE and the documentation licence line before reusing either.
Does TheAlgorithms C-Plus-Plus have versioned releases I can depend on?
No, the repository has no GitHub releases. The only version reference available for a file you take is the commit it came from, and the last push to master was on 2026-10-03.
How do I know a TheAlgorithms C-Plus-Plus implementation is correct?
Each program carries self-checks inside it, and that is the documented correctness signal. The README documents no shared test suite across files, and the same objective can have more than one implementation using different strategies, so verifying one file says nothing about another.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thealgorithms-c-plus-plus)Star history chart for your README
[](https://hysenlabs.com/projects/thealgorithms-c-plus-plus)Was this useful?