agent-memory keeps its claims in a benchmark table and its keys out of the library
Long-term memory runtime for AI agents — plain Markdown as the source of truth, local ranked retrieval, and an independent sleep-time Manage layer. Claude Code and Codex share one store. No API key.
At a glance
- What is it?
- agent-memory is a long-term memory runtime for AI agents where Markdown files are the source of truth, a SQLite index beside them is a deletable cache, and a sleep-time Manage layer proposes deletions instead of performing them. Two details decide whether it fits your setup: there are no GitHub releases, and the environment sample carries four variables beyond the store path, including an OpenAI key, which the library claims not to need.
- Who is it for?
- agent-memory fits a setup where the memory store is something you want to read, grep, diff and put in git, and where the host agent can run a shell command. Two things to weigh before adopting it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
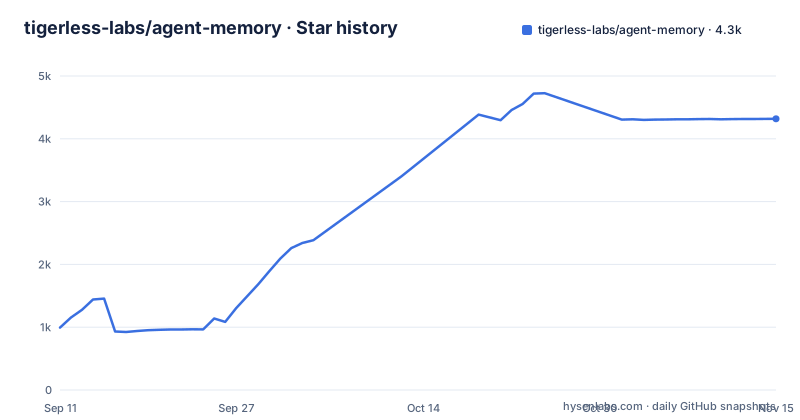
- tigerless-labs/agent-memory4,319 ★ · +3,326
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| tigerless-labs/agent-memory | 993 | 4.3k |
3,326 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
There are no GitHub releases, and 0.1.0 is the only version number
The repository publishes no releases at all, and the branch itself was pushed to on 2026-10-30. The one version in the tree is 0.1.0, declared in a root project named agent-memory-workspace whose description is an agent-agnostic, local-first long-term memory runtime. That root depends on three siblings from a uv workspace, agent-memory-core, agent-memory-cli and agent-memory-adapters, with members taken from packages/*. Five optional extras exist: an MCP server, an executor, a harness, and vector and cjk extras that pull core variants. So what you install is one of seven names, and the memory store path itself is a single environment variable, AGENT_MEMORY_STORE, shown with a home-relative value. Pinning an install means pinning a commit.
Recall answers with paths, and reading has five rungs
The retrieval verb does not paste text into the context window. It returns an L0 list where each entry is a one-line abstract, a file path, an anchor and a score, eight entries by default, and the agent then opens only what it needs:
mem recall "why files instead of a database"    # L0 list, 8 entries by default
mem recall "why files instead of a database" --limit 20  # more Memory candidates
mem read <name> --level outline                 # headings only; or abstract, or full
mem context "why files instead of a database"   # both in one call, top few expanded in full
mem trace <name>                                 # cited raw messages, when needed
The rungs are the index line, then the abstract, then the full file, then the raw material, and a long file adds two more that are free: the anchor that matched, and an outline computed at read time. Behind the recall verb sit three tracks, so a miss on one is not a miss: a deterministic MEMORY.md injection at session start, BM25 over an FTS5 index with an optional vector plugin fused in by reciprocal rank fusion, and the plain directory tree reachable with ls and grep.
The store diagram stops mid-word in the archive listing
The store is described as a tree, and the description reads as a contract. At the root sit MEMORY.md, a one-line-per-memory index that is the only thing injected into a session, and config.toml, which holds every tunable and refuses an unknown key at load time. Then schemas/, one file per type carrying its key fields, the field it groups by and its write mode. Then the memories themselves, placed by the schema at type, group and name, with a worked example path for a memory about Markdown files being the source of truth. Then archive/, which is append-only and outside the retrieval surface by default. Its listing includes provenance/, annotated as distillation evidence.
The index is a cache, and a test is what makes that true
The design commitment here is unusually specific: files are the truth and every index is a rebuildable cache. The claim is checkable by hand, with rm -rf .index/ followed by mem rebuild, and the README is explicit that this loses zero knowledge and that the property is enforced by a test rather than promised in a document. What sits under the Markdown is SQLite in an FTS5 configuration for the BM25 track, plus a vector plugin that is an optional extra rather than a default. The same layering explains the neighbouring claim that the read path calls no model and crosses no network: judgement is borrowed from the host agent's own command line tool, which is also why every write stays visible in your transcript.
Deletion only ever arrives as a proposal you confirm
The Manage layer runs on its own clock, at a sleep-time pass, separate from the write path, and it has authority tiers. An unattended pass may add and update; deletion does not have that authority and arrives as a proposal. Superseding leaves the chain intact rather than rewriting history, which is backed by validity fields in the frontmatter: a valid_from timestamp and an optional invalid_at. Replaced and deleted files stay in the store so that recall --as-of can answer as of a date, while current recall, the MEMORY.md index, BM25 and the vector track all use only files without an invalid_at. Existing files carrying a status field load without needing a reset, so an older store is not a migration.
Link editing is all or nothing, and the MCP surface mirrors it
Relations are expressed as links in the frontmatter rather than in a graph database, and explicit links have to name distinct active memories inside the same store. The editing verbs treat that list as a whole. `mem correct --link` replaces the entire list, and `mem correct --clear-links` removes every link. The MCP tool memory_correct does the same two things with links: [...] and links: []. The rule that matters in practice is what happens when you leave links out: omitting the field preserves historical relationships during an otherwise unrelated correction, so a typo fix does not silently unhook a memory from its neighbours. The reasoning behind that boundary is written up separately in docs/design/management-operation-boundaries.md.
The benchmark table arrives with its own caveat attached
The proof section publishes numbers and then explains what they do not mean. The setup is LongMemEval-S with a bounded haystack, 120 episodes, `claude -p` with Haiku 4.5 as the host, one calibrated Sonnet 5 as judge, and two exam replays per arm. The pooled accuracy row for agent-memory W2 is 127 out of 240, or 52.9 percent, against 86 out of 240 for a MemCore W2 arm, with paired counts and p values of 0.009 and 0.004, and 7 out of 120 for a no memory arm. The caveat is stated in the same breath: these absolute numbers are not comparable to published LongMemEval scores because the haystack is bounded to twelve sessions per episode, which makes this a study of write strategy rather than of corpus size, and the system-to-system row differs in write and read together.
The library needs no key, and the sample environment lists four
The headline is that none of it needs an API key, and the claim is scoped to the library: there is no LLM client inside it, so there are zero keys to install and no billing surface. The environment sample complicates the picture. It contains four variables that have nothing to do with the store path: a Google Cloud project, a location pinned to global, a model name under HERMES_MODEL, and an OpenAI key. The vector track is an extra, the benchmark used hosted models as both host and judge.
Editorial conclusion
agent-memory fits a setup where the memory store is something you want to read, grep, diff and put in git, and where the host agent can run a shell command. Two things to weigh before adopting it. There are no GitHub releases and the only version number lives in the workspace root manifest, so pin your install by commit rather than by tag. And the no API key promise covers the library, not your environment: the sample file carries a cloud project, a location, a model name and an OpenAI key, and the published benchmark used a hosted model as both host and judge. Read the benchmark's own caveat before quoting its numbers, because the author states the haystack is bounded and that the comparison row differs in write and read at the same time.
Frequently asked questions
What does agent-memory use as the source of truth?
Markdown files in one store, with a SQLite index beside them acting as a cache that can be deleted and rebuilt with mem rebuild. Current recall, the MEMORY.md index, BM25 and the vector track all read files that carry no invalid_at timestamp.
How does agent-memory handle deleting a memory?
An unattended sleep-time pass may add and update, but deletion only ever arrives as a proposal you confirm. Supersede leaves the chain intact, and recall --as-of can answer as of a date because replaced and deleted files stay in the store.
Does agent-memory need an API key to run?
The library itself embeds no LLM client, so it needs no key. The sample environment file still lists a Google Cloud project, a location, a model name and an OpenAI key, and judgement is borrowed from the host agent's own command line tool.
How is the agent-memory recall output shaped?
Recall returns an L0 list where each entry is a one-line abstract, a file path, an anchor and a score, eight entries by default and adjustable with --limit. Deeper reading is a separate call: mem read with a level of outline, abstract or full, plus mem context and mem trace for cited raw messages.
How do I change links between agent-memory memories?
The link list is edited as a whole. mem correct --link replaces the full list and mem correct --clear-links removes every link, and the MCP tool memory_correct does the same with links: [...] and links: []. Omitting links preserves existing relationships during an unrelated correction.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tigerless-labs-agent-memory)Star history chart for your README
[](https://hysenlabs.com/projects/tigerless-labs-agent-memory)Was this useful?