TimescaleDB: a local-only installer script, port 6543 everywhere, and an HA image on PostgreSQL 18
A time-series database for high-performance real-time analytics packaged as a Postgres extension
At a glance
- What is it?
- TimescaleDB is a PostgreSQL extension for time-series and event data, and its quick start is written for a laptop rather than a server: a piped shell script marked local-development only, a non-standard port to dodge an existing PostgreSQL, and a Docker tag that pulls the HA image on PostgreSQL 18. Some of the sample SQL does not quite agree with the prose around it.
- Who is it for?
- TimescaleDB suits developers who want time-series behaviour inside an existing PostgreSQL rather than a second datastore, and who can accept that the fast path to a running instance is a local convenience rather than a deployment recipe. It does not suit anyone starting from the project page alone, because the one command that looks like an installer is explicitly refused for production, and the production path in the quick start is a documentation link rather than steps.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
Star history
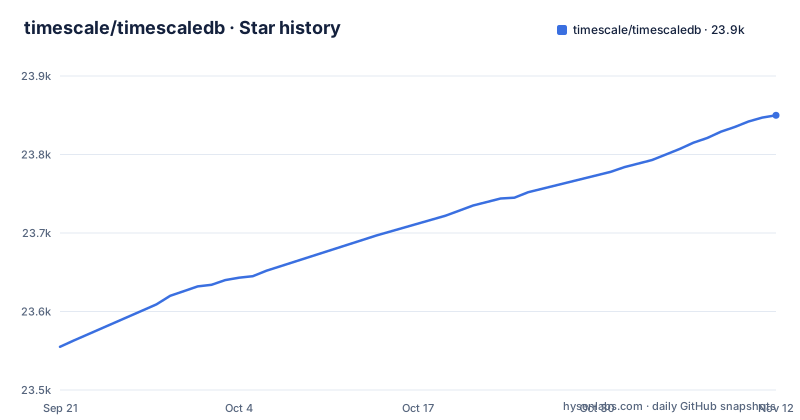
- timescale/timescaledb23,850 ★ · +295
| Repository | 2026-09-21 | 2026-11-12 |
|---|---|---|
| timescale/timescaledb | 23.6k | 23.9k |
295 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The one-line installer is refused for production in the same breath
The recommended way to start is one line:
curl -sL https://tsdb.co/start-local | shSitting directly above it is a warning that this script is intended for local development and testing only, and that it should not be used for production deployments. Production-ready options are a documentation link away, in the TimescaleDB installation guide under `docs.timescale.com/self-hosted/latest/install/`, and the quick start gives that link rather than production steps.
The script is worth understanding rather than just avoiding. It downloads and starts TimescaleDB if it is not already downloaded, exposes PostgreSQL on port 6543, tunes settings for your environment using `timescaledb-tune`, and sets up a persistent data volume.
The gap is deliberate but easy to skim past. A quick start that pipes a remote script into a shell and hands you a tuned, volume-backed database is a good way to evaluate the product and a bad way to provision a server, and the page says the second thing in a blockquote rather than in the flow of the instructions.
Port 6543 on the host side, because 5432 is already in use
Every connection detail in the quick start uses port 6543, and the reason is stated twice: 6543 is a non-standard port chosen to avoid conflicts with other PostgreSQL instances already running on 5432.
In the Docker route the mapping is what makes this work. The container listens on 5432 and the host publishes 6543:
docker run -d --name timescaledb \
    -p 6543:5432 \
    -e POSTGRES_PASSWORD=password \
    timescale/timescaledb-ha:pg18
The client side then follows, and it is the same for the command line and the GUI:
psql -h localhost -p 6543 -U postgresIf you prefer a graphical client, pgAdmin uses the identical details, host `localhost`, port `6543`, user `postgres`.
The consequence is mechanical but catches everyone once. Anything you connect with that assumes the standard port will fail, including a connection string copied from another tutorial, a GUI that pre-fills 5432, and a tool that reads `PGPORT` from the environment. It also means container port 5432 and host port 6543 are not interchangeable, which confuses people who move between the Docker route and the script route.
The quick start pulls the HA image, and the Postgres version is in the tag
The Docker command names `timescale/timescaledb-ha:pg18`. Two decisions are packed into that one string.
The first is the variant. The image is the HA one, and it is chosen in the very first command on the page, before you have chosen a topology.
The second is the PostgreSQL version, which lives in the tag rather than in a configuration step. Upgrading your database major version later means changing this tag, and the quick start does not say which major versions are supported or how the extension version tracks them.
Verification is a single query against the extension catalogue:
SELECT extname, extversion FROM pg_extension WHERE extname = 'timescaledb';The expected output shown is a single row, `timescaledb` with a version of the pattern `2.x.x`. Note what that pattern tells you: it confirms the extension is loaded, but it deliberately does not pin the exact build, so a version mismatch between two environments will not show up in this check.
The hypertable step promises columnstore and the SQL does not mention it
The quick start announces that you will create your first hypertable with columnstore enabled, and the surrounding prose talks about writing directly to the columnstore. The statement it gives you is this:
CREATE TABLE sensor_data (
    time TIMESTAMPTZ NOT NULL,
    sensor_id TEXT NOT NULL,
    temperature DOUBLE PRECISION,
    humidity DOUBLE PRECISION,
    pressure DOUBLE PRECISION
) WITH (
    tsdb.hypertable
);
The only option present is `tsdb.hypertable`, which the page explains converts the table into a TimescaleDB hypertable. There is no columnstore option in the statement, even though the step heading says one is enabled and the insert step that follows is specifically about columnar writes.
The links attached to this step split the difference: one is about hypertables, one is about columnstore, and one is titled enable columnstore manually. That last title is the tell. A reader who follows the heading expects a columnstore key in the `WITH` clause and will not find one, and the page routes them to the manual path instead of showing the automatic one. On the build shown here, the columnstore behaviour arrives through the session setting in the next step.
Direct columnar writes are off until a session setting turns them on
The insert step opens by switching on direct compression inserts:
SET timescaledb.enable_direct_compress_insert = on;The comment next to it is explicit that this is what lets you insert data straight into the columnstore, in columnar format, for performance. Without it the same `INSERT` runs, the same rows land, and the query that follows still returns the right numbers.
That is the problem. This is a session setting, not a database-wide or table-level one, so it travels with the connection rather than with the schema. A connection pool that opens sessions without issuing the statement, or a second application sharing the database, will write the other way, and the table still looks correct. Nothing in the output of a `SELECT COUNT(*)` distinguishes the two paths.
If columnar write format matters to your sizing or your write costs, the check is not the row count. It is whether the setting is issued on every connection that inserts, which is a property of your pool configuration rather than of the database.
The sample generator claims ten sensors and its arithmetic produces nine
The sample data step says it generates roughly 7,776,001 readings across 10 sensors over the past 90 days. The row count is right. Ninety days at one second per step is 7,776,000 intervals, and `generate_series` from `NOW() - INTERVAL '90 days'` to `NOW()` inclusive adds one more.
The identifier expression is `'sensor_' || ((random() * 9)::int + 1)`. `random()` returns a value below 1, multiplying by 9 gives a value below 9, and PostgreSQL's cast to int rounds rather than truncates, giving 0 through 9; adding 1 gives 1 through 10. That is ten distinct identifiers, matching the prose, although sensor_1 and sensor_10 each receive about half as many rows as the others.
If you write a cardinality assertion against the sample, expect ten groups, but do not assume an equal row count per sensor.
Compression is quoted as 90% or better, typical rather than guaranteed
The page describes four things happening underneath: data is partitioned into time-based chunks, writes go directly to columnstore using columnar storage with 90%+ compression typical and faster vectorized queries, queries scan only the relevant time ranges and columns, and `time_bucket()` is available for time-series aggregation.
The word doing the work in that compression claim is typical. It is not a bound, and it is not attached to a workload description, so it cannot be used to size a volume. What it tells you is the order of magnitude the author expected, and the honest reading is that your ratio depends on your column types and how repetitive your data is.
The second mechanism, continuous aggregates, is described more precisely and is a different kind of object. They continuously and incrementally refresh a query in the background, so running such a query only computes the data that has changed rather than the entire dataset, which is stated as the difference from regular PostgreSQL materialized views. The cost is that they are something you create and maintain, and the quick start only reaches them as a next step.
Building the extension means CMake, a control file template, and Coccinelle
The repository is a C extension built against PostgreSQL, and the top level shows how. There is a `CMakeLists.txt` and a `cmake/` directory, alongside `bootstrap` and `bootstrap.bat` shell scripts, which is the pair for Unix-like systems and Windows. A `coccinelle/` directory sits next to them, and Coccinelle is a tool that rewrites C source rather than compiling it.
Two smaller files explain the packaging. `timescaledb.control.in` carries a `.in` suffix, the convention for a template that gets configured at build time, which is how a PostgreSQL extension declares itself to the server. `version.config` sits beside `CHANGELOG.md` and an `.unreleased/` directory, so the version is configured rather than hard-coded and pending changes are collected as fragments.
Editorial conclusion
TimescaleDB suits developers who want time-series behaviour inside an existing PostgreSQL rather than a second datastore, and who can accept that the fast path to a running instance is a local convenience rather than a deployment recipe. It does not suit anyone starting from the project page alone, because the one command that looks like an installer is explicitly refused for production, and the production path in the quick start is a documentation link rather than steps. Before you build on it, confirm the Postgres major version in the image tag matches your cluster, remember the columnstore insert behaviour is a session setting that a pooled connection can silently miss, and treat the compression figure as a typical case rather than a bound you can size against.
Frequently asked questions
What is TimescaleDB used for?
It is a PostgreSQL extension for high-performance real-time analytics on time-series and event data. It partitions data into time-based chunks, supports columnar storage in the columnstore with 90%+ compression described as typical, and provides `time_bucket()` for aggregation plus continuous aggregates that refresh incrementally.
Is TimescaleDB a PostgreSQL extension?
Yes. The quick start verifies it by querying the extension catalogue with `SELECT extname, extversion FROM pg_extension WHERE extname = 'timescaledb';`, and the repository carries `timescaledb.control.in`, the control file template PostgreSQL extensions declare themselves with.
how to install timescaledb
The page offers two local routes, and warns that the one-line script is for local development and testing only. One is `curl -sL https://tsdb.co/start-local | sh`, the other is a `docker run` of `timescale/timescaledb-ha:pg18` with port 6543 mapped to the container's 5432. Docker, 8GB of RAM and a PostgreSQL client are the stated prerequisites, and initialization takes one to two minutes.
how to check timescaledb version
Query the extension catalogue: `SELECT extname, extversion FROM pg_extension WHERE extname = 'timescaledb';`. The expected output on the page is a single row for `timescaledb` with a version of the pattern `2.x.x`, which confirms the extension is loaded without pinning an exact build.
is timescaledb free
The repository ships a `LICENSE` file, a `LICENSE-APACHE` file and a `NOTICE` file, while the project's own licence metadata is reported as `NOASSERTION`. The project also runs a commercial cloud with a separate sign-up console, so what the extension permits and what the hosted service charges for are two different questions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/timescale-timescaledb)Star history chart for your README
[](https://hysenlabs.com/projects/timescale-timescaledb)Was this useful?