gplearn: symbolic regression behind a scikit-learn estimator API
Genetic Programming in Python, with a scikit-learn inspired API
At a glance
- What is it?
- trevorstephens/gplearn is a BSD-3-Clause Python package for genetic programming, deliberately narrowed to symbolic regression and shaped to drop into scikit-learn pipelines and grid searches. Its own metadata calls it Alpha, its Python requirement has no ceiling, and its version is read out of the package source at build time.
- Who is it for?
- gplearn fits a tabular problem where you want a readable formula rather than a model you cannot inspect, and where you want to try it the same way you try every other estimator, inside a pipeline and a grid search over its parameters. It does not fit a task that needs general genetic programming, since that scope was refused on purpose, and it does not fit an environment pinned to an older scikit-learn, because the dependency floor is 1.8.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 93 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
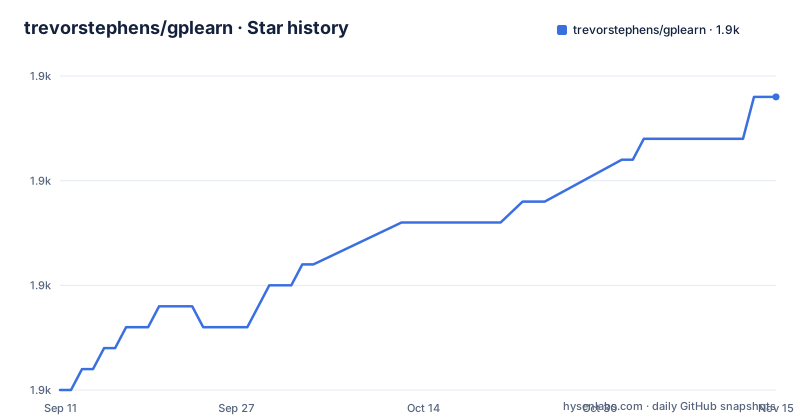
- trevorstephens/gplearn1,899 ★ · +14
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| trevorstephens/gplearn | 1.9k | 1.9k |
14 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Genetic programming, narrowed to symbolic regression
Genetic programming in general can be pointed at a very wide range of tasks, and this project declines most of them. The stated reason is the scikit-learn ethos of having powerful estimators that are straightforward to implement, so the scope is deliberately held to symbolic regression, the technique that looks for a mathematical expression describing a relationship between known inputs and a target. The mechanism is the standard one: start from a population of naive random formulas standing in for that relationship, then evolve generation by generation, selecting the fittest individuals from each population to undergo genetic operations and become the next one. What the package adds is not the evolutionary loop but the packaging. It exposes that machinery as an estimator with parameters, so the difference between a working setup and a broken one is configuration rather than a research project.
Three estimators, and the transformer carries a caveat
Three estimators cover the scope, and each maps to a different task. SymbolicRegressor is for regression, which is the reason the library exists. SymbolicClassifier is for binary classification, so the evolutionary search can be pointed at a classification problem rather than a numeric fit. SymbolicTransformer is for automated feature engineering, where the evolved output becomes input to something else instead of being the answer. The caveat is attached to the transformer in the project's own text: it is designed for regression problems and is expected to work for binary classification as well, which is a statement of intent rather than of measured coverage. Anyone using it on a classification target is going past what the documentation commits to, and the sensible thing is to treat the transformer's output as a new feature set and measure it with the estimator you already trust.
The compatibility claim is the fit, predict, pipeline, grid search surface
The compatibility with scikit-learn is what the documentation leans on hardest. The package keeps the familiar fit and predict API, and it works with the existing pipeline and grid search modules, so an evolved regressor can sit in the same cross validation loop as everything else in a scikit-learn workflow. The text is candid that it tries to squeeze a lot of functionality into a scikit-learn style API and that there are many parameters to tweak, sending readers to the documentation to work out which ones matter for a given problem. That combination, a large parameter surface behind a familiar interface, is the trade being offered: convenience in exchange for a configuration problem that documentation, rather than defaults, has to solve. One prerequisite is stated separately: the package is built on scikit-learn and needs a fairly recent copy, with a bug report link if installation or running goes wrong.
The metadata calls the project Alpha after a four year gap
Version history and self description do not sit comfortably together here. The releases list shows 0.4.2 published on 2022-05-03 and 0.4.3 on 2026-01-07, so roughly three years and eight months separate the two, and the branch's last recorded push is 2026-08-14, seven months after the newest release. Yet the packaging metadata declares Development Status :: 3 - Alpha, and nothing in the project retracts that. An alpha label on a package with 1891 stars, 324 forks and seventeen open issues says something specific: the interface is expected to keep moving. That reading is consistent with a project whose compatibility target is scikit-learn, where a dependency floor as high as 1.8.0 forces a reinstall whenever the ecosystem moves. If you are evaluating this for production, the classifier in the metadata is the most reliable signal about the maintainers' own view.
The Python requirement has no ceiling and the classifiers stop at 3.14
The interpreter support is declared in a way that leaves room to run. `requires-python` is `>=3.11` with no upper bound at all, so a future interpreter is admitted by the packaging metadata, while the classifier list enumerates 3.11, 3.12, 3.13 and 3.14 and stops there. Those two statements disagree about how far the tested surface goes, and the practical effect is that an installation on an interpreter nobody has tried will succeed and then surprise you. The dependencies are short and have hard floors: scikit-learn at 1.8.0 or newer and joblib at 1.3.0 or newer. That scikit-learn floor is what the phrase about needing a fairly recent copy means in practice, and it is high enough to rule out an environment frozen on an older release. The build itself asks for hatchling at 1.26 or newer, and the distribution declares Windows, Unix and MacOS as supported operating systems.
The version number is read out of the package source at build time
The packaging metadata does not contain a version. The project block lists the version as dynamic, and a hatch configuration line underneath points at a file inside the package, `gplearn/__init__.py`, as the source of truth. So the version that ends up on the index is whatever the package's own init file says at the moment the wheel is built, not a field a maintainer edits in one place. That is a defensible choice for a single-version package, and it has a visible edge: any consumer reading the manifest rather than the installed distribution sees a gap where the version should be. The release titles show the other half of the story. The 0.4.2 release carries a name, while the 0.4.3 release has no title beyond its own version string, so the newest release in the history is also the one with the least explanation attached.
A reStructuredText readme, six badges, and no test directory at the top level
The documentation is old school in a way that is worth noting, since it affects how the project is read. The readme is README.rst, written in reStructuredText, and every badge is an image directive rather than anything a renderer infers: PyPI version, licence, documentation status, test status, a Coveralls coverage badge and a Codacy code health badge, each with a target URL. The tree carries a .coveragerc and a .github directory, which is what a coverage and workflow setup needs, but there is no tests directory among the top level entries, so the test suite the badges report on lives somewhere inside the package rather than beside it. Alongside them sit .readthedocs.yaml for the documentation build, a doc directory that holds the project logo referenced by the readme, and the two community files a project like this normally has, CODE_OF_CONDUCT.md and CONTRIBUTING.md. One inconsistency to note: the repository record lists the documentation homepage over plain http, while the manifest links the same site over https with an en/stable path.
Editorial conclusion
gplearn fits a tabular problem where you want a readable formula rather than a model you cannot inspect, and where you want to try it the same way you try every other estimator, inside a pipeline and a grid search over its parameters. It does not fit a task that needs general genetic programming, since that scope was refused on purpose, and it does not fit an environment pinned to an older scikit-learn, because the dependency floor is 1.8. Before you build on it, check four things. That Alpha classifier in the metadata, which is the project's own assessment of its readiness and worth taking at face value. That your Python version is one the package has actually been run against, since the requirement is open ended at the top while the classifiers stop at 3.14. Which scikit-learn you install, since a recent copy is required and the floor is high. And what the found expression costs you to evaluate, because an evolved program is a program, and the library hands you one without telling you how long it takes to run.
Frequently asked questions
What is gplearn used for?
It is a Python package for genetic programming, deliberately constrained to symbolic regression rather than general genetic programming. Symbolic regression looks for a mathematical expression that describes a relationship between known inputs and a target, which it does by evolving a population of random formulas generation by generation.
Which estimators does gplearn provide?
SymbolicRegressor for regression, SymbolicClassifier for binary classification, and SymbolicTransformer for automated feature engineering. The transformer is designed for regression problems and is expected to work for binary classification as well.
Can gplearn estimators be used inside a scikit-learn pipeline?
Yes. The package keeps the familiar scikit-learn fit and predict API and is built to work with the existing pipeline and grid search modules. It also carries many parameters to tweak, so the documentation is the place to find which ones matter for a given problem.
What does gplearn require to install?
Python 3.11 or newer with no upper bound, scikit-learn 1.8.0 or newer, and joblib 1.3.0 or newer. The packaging metadata declares the project at Development Status :: 3 - Alpha, and its version is read from the package init file at build time rather than from the manifest.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trevorstephens-gplearn)Star history chart for your README
[](https://hysenlabs.com/projects/trevorstephens-gplearn)Was this useful?