wilsonrljr/sysidentpy: the multi-step forecast falls back to the CPU
A Python Package For System Identification Using NARMAX Models
At a glance
- What is it?
- A NumPy-centred Python library for identifying NARMAX models, with seven named structure-selection algorithms, up to eight basis functions, more than fifteen parameter estimators and a PyTorch path for neural NARX. It is adding experimental array-API dispatch so the numerics can run on other backends, and the disclosure about what that does not cover is the most useful sentence in the documentation.
- Who is it for?
- This suits a control or signals person who wants a maintained open alternative to a commercial identification toolbox and is prepared to read the algorithm choices rather than expect a black box. The thing to check before you rely on the array-API work is the fallback: single-step prediction is genuinely backend-native, multi-step is not, so an experiment that looks accelerated may not be.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 63 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
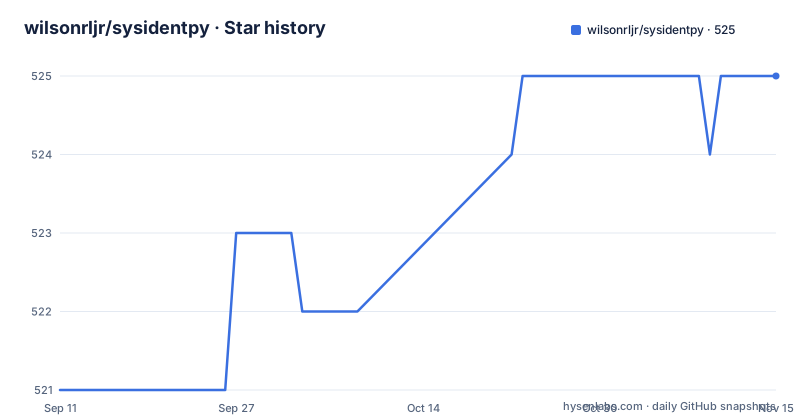
- wilsonrljr/sysidentpy525 ★ · +4
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| wilsonrljr/sysidentpy | 521 | 525 |
4 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Multi-step prediction quietly runs through a CPU fallback
The library is adding experimental, opt-in array-API dispatch, following the approach SciPy and scikit-learn take, enabled through a configuration call or a context manager rather than an environment variable. The disclosure in the middle of that section is the one to read carefully. On backends other than NumPy, single-step prediction stays native to the backend you chose. Sequential prediction, which is the case when you leave the horizon unset or ask for more than one step ahead, currently runs through a NumPy fallback on the CPU and converts the predictions back into your original namespace and device at the end. So the acceleration does not reach the path most forecasting users care about. Automated coverage is described as strongest for NumPy, PyTorch and the strict reference implementation, with GPU and array-acceleration frameworks named as experimental compatibility targets rather than supported ones.
Three of eight basis functions are covered by the new dispatch path
The feature table advertises up to eight different basis functions that you can combine linearly and nonlinearly and ensemble into custom models. The array-API section lists what is currently backend-native, and the basis functions it names are the polynomial, Fourier and bilinear ones. That is three of the eight. Everything else in that section, structure selection, simulation, metrics and utilities, is described as covered, so the gap is specific to basis functions rather than general. For anyone reading the support matrix before committing to a non-NumPy backend, that ratio is the number that matters: the parts of the pipeline you would reach for first on a linear-in-parameters model are covered, and the feature that differentiates this library from a plain linear fit is partly not. The exact matrix is deferred to a separate guide page.
The stated dependency floors cannot all be satisfied at once
The requirements are listed with lower bounds and no upper bounds, and one of them no longer makes sense. Python is given as 3.10 or later. The deep learning library, used for the neural NARX path, is given as 1.7.1 or later, a release that predates Python 3.10 support entirely. So the stated floor for that dependency cannot be installed on any interpreter the package claims to support, which means the floor is decorative and the real constraint is whatever the newest compatible version is. The same pattern applies to a numerical library floored at 1.8.0. A plotting library is listed among the core requirements rather than as an optional extra, which pulls a graphics stack into installations that only want to fit models, and the documentation separately notes that some examples need a dataframe library that is not in the list at all.
The stated target is a commercial toolbox
The clearest positioning statement in the file is in the section asking why the project exists. It states the goal twice: to be a free open-source package for designing these models, and to be a free open-source alternative to what the documentation calls the most used tool for building them, which it identifies as a commercial identification toolbox for MATLAB. Naming a proprietary product as the thing being replaced is unusual and clarifying, because it tells you the target user precisely: someone who knows the incumbent's workflow and wants the same modelling approach without the licence. The maintenance statement is one line, naming a single maintainer and asking for contributors. There is a peer-reviewed publication badge and an archive record, both of which are unusual for a package at version zero point nine and suggest the project has been taken seriously for longer than the version number suggests.
Five duplicate badges and one duplicated classifier
The badge row at the top of the page has repetition that suggests it was assembled by pasting rather than by editing. A link to the issue tracker appears twice in a row, and a link to the package index appears three times in a row. Functionally harmless, but it is the first thing a visitor sees and it reads as neglect rather than as an accident someone would make once. The same pattern appears in the packaging metadata, where one intended-audience classifier is listed at the top of the list and then again further down, inside a second block that otherwise holds topics and an operating-system line. Ten classifiers in total, including four separate audience declarations and five per-minor-version Python entries, which is a lot of metadata to maintain for a package where the audience is one group of scientists.
A production-stable label on a zero-point-nine release
Three signals about maturity do not line up. The release tags are at zero point nine, zero point eight and zero point seven, which by conventional numbering means the interface is not promised to be stable. The packaging metadata nonetheless declares a development status of production or stable, the highest of the five levels. And the most technically substantive section of the documentation describes itself as experimental, opt-in, partial and subject to a fallback. None of these is dishonest in isolation. A package can be stable in its classical algorithms while its newest dispatch layer is experimental, which is probably exactly the case here. But a user scanning metadata will read the classifier and skip the caveats, and the interpreter range adds a fourth signal: the manifest bounds it below 3.16 while the per-version classifiers stop at 3.14, leaving one allowed version unclassified.
The most prominent algorithm has no dedicated example notebook
The feature table names seven structure-selection algorithms, with the orthogonal floating search family appearing under three aliases. The examples directory tells you which of them are actually taught. Three get their own overview notebooks, covering a least-squares variant, a meta variant and an entropic-regression variant, all three framed on the same electromechanical system, plus a Fourier-transform overview and a general basis-function overview. The algorithm that leads the list in the documentation has no notebook of its own, and neither do two of the others or the floating search family. Given that the package's pitch is that you can use these selection methods, and the examples directory is where a newcomer decides where to start, that is an uneven distribution of attention. One filename in the same directory is also misspelled, with a single l in a word for electric.
Version comes from git tags, and the benchmark list stops mid-sentence
The build configuration derives the version from the repository's own tags rather than storing it, which is why the manifest and the release list cannot drift apart and why a build from an untagged checkout will not be the released version. That is the right choice, and it also means the tags are load-bearing infrastructure rather than labels. Alongside it sit a peer-reviewed publication badge with a digital object identifier, an archive metadata file, a paper directory, and an authors file maintained outside git history. The documentation footprint is unusually large for a library: a static site generator configuration, a companion book hosted next to the docs, a security policy and a code of conduct. One section is cut off though. The passage about benchmarking against other time-series tools names a forecasting library, a neural forecasting library and a classical model family, then stops at a single letter.
Editorial conclusion
This suits a control or signals person who wants a maintained open alternative to a commercial identification toolbox and is prepared to read the algorithm choices rather than expect a black box. The thing to check before you rely on the array-API work is the fallback: single-step prediction is genuinely backend-native, multi-step is not, so an experiment that looks accelerated may not be. Also confirm your interpreter against the manifest rather than the readme, since the two state different ranges.
Frequently asked questions
What models can sysidentpy build?
NARMAX variants, including the neural and non-neural autoregressive and moving-average forms, the non-linear-in-parameters form, and the classical autoregressive and moving-average families. The library offers seven named structure-selection algorithms with three aliases for one of them, up to eight basis functions that can be ensembled, and more than fifteen parameter estimation methods, including a multiobjective variant that minimises several objective functions at once.
Does sysidentpy support GPUs or non-NumPy array backends?
Experimentally and opt-in, through an array-API dispatch setting enabled with a configuration call or context manager. Automated coverage is described as strongest for NumPy, PyTorch and a strict reference implementation, with GPU and array-acceleration frameworks named as experimental. On non-NumPy backends single-step prediction stays native, but sequential prediction runs through a CPU fallback and converts results back afterwards.
How do I install sysidentpy and what does it need?
`pip install sysidentpy`. The documentation lists Python 3.10 or later, a minimum NumPy release, a minimum Matplotlib release for plotting, a minimum PyTorch release for the neural path, and a minimum SciPy release, with compatibility stated for Linux, Windows and macOS. Note that the deep learning floor predates Python 3.10 support, so that particular bound cannot be satisfied as written, and some examples need an additional dataframe library.
What is sysidentpy an alternative to?
The documentation states the goal directly: to be a free open-source alternative to what it calls the most used tool for building these models, which is the commercial System Identification Toolbox for MATLAB. It also states the goal of being a free open-source package for the community to design such models for system identification and time-series forecasting.
Can I reproduce published results with sysidentpy?
There is a dedicated simulation class described as making it easy to reproduce results from papers, including testing published models with different parameter estimation methods and comparing performance. The documentation also points to examples comparing against named forecasting and classical time-series tools, though that passage is cut off partway through in the visible text.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wilsonrljr-sysidentpy)Star history chart for your README
[](https://hysenlabs.com/projects/wilsonrljr-sysidentpy)Was this useful?