java-tron's default branch is develop, and its own build command checks out master
Java implementation of the Tron whitepaper
At a glance
- What is it?
- java-tron is the Java implementation of the TRON protocol, released under the LGPL with tagged builds that carry a codename and a philosopher's name. Two facts in its own documentation sit awkwardly against each other. The default branch is develop while the documented build sequence checks out master, and the JDK you need depends on your CPU architecture, with version 8 on x86 and 17 on ARM and the two described as not interchangeable.
- Who is it for?
- java-tron is a full node implementation rather than a library, so the questions it answers are operational: which JDK, which network configuration, and how much disk. The network parameters are the part to read first, because they differ in a way that matters for testing, since the Nile testnet's codebase is described as running ahead of mainnet while Shasta is deliberately kept in sync with it.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
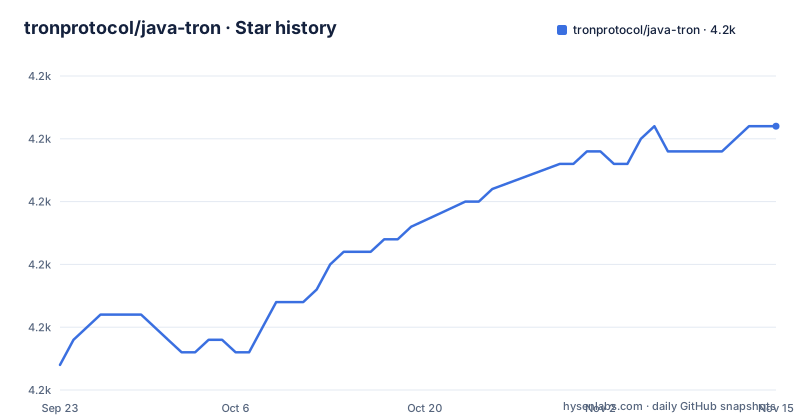
- tronprotocol/java-tron4,181 ★ · +19
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| tronprotocol/java-tron | 4.2k | 4.2k |
19 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default branch is develop; the build command checks out master
The repository's default branch is `develop`. The build instructions in the same readme say to clone the repository, change into the directory, and then check out the master branch before compiling:
git clone https://github.com/tronprotocol/java-tron.git
cd java-tron
git checkout -t origin/master
./gradlew clean build -x test
Those two statements are not compatible. A clone gives you the default branch, and the documented sequence immediately switches to another one. Which is correct depends on what you are building: master is presumably the branch that carries the releases, and develop is where ongoing work lands. Nothing in the visible documentation says so.
For anyone building a node this is not a cosmetic detail. The difference between the two branches is the difference between the code a tagged release was cut from and the code that has not been released yet, and the readme does not point at a release note that would tell you which one a given tag contains.
It is also worth noticing what is missing from that command. There is no step that fetches a tag or pins a commit, so a build following the readme exactly produces whatever master happened to be on that day.
JDK 8 on x86 and JDK 17 on ARM, and the two are not interchangeable
The build requirements are stated with unusual precision because the JDK version is tied to the CPU architecture, and the readme says outright that the two versions are not interchangeable. The table gives JDK 8 for x86_64 and amd64, and JDK 17 for ARM64 and aarch64. A note adds that ARM64 support is available starting from a named release.
That is an unusual constraint for a Java project, and it explains other things in the repository. There are two quick start scripts rather than one, with the x86 script described as targeting JDK 8 and the simple script as a template for ARM64 with JDK 17, its usage notes inside the file rather than in the documentation.
The platform requirement is narrower than the JDK one. The supported operating systems are Linux and macOS, and Windows is explicitly not supported for building, which sits oddly next to a repository that ships a Windows Gradle wrapper script in its root. The wrapper being present costs nothing; it is what you would expect from a project built by people who develop on several machines.
The hardware floor for compiling is modest next to what running a node needs: four CPU cores, 16 GB of memory and 10 GB of free disk.
The build skips its own tests unless you ask for them
The compile command ends with a flag that excludes test execution, and the readme explains the parameter in a bullet underneath. Skipping tests on a release build is a reasonable default for speed. Skipping them in the one command the documentation gives you is worth noticing.
That command is also the only build instruction in the file. There is no separate command for running the test suite, no note about which tests need a network, and no mention of an integration environment. The troubleshooting advice for a failed build points at a documentation page rather than at anything local.
Dependencies are handled the same way, with two routes and no detail on either. One is a shell script in the repository root that you make executable and run; the other is a link to a step-by-step guide on the project's documentation site. Nothing in the readme says what the script installs, so if you want a build you can reproduce later, the manual route is the one that leaves a record.
The rest of the build tooling is visible in the tree: a Gradle wrapper, build and settings scripts, a properties file, a configuration for an annotation-processing library, a directory for a static analysis tool, and configuration for two separate hosted analysis services.
Two runnable artifacts and two start scripts
The executables section is a short table and it draws a line between the node and its maintenance tooling.
The main artifact is the full node jar, generated into the build output directory after a successful build, which runs as a full node by default and takes a help flag for its command line options. The second is a toolkit jar, also generated in the build output, described as a node management utility covering database partitioning, pruning, copying and conversion, plus a shadow-fork tool.
The shadow-fork entry is the one that catches the eye, because it is not explained anywhere in the visible text. A fork tool on a consensus chain implies creating a divergent copy of chain state for testing purposes, which is a meaningful capability to have in a maintenance binary, and it is documented here by name only.
The two shell scripts at the root are thin wrappers around building and running the node jar, one per architecture, and each points somewhere different for its instructions. That asymmetry is small but real: the x86 script's notes live in a separate document in the repository, while the ARM script's notes are inside the file.
Launching the node itself is one command with no arguments, using the built jar, and the readme separately warns production deployments to consult a tuning guide for the JVM parameters.
Disk is the binding constraint, and the lite node saves terabytes
The mainnet hardware table is the most useful thing in the readme for anyone sizing a machine, and its shape is unusual: the columns are cores, memory, storage and required network capacity, and storage is where the numbers diverge wildly.
A minimum full node is eight cores, 16 GB of memory and 200 GB of storage, and that storage figure is for a lite node. A stable configuration keeps eight cores and 32 GB, and here the storage column splits into two options: 200 GB for the lite variant or 3.5 terabytes for the full one. The recommended configuration asks for sixteen cores or more, 32 GB or more and four terabytes. A super representative asks for thirty-two cores or more, 64 GB or more and the same four terabytes.
So the gap between the cheapest and the recommended setup is roughly twenty times the storage and a factor of four in memory, while the network requirement moves from five megabits per second to fifty.
A note under the table relaxes all of it for test networks, on the grounds that transaction volume is significantly lower there. That is the configuration most people experimenting with a node will actually run, and it is the one the readme spends least space on.
Network choice is a configuration file, and one of them lives elsewhere
Four network types are described, and the differences between them are the part that affects testing.
The main network is the public chain where real value moves. The Nile test network is described as forward-looking, where new features and governance proposals launch first, and the readme states plainly that its codebase is therefore usually ahead of the mainnet. Shasta is the opposite: it closely mirrors the mainnet's features and governance proposals, with network parameters and software versions kept in sync, and exists to be a realistic environment for final testing. Private networks are the fourth option, set up by private entities for testing, development or specific cases.
Selection happens by pointing the node at a configuration file at startup, and three of the four are named. The built-in template lives in the common module's resources. The mainnet configuration lives in the framework module's resources. The Nile configuration is not in this repository at all; it is linked in a separate testnet repository.
So a reader working through the list will find no path to Shasta's configuration, and will find that the testnet whose code is ahead of production keeps its parameters in another repository entirely. That is a reasonable arrangement for keeping test parameters out of the main codebase, but it means node operators depend on more than one repository to start.
Releases carry a codename and a philosopher's name
The tags are worth reading because they tell you how this project versions itself. The three most recent releases are named with a codename, a version, and then the name of a philosopher in brackets: 4.8.2.1 is Heraclitus, 4.8.2.2 is Parmenides, and 4.8.2.3 is Anaxagoras.
That is a four-part version number with a name attached, and the names are in chronological order of Greek philosophy rather than any order I can infer from the numbers alone. For an operator pinning a node build, it means the tag is readable, which is a genuine benefit, and it also means the tag is not a bare version you can compare lexically.
The patch cadence is steady. Three patch releases across July, September and late September 2026, with the branch pushed in early October, so the default branch is moving at the same rate as the releases.
One last detail connects the release naming to the build instructions. The note about ARM64 support names a specific release as the starting point, which is the only place in the readme where a release codename is used as a compatibility boundary rather than as a name.
Editorial conclusion
java-tron is a full node implementation rather than a library, so the questions it answers are operational: which JDK, which network configuration, and how much disk. The network parameters are the part to read first, because they differ in a way that matters for testing, since the Nile testnet's codebase is described as running ahead of mainnet while Shasta is deliberately kept in sync with it. Two things to confirm before you commit hardware. The build sequence in the readme checks out a different branch from the repository's default, so decide which one you are building deliberately rather than by following the commands. And the disk figures are the binding constraint, not the CPU or memory, since the gap between a lite node and a full node is measured in terabytes.
Frequently asked questions
Is TRON better than Ethereum?
The repository does not compare the two. What it states about its own chain is a throughput figure of 2000+ transactions per second, delegated proof of stake consensus, and a virtual machine described as compatible with the Ethereum virtual machine. Everything else in the readme concerns building and running a node rather than judging the protocol.
Is TRX coin a good buy or sell?
That question cannot be answered from this repository, which contains no price, market, or investment information of any kind. It is a node implementation, and its documentation covers build requirements, hardware sizing, network configuration and the maintenance toolkit.
Why is TRON not on Coinbase?
The repository does not address exchange listings. It describes the protocol, how to compile the node, the hardware needed for the mainnet, the four network types, and the configuration files that select between them.
How do I build java-tron from source?
You need four CPU cores, 16 GB of memory and 10 GB of disk, on Linux or macOS, since Windows is not supported. Install dependencies either with the shell script in the repository root or by following the manual guide, then clone the repository, check out the master branch, and run the Gradle build with the flag that skips test execution.
Which JDK does java-tron need?
The version depends on your CPU architecture and the two are described as not interchangeable: JDK 8 for x86_64 or amd64, and JDK 17 for ARM64 or aarch64. ARM64 support is available starting from a named release, and the repository ships two quick start scripts, one per architecture.
What are the TRON network types and how do I select one?
Four are described: the main network, the Nile test network whose codebase is usually ahead of mainnet, Shasta which mirrors mainnet and is kept in sync with it, and private networks. Selection is done by specifying a configuration file at startup, with the built-in template and the mainnet configuration in this repository and the Nile configuration hosted in a separate testnet repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tronprotocol-java-tron)Star history chart for your README
[](https://hysenlabs.com/projects/tronprotocol-java-tron)Was this useful?