u14app/deep-research: a self-hosted Next.js research app where you bring the models and the search engine
Use any LLMs (Large Language Models) for Deep Research. Support SSE API and MCP server.
At a glance
- What is it?
- Deep Research is an MIT-licensed Next.js app that drives a Thinking model and a Task model plus a search provider to produce research reports, and exposes an SSE API and an MCP server. It runs on your own Vercel, Cloudflare or Docker deployment, so every key and every limit is yours.
- Who is it for?
- Deep Research suits developers who want a deep-research workflow on infrastructure they control, with the freedom to swap LLM and search providers. It does not give you a hosted product with its own models, and its privacy claim covers browser storage, not the model provider your key points at.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 149 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
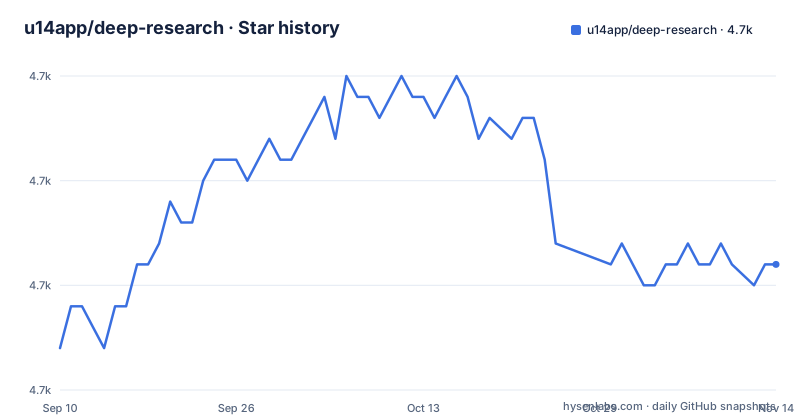
Star history
- u14app/deep-research4,686 ★ · +4
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| u14app/deep-research | 4.7k | 4.7k |
4 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Thinking model and a Task model split the work
The app does not run a single model end to end. It uses a Thinking model and a Task model, and the project says this balances depth and speed. Research models can be switched, and a project can be refined or adjusted at any stage, with re-research starting from that stage instead of from scratch. Finished output opens in an artifact editor with two modes, WYSIWYM and Markdown, where you can adjust reading level and article length or translate the full text. A one-click knowledge graph is generated from the report.
The practical consequence is that you pick two models and pay for both through whichever provider you configure. The project claims reports in about two minutes, but that figure is the README's own and depends on the models and search service you choose. Treat it as a ceiling to verify, not a promise.
Web search is a separate service you attach
Many LLMs cannot search the web, so the project bolts search on. The supported engines are Searxng, Tavily, Firecrawl, fastCRW, Exa, Bocha and Brave, and the stated purpose is to let models that lack native search use web search more conveniently. Uploaded files add a local knowledge base: text, Office and PDF resources can be processed into it.
The model providers come from the AI SDK packages in package.json: Anthropic, Azure, DeepSeek, Google, Google Vertex, Mistral, OpenAI, an OpenAI-compatible adapter, xAI and OpenRouter. The feature list also names Gemini, Atlas Cloud, Grok and Ollama. So a working install is three decisions: a model provider, a search provider and where to host. Each is a separate account or service, and a research run fails or degrades if either of the first two is misconfigured. The multi-key payload option is meant to improve API response efficiency by spreading across several keys.
Local storage is the privacy claim, but a server may sit in the path
The README states that all data is processed and stored locally, and that data is stored in your browser. Research history is preserved there so you can review earlier results and research again. The app is also a PWA, so it can be used like installed software.
The same project offers both local and server-side API calling, and the SSE API and MCP server turn a deployment into a service other tools can call. That is where the claim has limits. When requests go through a deployment on Vercel, Cloudflare or your own Docker host, that host is part of the path, and your prompts still go to whichever LLM and search providers you configured. The Docker setup can protect the instance with an ACCESS_PASSWORD environment variable. Browser-stored history also means a different browser or a cleared profile will not show your earlier research.
Free Gemini deployment still needs your own key and a host
The recommended route is the free Gemini path: get a Gemini API key, then deploy with the one-click Vercel button or to Cloudflare, then start using it. Cloudflare is not one click. The project says you must follow its separate How to deploy to Cloudflare Pages document. For any other LLM you deploy to Vercel or Cloudflare, set the LLM API key, optionally set the LLM API base URL, and start.
For local development, Node.js 18.18.0 or later is recommended, with pnpm, npm or yarn. The steps are:
git clone https://github.com/u14app/deep-research.git
cd deep-researchpnpm install # or npm install or yarn installEnvironment variables come from the env.tpl template:
# For Development
cp env.tpl .env.local
# For Production
cp env.tpl .envpnpm dev # or npm run dev or yarn devThen open http://localhost:3000. The dev script runs next dev with Turbopack. The word free refers to the Gemini route, not to hosting, which you still arrange yourself.
The custom model list only works in proxy mode
You can restrict or extend the models shown in the interface with an environment variable named NEXT_PUBLIC_MODEL_LIST, set in the .env file or on your host's environment variables page. The project is explicit that this works only in proxy mode, so a setup that calls providers directly from the browser will ignore it.
The syntax is simple. Separate models with a comma. To disable a model, prefix its name with a minus sign, as in -existing-model-name. To allow only specific models, start with -all and then add each with a plus sign, as in -all,+new-model-name.
The consequence for a shared deployment is that this is the lever for keeping users off expensive models, but only if you run in proxy mode. Because the variable begins with NEXT_PUBLIC, it is a build-time public setting in Next.js, so treat it as a menu preference, not as a security control. Pair it with ACCESS_PASSWORD if the instance is reachable by others.
The Docker image trails the repository by a day or two
Docker needs version 20 or above, otherwise it reports that the image cannot be found. The project also warns that the Docker version usually lags the latest by one to two days, so the update-exists prompt keeps appearing after deployment, which it calls normal. The published image runs like this:
docker pull xiangfa/deep-research:latest
docker run -d --name deep-research -p 3333:3000 xiangfa/deep-research
To pass environment variables:
docker run -d --name deep-research \
   -p 3333:3000 \
   -e ACCESS_PASSWORD=your-password \
   -e GOOGLE_GENERATIVE_AI_API_KEY=AIzaSy... \
   xiangfa/deep-research
Building yourself uses the Dockerfile, a multi-stage build on node:18-alpine that runs the standalone build, exposes port 3000 and starts node server.js. docker-compose.yml builds that image, reads .env and maps 3333 to 3000. A commented NEXT_TELEMETRY_DISABLED line in the Dockerfile shows how to switch off Next.js anonymous telemetry, which is on unless you uncomment it.
SSE API and MCP arrived in v0.9.x, and the last push was in June 2026
The v0.9.20 release is titled Support API and MCP, and the roadmap lists SSE API and MCP server as done. That is what turns the app from a browser tool into a deep-research service other AI services can call. The build scripts also include build:export, which sets NEXT_PUBLIC_BUILD_MODE to export, and build:standalone, which is what Docker uses.
The repository is not archived. The last push was on 2026-06-18. Tagged releases are v0.9.20 on 2025-05-20, v0.10.0 on 2025-09-11 and v0.11.0 on 2026-02-10, and package.json already reads 0.11.1, so the code is a patch ahead of the newest tag. The license is MIT. The interface is offered in English, Simplified Chinese and Spanish. With a 0.x version number and a package marked private, expect interfaces and environment variables to keep shifting, and pin a tag if you build on the API.
Editorial conclusion
Deep Research suits developers who want a deep-research workflow on infrastructure they control, with the freedom to swap LLM and search providers. It does not give you a hosted product with its own models, and its privacy claim covers browser storage, not the model provider your key points at. Decide which provider sees your prompts before you deploy.
Frequently asked questions
What is deep research?
In this project it means generating an in-depth research report with a Thinking model and a Task model plus web search, then editing the report, translating it or turning it into a knowledge graph.
Is deep research free?
The u14app/deep-research code is MIT licensed, and the README offers a free Gemini route. You still deploy it yourself and supply the API key for the model you use.
how to use deep research
Deploy u14app/deep-research to Vercel, Cloudflare or Docker, set an LLM API key and optionally a base URL, then open the app. Locally, run pnpm install and pnpm dev and visit http://localhost:3000.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/u14app-deep-research)Star history chart for your README
[](https://hysenlabs.com/projects/u14app-deep-research)Was this useful?