unitycatalog: a sandbox project that calls itself the only one, with a nightly extension and two frontends
Open, Multi-modal Catalog for Data & AI
At a glance
- What is it?
- Unity Catalog is an open catalog for data and AI assets, comparable to the metastore and REST catalog interfaces a commercial product exposes, and it is hosted as a sandbox project under a Linux Foundation arm. Its own readme says the APIs are evolving and should not be assumed stable. The build and deployment files are where the project's real shape shows: four ways to deploy, a corporate proxy hook, and two frontend directories of which one is built.
- Who is it for?
- Adopt it if you need an open metastore-shaped interface for several table formats and AI assets, and read it as a sandbox rather than a product: the project says so itself, and it says the APIs are not stable. Two things to weigh before depending on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
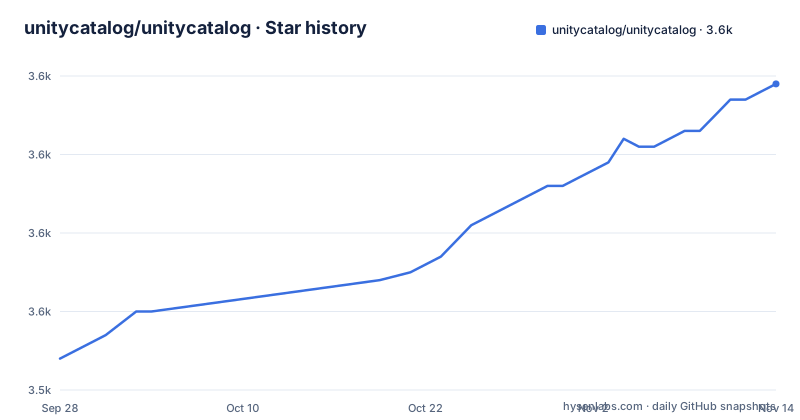
- unitycatalog/unitycatalog3,579 ★ · +35
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| unitycatalog/unitycatalog | 3.5k | 3.6k |
35 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A sandbox project that calls itself the only one
Two sentences in the opening of this readme sit in deliberate tension.
The first claims to be the only universal catalog for data and AI in the industry. The second, in a bullet further down, says the project is currently a sandbox project with the foundation's AI and Data arm, part of the Linux Foundation.
A sandbox is a specific status in that foundation's vocabulary: an incubation project with no stability commitment, which is the same message the compatibility section delivers in a third place, stating that the APIs are evolving and should not be assumed to be stable.
So the scope claim is maximal and the stability claim is minimal, and both are in the same document. That combination is common in foundation-hosted infrastructure and it is worth reading the second sentence rather than the first.
The rest of the scope is concrete and unremarkable in the best way. Several table formats through a shared metadata specification, plus Parquet, JSON, and CSV. Any engine that can speak the open interfaces. Assets including tables, files, functions, and models, all under one interface.
The quickstart's prerequisite sentence is missing a word
The quickstart is the most careful document in the repository, and one line in it is broken.
The prerequisites list has three items: clone the repository, ensure a certain environment variable points to a version 17 JDK, and compile the project with a build script subcommand. The middle item is where the sentence goes wrong, because the clause about the terminal being configured is spliced into the middle of the clause about the variable.
What survives the mangling is the actual requirement, and it is a real one: a version 17 JDK selected through that environment variable, plus a package step before the server will start. The compiling and testing section repeats the same instruction in a cleaner sentence, which suggests the quickstart text is the copy that was edited in place.
The rest of the quickstart is unusually good. It runs the server in one terminal and explores it in another, it names the flag that untruncates the output because the default view is cut short by nested data, and it says plainly that a table is a Delta table before demonstrating reading a snippet of its contents, crediting the kernel library that does the reading.
The engine integration installs the catalog extension from a nightly channel
The fourth route in the quickstart is a third-party engine reading the catalog, and it is the one to read carefully.
The instructions install that engine itself at a specific major version, then install two extensions inside it, the first of them from a nightly channel:
sql
install uc_catalog from core_nightly;
One of them is the catalog extension, and the line it comes from is a nightly channel rather than a released one. The other is the Delta extension, installed normally.
So the documented path for a third-party engine to read this catalog depends on a moving build of a dependency, inside a project whose own interfaces the readme says are not stable. Two moving parts, one of them explicitly.
The rest of that section is careful about its own mechanics. It warns that previously installed extensions may need updating and a restart before the later steps work. It shows the connection being declared as a secret rather than a configuration file, and the secret is the shape a storage secret normally takes: a type, a token, an endpoint, and a region. Then the catalog is attached and two queries print its contents.
The connection example ships a token spelled not-used
The example connection block in the quickstart is four lines and three of them are placeholders, which is exactly right for a tutorial and worth quoting as the shape you will actually need to fill in.
The type names the catalog, the token is the literal string saying it is not used, the endpoint points at a local address, and the region is a fixed string that has nothing to do with where the server is.
That is four fields to fill in for a real deployment, one of which is empty by default and one of which is a region name that the server does not read. The readme does not say whether the region is required, so anyone connecting to something other than a local server has to discover that by trial.
Two smaller details in the same section are the kind of thing that costs a newcomer an hour. The quitting instructions offer three ways, including a control combination the readme qualifies with a note about platform support, and the table listing command uses a different capitalisation style from every other SQL block in the document.
Two frontends in the tree, and both documented routes use one
The repository root contains two frontend directories, and that is the first thing a contributor will notice.
One is referenced in three places. The container composition file builds its image with that directory as the build context. The quickstart's interface section says to change into it, install with one package manager and start with another script. And the local start command given in the same section points at the server launcher in a subdirectory.
The second frontend directory is referenced by nothing in the readme. It sits beside the first with the same naming pattern and one extra word, which is the convention this repository uses for a replacement: elsewhere in the root there is a second build configuration and a second implementation directory, and the tree also carries a separate directory for the new interface.
So the documentation describes one frontend, the composition file builds one frontend, and the tree ships two. Which one is current is not stated anywhere in the visible material.
That matters more than a duplicate directory usually would, because the interface is a supported surface rather than an internal tool: the readme tells you to start it in a third terminal after the server.
The build cache is copied into the runtime image, for a documented reason
The image build carries the longest explanatory comment in this repository, and it explains something you would otherwise fix incorrectly.
The build stage sets a dependency cache location inside the home directory, and the comment explains two traps. First, the virtual machine derives its home from the account entry and ignores the home variable, so the cache would otherwise land outside the tree the runtime stage copies. Second, and this is the part that matters, the build tool bakes absolute paths to its downloaded jars into a file in the build output, so the cache location has to resolve to the same path in both stages or the server starts with classpath entries missing.
That is why the runtime stage copies the home directory wholesale, cache included, from the build stage. The comment above the second stage calls it a small runtime image, and it is small compared to a JDK build image, but it does ship a dependency cache because correctness requires the absolute paths to hold.
The rest of the build is disciplined in a way that is easy to miss: the base and runtime images are both pinned by digest rather than by tag, the build tool runs from inside the repository rather than being installed, and only six directories are copied forward rather than the whole tree.
Four deployment paths and a corporate proxy hook in the open build
The readme describes four ways to get this running, and the build file contains a fifth thing nobody would expect to find in an open-source project.
The four are: run the launcher from a source checkout, run the container composition file, build a deployment tarball, and use the Helm chart that sits in the repository root. The composition file pulls a prebuilt image by a floating tag rather than building the server itself, so the container route and the build-image route are genuinely different amounts of work.
The fifth thing is a build argument for a corporate Maven mirror, set as an environment variable in the build stage with a comment saying to pass it at build time. It is a harmless no-op for anyone who does not set it, and it is the kind of internal affordance that ends up in a public build file and stays there.
Two more details from the composition file. Configuration is bind-mounted from a directory in the repository into the container, so a fresh checkout ships a working configuration path. And the interface service is built locally rather than pulled, with the server declared as a dependency, which means the container route builds the frontend and downloads the backend.
Editorial conclusion
Adopt it if you need an open metastore-shaped interface for several table formats and AI assets, and read it as a sandbox rather than a product: the project says so itself, and it says the APIs are not stable. Two things to weigh before depending on it. The engine integration path in the quickstart installs the catalog extension from a nightly channel, so that path can move under you without a version change on this side. And the repository contains two frontend directories while the compose file and the quickstart both use only one, so a contributor has to work out which is current.
Frequently asked questions
how to use unity catalog
Clone the repository, point your environment at a version 17 JDK, compile with the build tool, then start the server in one terminal and explore it in another with the command line interface. The interface is started in a third terminal, and a container route is offered as an alternative to running the launcher directly.
how to install unity catalog
The readme gives a source route and a container route. The source route is a clone, a version 17 JDK selected through an environment variable, and a package step with the build tool. The container route is a compose file that pulls a prebuilt server image and builds the interface locally, with configuration mounted from a directory in the repository.
Is the Unity Catalog a Databricks feature?
Not in this repository. What this project is: an open-source catalog released under the Apache 2.0 licence and hosted as a sandbox project with the Linux Foundation's AI and Data arm. Its readme also says its interfaces are compatible with the metastore API and the REST catalog API, so it is a peer implementation of shapes the commercial product also implements rather than a feature inside it.
How much does Databricks charge for Unity Catalog?
Nothing in this repository concerns pricing. The readme covers the formats and engines supported, the open specification, unified governance across tabular, unstructured, and AI assets, and a statement that the interfaces are evolving and should not be assumed to be stable.
what is unity catalog
In this repository it is a catalog for data and AI assets, covering tables, files, functions, and models behind one interface, readable through open interfaces by many compute engines, and supporting several table formats through a shared metadata specification plus Parquet, JSON, and CSV. The readme also describes it as a sandbox project and warns that its interfaces are not stable.
what is unity catalog volume
The readme does not define the term. Its command line tutorial says the interface can operate on volumes and functions as well as on catalogs, schemas, and tables, and the asset list names tables, files, functions, and models, without explaining what a volume holds.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/unitycatalog-unitycatalog)Star history chart for your README
[](https://hysenlabs.com/projects/unitycatalog-unitycatalog)Was this useful?