Mediabunny in practice: Input, Output, Conversion, and where WebCodecs does the work
Pure TypeScript media toolkit for reading, writing, and converting video and audio files, directly in the browser.
At a glance
- What is it?
- A pure TypeScript media toolkit for the browser, where the interesting decisions are the Input and Output construction, the BufferTarget in memory, the WebCodecs dependency and the separate server package for Node.
- Who is it for?
- Mediabunny fits browser projects that need to inspect, trim, transcode or mux media without shipping FFmpeg or a server, and teams willing to depend on WebCodecs support in their target browsers. It does not fit a Node backend that wants one library for everything, and it is a poor fit for codebases that need codecs WebCodecs does not expose.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
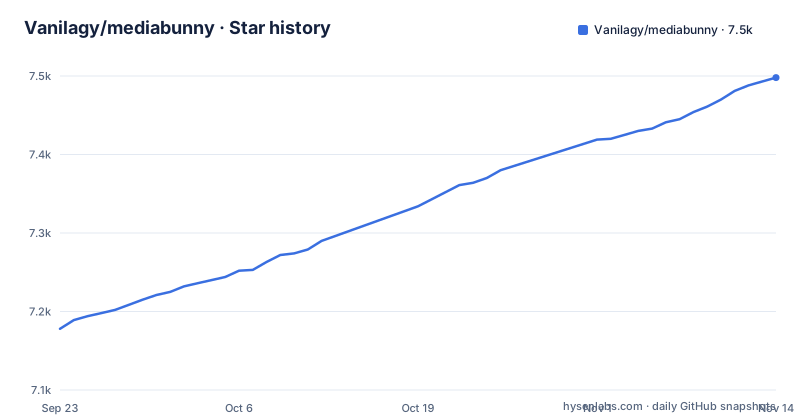
- Vanilagy/mediabunny7,498 ★ · +320
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| Vanilagy/mediabunny | 7.2k | 7.5k |
320 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two install paths: an npm package or a script tag exposing a global Mediabunny
The package manager route is the short one:
npm install mediabunnyThe alternative is to include a build directly with a script tag, which exposes a global `Mediabunny` object instead of giving you imports:
<script src="mediabunny.cjs"></script>Those builds come from the releases page rather than from the registry, which is the trade: no install step in exchange for managing the file yourself and reading it from a global. Whichever route you take, the runtime floor matters more than the install line. Any JavaScript environment that can run ECMAScript 2021 or later qualifies, the project expects modern browsers, and consuming the types requires TypeScript 5.7 or later. A codebase on an older TypeScript will therefore fail at the type level before it fails at runtime, which is worth checking against your tsconfig first.
Reading starts with an Input, a source object, and ALL_FORMATS
Every read follows the same three part shape: an `Input`, a source describing where the bytes come from, and a list of formats the input is allowed to consider. `ALL_FORMATS` accepts everything the library can parse, and `BlobSource` points at a file the user picked from disk.
import { Input, ALL_FORMATS, BlobSource } from 'mediabunny';

// Reading from disk
const input = new Input({
    source: new BlobSource(file),
    formats: ALL_FORMATS,
});

const duration = await input.computeDuration(); // in seconds
const videoTrack = await input.getPrimaryVideoTrack();
const audioTrack = await input.getPrimaryAudioTrack();

const displayWidth = await videoTrack.getDisplayWidth();
const displayHeight = await videoTrack.getDisplayHeight();
const rotation = await videoTrack.getRotation();
Note the shape of the API. There is no single metadata object to grab: you ask the input for its duration, then ask for the primary video and audio tracks, then call one accessor per property you care about, and each of those is an async call. Get the display size, not the coded size, and read the rotation separately, because a rotated video does not present its stored width as its display width.
BufferTarget keeps the finished file in memory, and the streaming claim covers the rest
Writing reverses the construction: an `Output` needs a format and a target before anything can be added to it, and the target decides where the bytes end up.
import { Output, Mp4OutputFormat, BufferTarget, CanvasSource, Quality } from 'mediabunny';

const output = new Output({
    format: new Mp4OutputFormat(),
    target: new BufferTarget(), // Writing to memory
});

// Add a video track backed by a canvas element
const videoSource = new CanvasSource(canvas, {
    codec: 'avc',
    bitrate: new Quality('high'),
});
output.addVideoTrack(videoSource);

await output.start();
// Add frames...
await output.finalize();

const buffer = output.target.buffer; // Final MP4 file
The `BufferTarget` is the quick path, and its cost is the obvious one: the finished MP4 sits in memory and is reached through `output.target.buffer` after `finalize()`. The feature list also claims streaming I/O that handles files of any size with bounded memory, so a long recording should not be built this way. The other thing to notice is ordering. Tracks are added before `start()`, frames go in between `start()` and `finalize()`, and the buffer only exists afterwards.
Conversion is two calls: Conversion.init, then execute
Converting a file means building an input and an output as before, then handing both to the conversion API:
import { Input, Output, Conversion, ALL_FORMATS, BlobSource, WebMOutputFormat, BufferTarget } from 'mediabunny';

const input = new Input({
    source: new BlobSource(file),
    formats: ALL_FORMATS,
});

const output = new Output({
    format: new WebMOutputFormat(), // Convert to WebM
    target: new BufferTarget(),
});

const conversion = await Conversion.init({ input, output });
await conversion.execute();
Here the output format decides the target container. The same API is described as covering transmuxing, transcoding, resizing, rotation, cropping, resampling and trimming, so the operations a command line tool would take flags for are method calls here. What the snippet does not show is any progress reporting or cancellation hook, so for a large file you will want to know how to observe the run before you put it behind a progress bar.
Codec work is delegated to WebCodecs, which decides where it can run
Encoding and decoding are described as built in and hardware accelerated using the WebCodecs API, covering more than 25 video, audio and subtitle codecs, with reading and writing described as microsecond accurate. That sentence is the real constraint of the project. Mediabunny implements containers and media operations itself in pure TypeScript with zero dependencies, but it delegates the codec primitives to the platform, so codec and hardware-acceleration availability depend on the browser, device and configuration. WebCodecs being present does not guarantee that a particular codec or hardware path is supported; check support on the target runtime. The claimed cross platform support follows from the same design: it works in browsers, and in Node, Bun and Deno the support comes from a separate `@mediabunny/server` package rather than from the core one.
The browser condition in package.json replaces the Node modules with false
The packaging is where the split becomes concrete. The exports map has separate browser and node conditions, with the browser branch pointing at the module build and a require fallback of `mediabunny.cjs`, while the node branch falls back to `mediabunny.node.cjs`. On top of that sits a browser field that maps the node entry point and `node:fs/promises` to false, so a bundler drops those files instead of failing on them. `sideEffects` is false, and that is what backs the claim that the library is tree-shakable down to as little as 5 kB gzipped when you import only what you use. The practical warning is that those entry points point into `dist`, so you should consume the published package rather than pointing a bundler at the `src` tree and expecting the same resolution behaviour.
A workspace repo with split Node and browser test suites
The tree is that of a monorepo: `package.json` declares workspaces of `.` and `packages/*`, with the server package living under `packages/`. Alongside sit `src/`, `test/`, `docs/`, `examples/`, `scripts/`, `dev/` and `shared/`, plus an `api-extractor.json` for the public API surface and a `CLAUDE.md`. Tests are split by runtime rather than run as one suite: `npm test` bundles first and then runs vitest, `npm run test-node` covers the `node/` directory and `npm run test-browser` covers the `browser/` directory. The examples directory mirrors the use cases the library advertises, with folders for HLS transcoding, live recording, metadata extraction, thumbnail generation, procedural generation and file compression. Docs are a VitePress site, served with `npm run docs:dev`.
MPL-2.0 and distribution obligations
The license is MPL-2.0, described as a permissive weak copyleft licence not far from MIT. You may use it commercially or not, use it in open and closed source projects, distribute projects built with it without royalties, and read and modify the source. The MPL is a file-level copyleft license. When distributing modified MPL-covered files, make their source available under the MPL. Distribution of unmodified covered code can also carry notice and source-availability requirements, depending on what and how you distribute; consult the license and Mozilla’s FAQ for the relevant case. Maintenance of the library is described as sponsor funded, with the gold and bronze sponsor lists naming companies including Remotion, Tella and Mux, and releases land quickly: v1.63.0 on 2026-10-28, v1.64.0 on 2026-10-29 and v1.65.0 on 2026-10-30, with the repository last pushed on 2026-11-02.
Editorial conclusion
Mediabunny fits browser projects that need to inspect, trim, transcode or mux media without shipping FFmpeg or a server, and teams willing to depend on WebCodecs support in their target browsers. It does not fit a Node backend that wants one library for everything, and it is a poor fit for codebases that need codecs WebCodecs does not expose. Before committing, confirm your target browsers have WebCodecs, decide whether a memory target is acceptable for your file sizes, and read the MPL-2.0 modification clause if you plan to fork.
Frequently asked questions
What are the key differences between Mediabunny and FFmpeg?
The project compares itself to FFmpeg but built for the web: pure TypeScript, zero dependencies, running in the browser on the WebCodecs API, tree-shakable down to 5 kB gzipped, with Node, Bun and Deno support coming from a separate @mediabunny/server package.
What is Mediabunny used for?
It is a JavaScript library for reading, writing and converting media such as MP4, WebM, MP3 and HLS directly in the browser, through the Input, Output and Conversion classes.
Which alternative to Mediabunny should a browser project consider?
The README compares Mediabunny to FFmpeg: you can think of it a bit like FFmpeg, but built from the ground up for the web.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vanilagy-mediabunny)Star history chart for your README
[](https://hysenlabs.com/projects/vanilagy-mediabunny)Was this useful?