Vexa: one runtime for meeting bots and coding agents, and a 503 when the transcription token is missing
Open-source meeting transcription API for Google Meet, Microsoft Teams & Zoom. Auto-join bots, real-time WebSocket transcripts, MCP server for AI agents. Self-host or use hosted SaaS.
At a glance
- What is it?
- An Apache-2.0 stack where a bot joins Google Meet, Teams, Zoom or Jitsi calls and streams speaker-attributed transcripts, and the same sandbox runtime that runs those bots also runs the agents that turn meetings into Markdown in a git repo. The hosted service covers capture only, self-hosting needs a transcription token unless you opt out, and the manifest carries more than twenty named gates.
- Who is it for?
- Fit for a team that wants meeting transcripts as files it owns and refuses to hand conversations to a vendor's cloud, and unfit for anyone who only wants the agent side without running the stack themselves, because the hosted service stops at capture and the knowledge agents are self-host only. Four things to check before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
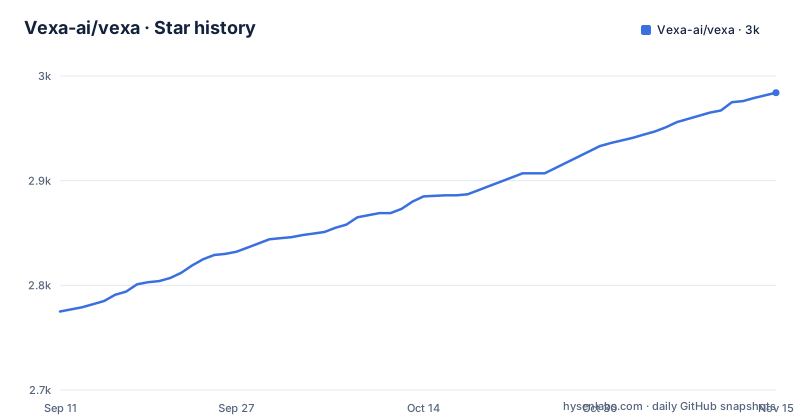
Star history
- Vexa-ai/vexa2,984 ★ · +209
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Vexa-ai/vexa | 2.8k | 3k |
209 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A bot and an agent are the same runtime.v1 workload
The architecture section makes one claim and then applies it everywhere: there is a single gateway with two domains, Meetings for capture and Agents for working the knowledge, and both run on the same runtime, the engine that spawns every bot and every agent in its own sandboxed container. A bot and an agent are described as the same runtime.v1 workload, isolated, ephemeral and reaped on idle, so the machinery already exercised by thousands of meeting bots is what runs the agents. Three properties define that runtime. Isolation is enforced by the substrate rather than by the agent: every dispatch gets its own container, egress is blocked except through brokered tools, only granted workspaces are visible in the filesystem, and agents never run in the control plane. Ephemerality means a container lives while it works, with continuity kept in a session file inside the workspace and starts in under a second. Orchestration stays pluggable behind one lifecycle, on Docker or on Kubernetes. The product framing rests on the same idea from the user's side: meetings compile into Markdown in a git repository, which the page calls portable, diffable and greppable, and the agents read and write that repository the way a developer would, committing only what a person decides. Agents are also reachable from outside the Terminal, since the page carries a connect-your-agent link alongside an MCP server for AI agents in its own description.
POST /bots answers 503 when the transcription token is missing
The default configuration fails closed, and that is the single most useful operational fact on the page. Transcription is a prerequisite: by default POST /bots requires the speech-to-text component and answers 503 when it is missing, and make all warns when the credentials block in the .env file is empty. There are two documented ways to supply it. You can use a free token from the hosted account page, or you can self-host the transcription unit, which needs a GPU and is what makes a fully air-gapped setup possible. Running without transcription is not the default but it is supported, and it has to be asked for explicitly: a capture-only bot carries transcribe_enabled set to false on the spawn request, or the deployment sets TRANSCRIBE_ENABLED to false. That distinction matters when you read the failure, because a 503 on the bot endpoint means a missing credential, not a broken meeting link.
Three ways to get it running, and they cost very different machines
The Makefile is a deploy entry point rather than a build system, and its help text is the clearest documentation of the three paths. The prerequisites are short: make, a Docker engine at version 26 or later, which make all checks for itself, and a transcription token or your own transcription unit. Linux on Ubuntu 24.04 is named as the production target, while a Mac with Docker Desktop is described as fine for a local evaluation, since everything runs in containers either way. The starting point is two commands:
git clone https://github.com/Vexa-ai/vexa.git && cd vexa
make all
make all brings up the full Docker Compose stack from the published, release-validated images, which are pulled rather than built, so the README says a modest machine is enough. make lite is the same product as a single container, lighter still. make dev builds everything from the checkout, and that is the path contributors take, with the images tagged for development so they never shadow the published line. The cost difference is stated plainly: building from this checkout wants eight vCPUs and sixteen gigabytes of memory, while the pull path does not. Two smaller targets complete the picture. make bot builds only the meeting bot from source, and make probe runs a full-journey smoke check against an install that is already running, with the surface selectable between compose, lite and helm.
make probe inspects a running install, and SURFACE picks how
The probe target is worth reading closely because of what it deliberately is not. It does not start anything: the comment describes it as a full-journey smoke probe of a running install, a spawn through stop sequence with a log sweep, and the recipe simply runs a shell script under the deploy directory for whichever surface is selected. SURFACE defaults to compose and can also be lite or helm, so the same check runs against a Kubernetes deployment even though the top-level entry point is Compose. There is also a login target that provisions an authenticated bot session, described as signing in once and persisting it, with its uploads going to userdata storage, implemented by calling into a workspace package through pnpm. The remaining target, make down, stops the Compose stack. Together these five targets are the whole operational surface a self-hoster needs.
Two local ports, a printed key and three things to try in the Terminal
A completed make all prints three lines: a Terminal UI on port 13000, an API gateway on port 18056, and an API key with the vxa_ prefix. The page calls the Terminal the fast path, because it needs no curl. From it you can paste a Meet, Zoom, Teams or Jitsi URL and send a bot as a participant; watch the transcript stream in live, where each segment is attributed to a speaker and is described as draft then confirmed; and chat with the workspace, asking an agent that has every captured meeting as context and watching it commit what you decide. Over the API the same three actions are a POST to /bots with the platform, the native meeting id taken from the join URL and a bot name, a GET on the transcripts path for that platform and meeting, and a POST to /agent/chat that streams its answer back as Server-Sent Events. The bot call is the smallest useful piece to copy:
curl -X POST "https://api.cloud.vexa.ai/bots" \
  -H "X-API-Key: $API_KEY" -H "Content-Type: application/json" \
  -d '{"platform":"google_meet","native_meeting_id":"abc-defg-hij","bot_name":"Vexa"}'
That is the hosted endpoint, with the key passed as a header rather than in the path. On a self-hosted install the same request goes to the local gateway with the local key. The event stream uses two frame types, message-delta for the text of the answer and commit for anything the agent recorded into your workspace.
Jitsi is offline-proven with live validation still pending
The platform list is four values, google_meet, teams, zoom and jitsi, and the identifier sent with each is the code from the meeting's join URL rather than a full link. Three of the four are presented as working without qualification, and the fourth is not. The summary line at the top of the page carries a parenthetical about Jitsi: join and capture are offline-proven, live validation is pending, with a link to issue 883. That distinction is carried through the feature argument as well, where the same wording appears when the bot fleet is described as the hard part of the product. The practical reading is that a Jitsi deployment should be validated against a live call before anyone depends on it, and that the issue tracker, not the documentation, is where that status will change.
More than twenty named gates guard the build
The JavaScript side of the repository is where the project's engineering discipline shows. Build, test, lint and typecheck all delegate to turbo across the workspace, and the prepare script points git at a hooks directory during install. Then there are the gates, all of them scripts behind named entries: a readme gate, a docs-version gate, an isolation gate, an exports gate, a graph gate, a schema gate, a contract-version gate, a config-contract gate, a database schema gate, a database budget gate, a merge card gate, a docs-current gate, a release value gate, a release witness gate, a dataflow gate, and gates named for the languages in the stack including python, node and licenses. Alongside them are sealing steps for contracts, schema and architecture, an architecture DSL script, and two witness scripts for releases. The names imply what is being defended: isolation of workloads, exported surface, versioned contracts, database size, and licence compliance.
Licence accounting, sealed contracts and two oddly named Markdown files
The root of the repository documents its own obligations in detail, which suits a project whose pitch is that you own what your meetings become. Alongside the Apache licence there are THIRD_PARTY_LICENSES.md, a licenses/ directory, a licence exceptions file, and an image licences file, so both code and container contents are accounted for. There is also a contributor rights file, a security policy and a security insights configuration. Four sealed JSON artefacts sit next to them, covering architecture, contracts and schema, which pair with the seal and graph gates from the manifest. Then there are the files nobody would guess: MARVIN-TEST-KIT-1005.md and OBSERVATION-BUNDLE-1005.md at the root, and assistant tooling committed alongside the human instructions in the form of CLAUDE.md, a CLA/ directory and a .claude-plugin/ directory. The Makefile header calls the project open-core, while the page describes the code as Apache-2.0. Versions are similarly unsettled: the newest tag is v0.13.1, named for an alpha minutes line, but the manifest reads 0.12.28 and the hosted service is described as running the 0.12 line. On 2026-09-07 two tags were published on the same day, with the 0.12.27 build, named for the full MCP, flows and searchable meetings, appearing after the 0.13.1 one.
Editorial conclusion
Fit for a team that wants meeting transcripts as files it owns and refuses to hand conversations to a vendor's cloud, and unfit for anyone who only wants the agent side without running the stack themselves, because the hosted service stops at capture and the knowledge agents are self-host only. Four things to check before you commit. Transcription is not optional by default: without a token the bot endpoint answers 503, so either supply one or set the capture-only flag deliberately. Jitsi is described as offline-proven with live validation still pending, so it is the platform to test first if you need it. The build from source wants eight vCPUs and sixteen gigabytes of memory, while the published-image path needs far less. And the version story is muddled, since the newest tag is v0.13.1 while the manifest reads 0.12.28 and the hosted service is described as running the 0.12 line.
Frequently asked questions
How much does Vexa cost, and is there a free tier?
New hosted accounts get $2 of free bot credit with no card required, which the page works out as about six hours of bot time at $0.30 per hour, and a pricing page is linked for more. Self-hosting the stack does not carry that per-hour cost.
Can I run Vexa without sending my meetings to someone else's cloud?
Yes. Self-hosting the full stack is the supported route, on one host with everything in containers, and the code is Apache-2.0 and described as air-gap-ready. Self-hosting the GPU transcription unit is what makes a fully air-gapped setup possible, and meetings compile into Markdown in a git repository you own.
What does Vexa need before POST /bots will work?
A transcription token. By default POST /bots requires the speech-to-text component and answers 503 when it is missing, and make all warns when the credentials block in the .env file is empty. Running capture only has to be requested, with transcribe_enabled set to false on the spawn, or TRANSCRIBE_ENABLED set to false for the deployment.
Which meeting platforms does Vexa join, and which one is less proven?
Four values are accepted for the platform field: google_meet, teams, zoom and jitsi, with the native meeting id taken from the join URL. Jitsi is the one qualified in the page, described as join and capture offline-proven with live validation pending, tracked as issue 883.
How do I read an agent's answer from the Vexa API?
POST to the agent chat endpoint and read the stream. The reply arrives as Server-Sent Events, where message-delta frames carry the text of the answer and commit frames mark anything the agent recorded into your workspace.
Does the hosted Vexa service include the agent features?
No. The hosted service runs meeting bots and transcription on the 0.12 line, while the sandboxed knowledge agents are self-host only. The page also notes that if you only want the transcription API, it is a complete standalone product and the agent lane can be ignored.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vexa-ai-vexa)Star history chart for your README
[](https://hysenlabs.com/projects/vexa-ai-vexa)Was this useful?