OpenFic tells you which of its two use cases is the wrong one for you
A cross-platform, user-friendly, AI-native, all-in-one Vibe Writing tool designed specifically for novel writing.
At a glance
- What is it?
- A local-first writing environment for long-form fiction, with a vector index for retrieval across a project measured in hundreds of thousands of words, and prompts and workflows the author expects you to edit. The front page spends as much space listing what the tool is not for as what it is for, and the Docker image bakes the frontend build into the Python runtime.
- Who is it for?
- OpenFic fits someone with an existing novel and an existing method: a maintained worldview, a cast, planted foreshadowing, and a sense of how the chapters fit. The agent's job there is retrieval and consistency checking across what you already wrote, which is what the vector index is for.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
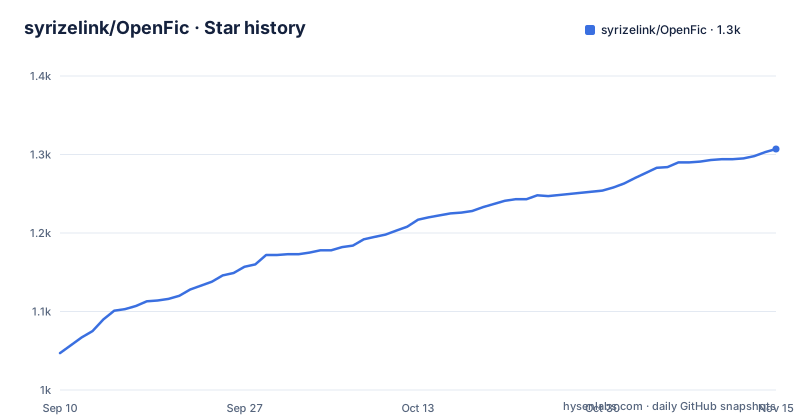
- syrizelink/OpenFic1,307 ★ · +260
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| syrizelink/OpenFic | 1k | 1.3k |
260 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The page lists five reasons it fits and three reasons it does not
The most useful paragraph on the front page is the one telling you when not to use it. It is a longer list than the compatibility list, and the three exclusions are specific rather than coy. Type one prompt and receive a whole novel automatically: the page calls that unrealistic. Needing short copy, social content, or one-off general text generation: that is not what this is for. And having no intention of maintaining a complex setting or of needing long-lived context and workflow management, in which case the machinery is overhead. The three inclusions it does name are long-form novel writing with a maintained worldview, cast and chapter information; help from the agent with consistency checking and detail completion; and having your own workflow with prompts you intend to change.
The stated order is writing tool first, agent second
A callout above the lists states the design position, and it is the clearest thing the project says about itself. The premise is that the agent takes part in novel creation deeply rather than producing soulless text in one click, and that it is first a user-friendly novel writing tool and only second an AI agent system aimed at writing. That ordering is a specification as much as a slogan, because it is what decides the trade-offs. If the editor is the product and the agent is an accessory, then the thing being optimised is the writing surface and the retrieval underneath it. The feature list follows the same order: an editor built for novel writing, model support, a responsive interface, configurable workflows, then the agent features, then local storage, retrieval, and cost.
Retrieval is vector-based and pitched at projects of a million characters
The retrieval feature is described as semantic search over the project, built on vectors, and its stated purpose is letting the agent find earlier information efficiently inside a project measured in hundreds of thousands of characters. That scale claim is the interesting part. It sets the design target: a novel long enough that an agent cannot hold it in context has to be able to look things up, and looking them up by meaning rather than by keyword is what survives a rewrite of the prose. The neighbouring feature entry is the cost one, and the two are related in practice. Multi-layer context handling with intelligent compression, dynamic truncation and stable caching is listed as the way to reduce what you spend, which is what you need if the alternative is re-reading large parts of a manuscript on every request.
Prompts are meant to be edited, and that is a feature rather than a gap
Two entries in the feature list are really the same instruction stated twice. Customisable workflows describe a configurable agent system where you are free to modify any prompt and build a workflow that is yours. Human and machine collaboration describes the same thing from the author's side: assistance integrated with the agent for diverging ideas, constructing plot and editing together, and explicitly not the one-click generation the page elsewhere refuses. The two scenes listed as fitting the tool reinforce that. If you have a full setting, a prose style and a direction for the plot and want help turning inspiration into text, you are the intended user. If you want the tool to have opinions you did not supply, this is the wrong shape of software.
Three install routes, and the container is the recommended one
There are three ways in and the page marks one as recommended for self-hosting. The container is a single line that publishes a port, mounts a named volume at a data path and names the container:
docker run -d -p 8000:8000 -v "openfic:/data" --name openfic ghcr.io/syrizelink/openfic:latestThe Python route warns first that you need 3.12 or newer, then installs the package from the index and starts the server with one command. The third route is a desktop application downloaded from the releases page, described as running natively on your system with no extra steps. Note what the volume argument does: it is the entire local persistence story, since the features claim no cloud storage dependency and the container command puts project data in a named volume on your disk. Everything else about the deployment follows from that one flag.
The image builds the frontend once and ships it inside the Python runtime
The container definition is a two-stage build with a deliberate asymmetry between them, and the comments say so. The frontend stage pins itself to the build platform and is described as building once, architecture-independent, because the output is static files. It installs Node, enables the package manager's corepack shim, copies the manifest and lockfile and a patches directory, installs with a frozen lockfile against a mounted store, then builds. The backend stage pins to the target platform, lists amd64 and arm64 as the outputs, copies a package manager binary from another image, syncs dependencies without development packages, and then syncs again to install the project itself, with a comment saying that is so the distribution metadata gets written for the runtime to read the version from.
The runtime reads its data path from one variable and serves on all interfaces
Two environment variables carry the whole runtime contract. One points at the frontend build output that was copied in from the first stage, so the server finds the static files without a separate web server. The other points at the data directory, defaulted to the path the volume is mounted at, and the image creates that directory during the build. The final command runs an application server bound to all interfaces on the published port, which is correct inside a container whose port is already controlled by the publish argument. The compose file in the repository adds a restart policy and the same three things the one-line command has: the image, the port, and the volume. The published port is the only thing exposed, and the data volume is the only thing persisted.
Editorial conclusion
OpenFic fits someone with an existing novel and an existing method: a maintained worldview, a cast, planted foreshadowing, and a sense of how the chapters fit. The agent's job there is retrieval and consistency checking across what you already wrote, which is what the vector index is for. Two things to weigh before committing. The tool states plainly that it is not built for turning one prompt into a finished novel, and that is a real constraint rather than marketing modesty, so if your plan is generation rather than maintenance you want something else. And the data lives in one mounted volume: that is what makes local storage work and also what you must back up yourself, since nothing on the page describes an export or a sync path.
Frequently asked questions
What is OpenFic and what is it for?
It is a local-first writing tool for long-form fiction, built around an editor aimed at novel writing with an agent system layered on top. The page's own position is that it is first a user-friendly novel writing tool and only second an AI agent system, and it lists long novels with a maintained worldview and cast as the case it serves.
What does OpenFic say it is not for?
Three exclusions, stated on the front page rather than buried. It is not for typing one prompt and receiving a whole novel automatically, which the page calls unrealistic. It is not aimed at short copy, social content or one-off general text generation. And it is not for you if you do not intend to maintain complex setting information or need long-lived context and workflow management.
How does OpenFic store project data?
Locally, with no cloud storage dependency. The container run mounts a named volume at a data path inside the container, and the image sets an environment variable pointing at that directory and creates it during the build. The compose file in the repository uses the same image, the same port and the same volume, and adds a restart policy.
How do I install OpenFic?
Three routes. A single container run from the project's published image, which the page calls the recommended way to self-host. A Python route that warns you need 3.12 or newer, installs the package from the index, and starts the server with one command. Or a desktop application downloaded from the releases page, described as running natively with no extra steps.
Does OpenFic support models other than one provider?
Yes. The model support entry describes working with models from several providers, and separately with any model compatible with the OpenAI API shape. The agent side adds vector-based retrieval over the project, described as working inside a project of hundreds of thousands of characters, plus multi-layer context handling with compression, dynamic truncation and caching to reduce cost.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/syrizelink-openfic)Star history chart for your README
[](https://hysenlabs.com/projects/syrizelink-openfic)Was this useful?