everything-ai-ml forbids hand edits to its README because a TypeScript file generates it
A curated collection of learning resources for Generative AI, Machine Learning, Agentic AI, LLMs, RAG, Fine-tuning, MLOps, and more.
At a glance
- What is it?
- This is a curated index of AI and machine learning resources that ships in two forms, a GitHub readme and an interactive cheatsheet site, both rendered from one data file. That single source is the whole architecture, and it explains both the consistency between the two surfaces and the parts of the index nobody reviews.
- Who is it for?
- Treat everything-ai-ml as a maintained link index rather than as a course, and use it the way its structure invites: open the cheatsheet to find the one link you need, then check that link yourself before relying on it. Two things to know before you build on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
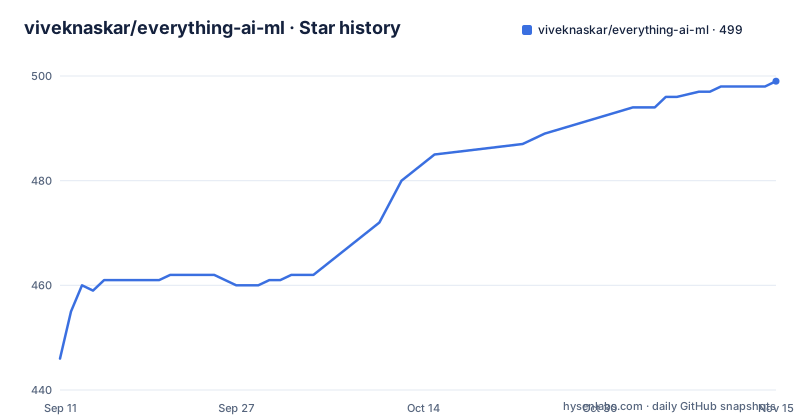
- viveknaskar/everything-ai-ml499 ★ · +53
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| viveknaskar/everything-ai-ml | 446 | 499 |
53 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README is generated, and the file says not to touch it
The first structural fact is a comment near the top of the readme, split here across two lines because the original is a single one:
<!-- AUTOGEN:START -->
<!-- generated from website/src/data/resources.ts via `npm run gen:readme` -->
So the readme is a build artifact, and the comment between those two halves tells the reader not to edit it by hand. The content lives in a TypeScript data file under website/src/data/resources.ts, a script regenerates the markdown, and a human editing the rendered output would lose their change on the next run. The start and end markers around the generated block are what make that boundary machine detectable rather than a convention.
The repository layout agrees with that reading. Everything above the generated block is prose and badges, and everything below is list content, while the top level holds only .github/, .gitignore, CONTRIBUTING.md, LICENSE, README.md and website/. There is no source directory, no tests, no build script and no other document: the entire project is one data file, a generator, and a static site.
That is also why the recorded primary language is TypeScript. Nothing about a link list needs a language, and a markdown-only repository would not have one, so the language field is really telling you that the data layer, not the content, is the project.
One release exists for the repository, v1.0.0 dated 2026-04-02, while the branch itself was last pushed on 2026-10-01. Six months of commits have accumulated without a second tag, which is unremarkable for a documentation repository and worth knowing if you pin to the release rather than to the branch.
Two surfaces, one data file, and the readme copy is the stale one
The repository exists to be read in two places. The primary home is a hosted page at viveknaskar.github.io/everything-ai-ml, which the file calls an interactive cheatsheet, and that is also the recorded homepage for the project. The readme links to it in a callout at the top, before the generated content begins.
Both surfaces draw on the same data, which is the strength of the arrangement. Adding a resource once in the TypeScript file updates the list and the cheatsheet together, and there is no chance of the two disagreeing about what the index contains.
The catch is that the readme is a projection, and a projection goes stale in a way a live page does not. The cheatsheet is whatever the current data file holds, while the readme is whatever the last run of the generator produced. A visitor browsing GitHub sees a snapshot, and nothing in the snapshot tells them when it was taken or which entries have since changed. For a list whose value is the links themselves, that difference matters most exactly where it hurts: a resource that was retired upstream still looks current in the readme.
The retrieved copy of the readme is also cut off partway through, three categories in, so most of what the project indexes is not visible here. The roadmap section breaks off mid-list, and everything from generative AI general through to interview preparation, which is most of the index, is behind the truncation.
Twenty nine headings, and four of them overlap
The table of contents names 29 sections. Most are the obvious categories for the subject, covering key concepts, building blocks, a roadmap, generative AI at general and advanced levels, prompt engineering, RAG, fine-tuning, agentic work, MLOps and GenAIOps, security, Google Cloud, cost optimisation, organisational adoption, productivity tools, quantum computing, the software development lifecycle, courses, certifications, books, research papers, tools and frameworks, video channels, research and applied blogs, communities, practice problems and interview preparation.
Four of those overlap with a neighbour. Frameworks appears as its own heading, and then Tools and Frameworks appears again at the end of the list. Research Blogs and Applied AI/ML Blogs are two headings covering the same kind of artifact, split on a distinction that is not defined anywhere in the file. Courses, Certifications and Books are three headings where two would serve, and Practice Problems and Interview Preparation sit next to each other with an implied relationship that is again undefined.
The practical effect is on search rather than reading. Someone who knows a resource exists and remembers that it was listed under frameworks has a one in two chance of looking in the wrong section, and the duplicate headings make a text search of the readme return either both halves or neither.
Coming Innovations in LLMs is the odd one out in a different way. It is the only heading that promises content the index cannot deliver, since a list of links cannot know what has not been released yet. It is worth reading as an editorial placeholder rather than a section.
Foundational concepts link out to blog posts, not to papers
The first section is the one to read closely, because it sets the tone for everything after it. Supervised learning points at a Medium article. Unsupervised learning points at Google Cloud's explainer. Reinforcement learning points at OpenAI's Spinning Up introduction. Deep learning goes to DataCamp, natural language processing goes to an ageitgey post on Medium, and computer vision goes to GeeksforGeeks.
From there the sources get better. Generative adversarial networks are explained by AWS, dimensionality reduction and clustering by scikit-learn's own documentation, Bayesian inference by StatLect lecture notes, time series analysis by a free forecasting textbook, and self-supervised learning by Lilian Weng's write up on her own site.
So the pattern is mixed by design, and the mixing is uneven in one direction. Conceptual and introductory topics lean on blog and tutorial sources, several of them community platforms rather than primary documentation, while topics with an obvious canonical reference point get the primary source. Neither choice is wrong for a learning index, but it does mean the first section is opinionated and the rest is closer to a bibliography.
The three interactive explainers are the strongest items in the visible portion. MLU-Explain offers interactive visual explanations of core concepts, and the CNN Explainer and Transformer Explainer from the same group cover convolutional networks and the transformer architecture in the browser. For a field where the diagrams in most tutorials are static images, that is the part of the index most worth bookmarking.
The roadmap links a 2010 course archive and a pinned tutorial version
The building blocks section uses current documentation. Mathematics for machine learning is a Berkeley lecture note PDF, linear algebra is MIT OpenCourseWare course 18.06 from spring 2010, probability and statistics are a Stanford lecture series, and optimisation, feature engineering, regularisation and hyperparameter tuning are all served from GeeksforGeeks, while model evaluation comes from scikit-learn's stable documentation.
The roadmap section points at different places. Python is Harvard CS50's 2022 edition of its Python course, and the advanced course is the edX version of CS50's introduction to artificial intelligence with Python. NumPy links to its dev docs quickstart and Matplotlib to its stable tutorials, both of which track current releases.
Then there is Pandas, which links to the W3Schools tutorial, and scikit-learn, which links to version 1.4 of its tutorial rather than to stable. Both are the kind of link that works until the upstream reorganises, and the 1.4 pin is the more fragile of the two since a version specific path stops existing when the docs are rebuilt. The MIT course from spring 2010 is old in the same way, though an archived course is a different risk from a version specific documentation path because the archive is unlikely to move.
The pattern across the whole index is that nothing is verified automatically. A generated readme guarantees the list and the site agree with each other, which is not the same as guaranteeing any individual link still resolves.
One release, one newsletter link, and a license with a sponsor button
The header carries the ordinary furniture of a curated list. Two badge links sit at the top, one to the licence file and one to the sponsor page for the author, and the sponsor link is not decoration, since the list is someone's ongoing curation work and the page doubles as a portfolio entry.
The other header link is a newsletter, presented as a way to stay updated on the subject. That is the one outbound link with a commercial purpose in the file, and it sits above the generated block where it does not get regenerated, which is the correct place for it. Everything about the resources themselves is inside the generated region and comes from the data file, which keeps the promotional surface and the curated surface separable.
Licensing is MIT and the file is present at the root, which for a list of links raises a question the file does not discuss. MIT covers the curation, the data file, the generator and the site template. It does not cover the linked material, which keeps its own terms, and the index says nothing about that boundary. A reader who assumes everything under the licence is covered by it would be wrong about every entry in the list.
Contributing is handled by a separate document at the root rather than in the readme, so the route for proposing a resource exists but is not described where a reader would look for it.
Editorial conclusion
Treat everything-ai-ml as a maintained link index rather than as a course, and use it the way its structure invites: open the cheatsheet to find the one link you need, then check that link yourself before relying on it. Two things to know before you build on it. The category taxonomy overlaps, with frameworks and research blogs each appearing twice, so a search of the index can miss a resource that exists under the neighbouring heading. And the entry points are uneven in age, with a course archive and a version pinned tutorial sitting next to stable documentation links, which means a stale link will not announce itself.
Frequently asked questions
How is the viveknaskar/everything-ai-ml README maintained?
It is generated. The file carries an autogenerated marker that says not to edit it by hand, because it is produced from website/src/data/resources.ts by the npm run gen:readme script, and the same data drives the hosted cheatsheet.
What is in the viveknaskar/everything-ai-ml repository?
A top level with .github/, .gitignore, CONTRIBUTING.md, LICENSE, README.md and a website directory. The content itself is a curated list of AI and machine learning learning resources across 29 categories.
How many categories does everything-ai-ml index?
The table of contents names 29, from AI/ML key concepts and building blocks through a roadmap, frameworks, agentic AI, MLOps, courses, books, research papers, blogs, communities and interview preparation.
Does everything-ai-ml have interactive explanations?
It links three. MLU-Explain offers interactive visual explanations of core machine learning concepts, and the CNN Explainer and Transformer Explainer cover convolutional networks and the transformer architecture in the browser.
Are there releases for viveknaskar/everything-ai-ml?
One, v1.0.0 dated 2026-04-02. The branch was last pushed on 2026-10-01, so work after that release exists on main without a tag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/viveknaskar-everything-ai-ml)Star history chart for your README
[](https://hysenlabs.com/projects/viveknaskar-everything-ai-ml)Was this useful?