Haystack 3.4: A Python framework for building LLM pipelines with explicit control
Open-source AI orchestration framework for building context-engineered, production-ready LLM applications. Design modular pipelines and agent workflows with explicit control over retrieval, routing, memory, and generation. Built for scalable agents, RAG, multimodal applications, semantic search, and conversational systems.
At a glance
- What is it?
- Haystack is an open-source Python framework for assembling RAG systems, agents, and semantic search applications from modular components. This review covers its pipeline model, agent hooks, async support, and where its design trade-offs matter.
- Who is it for?
- Adopt Haystack if you need a Python-native, vendor-agnostic framework where every retrieval, routing, and generation step is explicit and inspectable. Avoid it if you want a fully managed platform or if your team prefers a configuration-driven approach over writing Python code.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
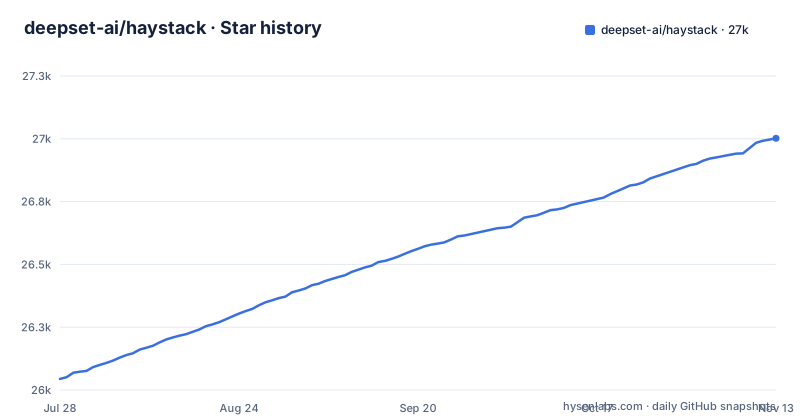
- deepset-ai/haystack27,002 ★ · +958
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| deepset-ai/haystack | 26k | 27k |
958 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Haystack actually solves
Haystack addresses a specific pain: LLM applications are rarely a single model call. They involve retrieval, reranking, memory, tool selection, and generation, and the order matters. Haystack gives you a Python framework to compose these steps into pipelines and agent workflows. The target user is a developer who wants explicit control over how context is built before it reaches the model. The README stresses "transparent architecture" and "explicit control," which means you are not hiding the orchestration logic inside a black box. This is for engineers who need to see and modify every step, not for teams looking for a no-code platform.
Pipeline architecture and context engineering
The core idea is a Pipeline that connects components. Each component handles one task: retrieval, indexing, tool calling, memory, or evaluation. You can add loops, branches, and conditional logic. This is not a linear chain. The documentation describes "explicit control over how information is retrieved, ranked, filtered, combined, structured, and routed before it reaches the model." That is the essence of context engineering. Instead of stuffing everything into a prompt, you decide the flow. For example, you might retrieve documents, filter them by metadata, rerank, and then pass only the top results to the generator. The pipeline makes that flow visible and testable. A trade-off is that you must design that flow yourself. Haystack gives you the lego bricks, not the final castle.
Agent lifecycle hooks and observability
For agent workflows, Haystack introduces lifecycle hooks: before_llm, before_tool, on_exit, and others. These let you inject guardrails or custom logic at specific points in the agent's execution. The README also mentions tracking step_count, token_usage, and tool calls out of the box. That is useful for monitoring and cost control. This is a concrete mechanism, not a vague promise. You can intercept a tool call before it executes, which is where many safety issues arise. The hooks give you a place to enforce policies. Consult the documentation or the Agent Pack integrations for the exact signatures.
Installation and getting started
Installation is straightforward: pip install haystack-ai. There is also a nightly pre-release channel with pip install --pre haystack-ai. Docker images are mentioned, but the README points to the documentation for details. The package name is haystack-ai, not haystack, which matters if you are adding it to a requirements file. The README suggests starting with the "What is Haystack?" overview, then the Get Started Guide. There are tutorials and a Cookbook with recipes. The Agent Pack is a separate repository under deepset-ai/haystack-core-integrations, so you install it separately. The core package gives you the Pipeline and base components, but many integrations live in that separate repo. That is a practical detail for your build process.
Async support and streaming
Haystack has native async support. A single Pipeline can run synchronously or asynchronously, and it can stream tokens. Agents can run concurrent tool calls. This is a significant design choice. Many orchestration frameworks handle async as an afterthought. Here, it is built into the core. For production workloads, this matters because you can handle multiple requests without blocking. Streaming is essential for chat applications. A limitation is that you need to understand Python's asyncio model to use it effectively. If your team is not comfortable with async, you can still run pipelines synchronously, but you lose the concurrency benefits.
Vendor neutrality and integration breadth
Haystack is model- and vendor-agnostic. The README lists OpenAI, Mistral, Anthropic, Cohere, Hugging Face, Google, Azure OpenAI, AWS Bedrock, and local models. You can swap models without rewriting the pipeline. This is a real advantage over frameworks that lock you into one provider. The integrations are not all in the core package. Many live in haystack-core-integrations. That means you need to manage multiple dependencies, but it also keeps the core lean. The trade-off is that integration quality varies. Some providers may have more mature components than others. You should check the specific integration's documentation before relying on it.
Limitations and when Haystack is the wrong tool
Haystack is not a managed platform. You are responsible for deployment, scaling, and monitoring. The framework gives you building blocks, not a runtime. If you want a fully hosted solution, Haystack Enterprise exists, but that is a separate offering. Another limitation is the learning curve. The pipeline model is flexible, but that flexibility means you must design the architecture yourself. There is no default pipeline that works for every use case. Also, the README mentions telemetry, which may raise privacy concerns for some deployments. Check the README's Telemetry section and the documentation for what is collected and how to disable it. Finally, Haystack may be overkill for simple single-model applications. If you just need to call an API, a direct client is simpler.
Alternative approaches and maintenance cost
A common alternative is LangChain, which takes a different approach: it provides predefined chains and agents with a higher-level abstraction. Haystack's pipeline model is more explicit and lower-level. You write more code, but you have more control. Another alternative is LlamaIndex, which focuses on data indexing and retrieval. Haystack aims to cover both. On maintenance, Haystack is under active development. The last push was on 2026-11-02, and version 3.4.1 was released on 2026-10-21. The project has a CI/CD pipeline, mypy type checking, and ruff linting, which suggests a mature codebase. The license is Apache-2.0, which is permissive for commercial use. You should budget time for upgrading between minor versions, as the 3.0 release was a major change. The repository includes a MIGRATION.md file at the top level.
Editorial conclusion
Adopt Haystack if you need a Python-native, vendor-agnostic framework where every retrieval, routing, and generation step is explicit and inspectable. Avoid it if you want a fully managed platform or if your team prefers a configuration-driven approach over writing Python code. Before committing, verify that the components you need are available in the core package or the integrations repo, and test the agent lifecycle hooks against your guardrail requirements. The framework's strength is transparency, so confirm that its pipeline model matches how you want to control context flow.
Frequently asked questions
Is Haystack free to use?
The framework is open source under the Apache-2.0 license, published on PyPI as haystack-ai and on conda-forge. The README also has a section on Haystack Enterprise, which is the project's commercial support and platform offering and is separate from the framework.
How do I install Haystack?
The simplest way is pip install haystack-ai. To try the newest features from nightly pre-releases, use pip install --pre haystack-ai. The documentation also describes Docker images and other installation methods, and the project requires Python 3.11 or newer.
How do I use Haystack to build an LLM application?
The README points new users through What is Haystack, then a Get Started Guide, then the tutorials, with recipes in the Cookbook for more advanced cases. A pipeline is built by connecting built-in or custom components, and the framework supports loops, branches and conditional logic.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepset-ai-haystack)Star history chart for your README
[](https://hysenlabs.com/projects/deepset-ai-haystack)Was this useful?