WebBrain ships 112 provider cards on Chromium, 111 on Firefox, and one test command that chains thirty suites
Open-source AI browser agent for Chrome and Firefox (monorepo) 🧠
At a glance
- What is it?
- An open source browser agent with a side panel, three permission modes, and a model layer wide enough to include a managed default that needs no key, local servers on six ports, and a cloud catalogue of over a hundred cards, with a research sharing switch that exports tool names and error codes but never page content.
- Who is it for?
- WebBrain suits someone who wants an agent in the browser rather than beside it, and who would rather point it at a local server than hand page content to a vendor. Four things to check.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
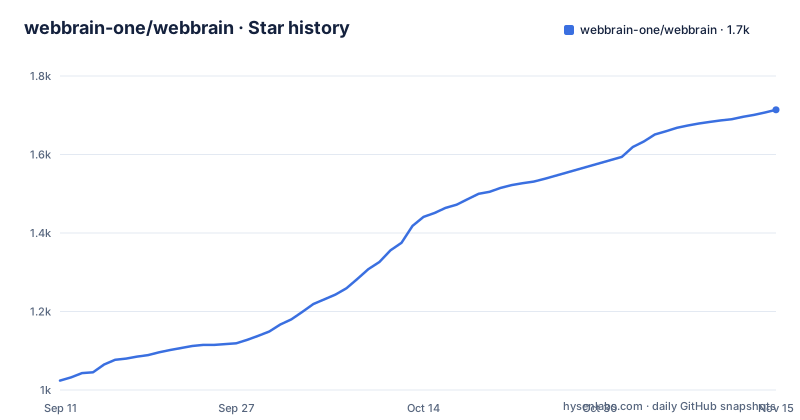
- webbrain-one/webbrain1,714 ★ · +690
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| webbrain-one/webbrain | 1k | 1.7k |
690 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One repository carrying five deliverables and three readmes
The top level is wider than a browser extension needs to be. Alongside the extension sources in `src/`, there is `dist/`, `docs/`, `examples/`, `ci/`, `scripts/`, `assets/`, `test/`, `web/`, and three directories that are separate products in their own right: `firefox-companion/`, `lmstudio-plugin/` and `mcp-server/`.
So the repository ships at least five things: the extension itself, a companion for Firefox, a plugin for LM Studio, a Model Context Protocol server, and a web surface. The repository description calls it a monorepo for Chrome and Firefox, which is accurate and understates it.
Documentation is triplicated at the root, with an English readme, a Simplified Chinese one and a French one, all linked from the header alongside the docs directory, the website, a Discord invite and the license. Three readmes is a maintenance commitment that most projects of this size do not take on.
Two other root files are worth naming because they are not usual for a published extension: `AGENT.md`, a single file rather than the plural spelling, and `TODOs.md`. Both are the project's own working notes committed to the tree, alongside `CHANGELOG.md`, `GOVERNANCE.md`, `SECURITY.md`, `CODE_OF_CONDUCT.md` and `CONTRIBUTING.md`.
The license is worth reading carefully too. The repository's license field is empty, the header links the license as GPL-3.0-or-later, and both a `LICENSE` file and a `LICENSES/` directory sit at the top level. The declared terms and the repository metadata do not agree, and no single file is obviously the authoritative one.
The unpacked load paths disagree about the directory name
Loading from source is documented per browser, and the two sets of instructions do not use the same paths.
Start with the clone:
git clone https://github.com/webbrain-one/webbrain.gitFor Chrome the instructions are to open `chrome://extensions/`, enable Developer mode, click Load unpacked, and select the `webbrain/src/chrome` folder. That path contains a `webbrain` segment inside a repository already named webbrain. There is also a cleaner route: run `npm run build:chrome` first and load `webbrain/build/chrome` instead, which is described as an isolated copy that will not pick up stray working tree files.
For Firefox the folder is given without that extra segment: open `about:debugging#/runtime/this-firefox`, click Load Temporary Add-on, and select `src/firefox/manifest.json`, or `build/firefox/manifest.json` after `npm run build:firefox`.
So one instruction nests the extension inside another `webbrain` directory and the other does not. Whether that is because the build output is nested and the Firefox path is relative to it is not explained, and picking the wrong one produces a load failure with a message that will not tell you which of the two you chose.
Two Firefox facts are stated plainly and matter more than the path. Temporary add-ons are removed when Firefox restarts, and permanent installation requires signing through addons.mozilla.org. The build output also goes to `build/`, while a `dist/` directory is committed at the root, and the visible text does not say what `dist/` holds.
Three modes, and Dev is the one with reversible edits
What the agent is allowed to do is controlled by three modes rather than by a single on and off switch.
Ask is read only. It reads the page, answers questions and fetches URLs. Act is the mode that changes things: it clicks, types, navigates, uploads, downloads and fills forms. Dev adds the developer surface, which is page source, styles, console and network, plus page edits that are described as reversible.
The reversibility claim is the one to test first, because Dev is the only mode that writes to the page you are reading. Edits that can be undone are a different proposition from edits that cannot, and the file does not say what the undo covers.
Two related mechanisms sit underneath the modes. Consequential actions raise a per site permission prompt, so consent is asked at the site level rather than once for the whole session. And Act and Dev can generate a structured plan, show it for approval, and pin the approved plan to the scratchpad before any tool runs, which means the agent works from a plan you have seen rather than from an intention it formed silently.
Page reading is built on the accessibility tree rather than on selectors, and that choice shows up everywhere. It survives class name churn and redesigns, and it sees nothing on a canvas or in a picture. It is also why the mode list includes a Dev mode at all: when the accessibility tree is not enough, the fallback is to hand the agent the page source.
Six local servers, two of which default to the same port
The local model story is one shape: any OpenAI compatible server. Four are given as commands:
llama-server -m your-model.gguf --port 8080          # llama.cpp
ollama serve                                          # Ollama  → :11434/v1
vllm serve your-model --port 8000                     # vLLM    → :8000/v1
python -m sglang.launch_server --model-path your-model --port 30000
Then five more are named with the port they answer on: LM Studio on 1234, Osaurus on 1337, Jan on 1337, LocalAI on 8080 and GPT4All on 4891.
Two collisions fall out of that list. Osaurus and Jan are both given as port 1337, so you cannot run both defaults at once. LocalAI is given as 8080, which is also the port in the llama.cpp example, though that one is a command line flag rather than a fixed default.
Beyond those there is a generic Local OpenAI compatible Proxy card that supports authenticated loopback gateways, with a worked subscription proxy setup documented for CLIProxyAPI, and dedicated cards for Unsloth Studio, where the user supplies the studio port and an API key with a particular prefix, and for Osaurus, with model discovery, streaming and tool calls.
The window requirement is the other hard number. Load a model with at least a 16k token context: 8k works only with the Compact tier, and 4k is too small for the system prompt plus the tool schemas. The Compact tier is named without being explained anywhere in the visible text, which is the one gap in an otherwise specific set of requirements.
112 cards on Chromium, 111 on Firefox, and a local option with no endpoint at all
The cloud list names OpenAI, Anthropic Claude, Google Gemini, Azure OpenAI, AWS Bedrock, Mistral, DeepSeek, xAI Grok, MiniMax, Kimi, Qwen, z.ai GLM, Groq, Together, Cloudflare, Nvidia NIM, Hugging Face, Fireworks and OpenRouter, and then says and more.
The number is the more useful figure. Settings ships 112 built in provider cards on Chromium and 111 on Firefox. One card is missing on Gecko, and nothing in the file says which one or why. For a project that maintains a catalogue by hand, that single card is either a deliberate platform exclusion or an oversight, and either way it is the kind of detail worth asking about before you rely on a specific provider in Firefox.
Two entries in the catalogue are worth singling out because they are not cloud cards at all. One is an endpoint free local WebGPU option with a tested preset for a 2.6B parameter model, which runs inference in the browser with no server and no key. The other is an experimental option for a custom Hugging Face repository using ONNX.
Auto detection is handled in layers. WebBrain auto detects the real context window for llama.cpp, Ollama and LM Studio and compacts the conversation as it fills. For Ollama, llama.cpp, LM Studio and LocalAI it also reads native server metadata before deciding to add screenshots to a request, with Auto, Force on and Off overrides in Settings. And when the optional model field is left blank, the loaded model capability is rechecked on every user turn, so a server side hot swap takes effect without reopening the panel.
The research switch exports tool names and error codes, and never page content
Data sharing is one switch per provider, called Share queries for research, and it is off by default. What it exports has been narrowed in a specific way, and the narrowing is described precisely enough to be checked.
Alongside the existing scrubbed prompt and response share, enabling the switch adds a bounded, content free diagnostic timeline for that provider's model attempts, including runs that failed. The timeline contains tool names, outcomes, error codes and timings. It does not contain tool arguments, page content or screenshots.
That is a well chosen boundary. Tool names and error codes are what you need to see that a provider is rejecting a particular tool call shape, and they are also close to useless for reconstructing what you were looking at. Arguments and page content are exactly what would make a diagnostic timeline sensitive, and they are the two things excluded, along with images.
There is one case that goes beyond the timeline. If a run fails before a normal generation share happens, the bounded model facing request and the final blocker travel with the diagnostic record, so a failure that never produced a share is still visible.
The ergonomics are deliberate too. There is no second switch to discover for the new timeline data, and turning the existing switch off also purges diagnostics that are queued but not yet sent.
One test command, about thirty suites, and a captcha provider matrix
The package manifest defines a single test entry point, and it is a chain. `npm test` runs the CMS suite, then the markdown suite, then two system suites, then a `node --test` invocation naming thirteen individual files, then the Firefox BiDi suite, the runtime lifecycle suite, provider limits, an accessibility tree benchmark, a toolbar guard, a cloud bridge approval suite, a Discord suite, two PDF suites, a social contract suite, a safe social suite, a build unpacked suite, an attachment drop suite, a workflow editor suite, a profile sync statistics file, the main runner, a selection scope restoration script, an offline relevance benchmark script, and finally the security suite.
That is roughly thirty suites behind one command, with no way to run a subset without reading the string.
The named files are where the project's real priorities show. Seven of the thirteen individually listed files are captcha related: a cloud broker, providers, a weighted fallback, hCaptcha providers, native providers, a runtime policy, a callback bridge, and an AWS recovery path. Alongside them sit a Hugging Face signup recovery file and a trace full export file, and there are separate scripts for the captcha settings and application interfaces and for the captcha callback bridge interface.
A cloud bridge approval server appears in the examples directory and again as a test suite, which suggests the same approval flow is exercised in both directions.
Everything else in the tree points the same way. A coverage benchmark for the accessibility tree is wired into the default test run, a schedule and watch feature exists for deferred work and polling, and a saved workflow can be exported and shared. That last one is described as value free, which is the detail that makes sharing safe: a reusable workflow carries the steps and not the values that made it work, so it cannot carry a credential with it.
Editorial conclusion
WebBrain suits someone who wants an agent in the browser rather than beside it, and who would rather point it at a local server than hand page content to a vendor. Four things to check. Reading goes through the accessibility tree, which is the right call for durability and the wrong one for pages that expose nothing useful there. The model catalogue is versionless, so a provider card is a promise rather than a contract. Saved workflows are described as value free, which is what makes them shareable and also what stops them carrying credentials. And the entire test suite is one command, so a partial run is not something the project offers.
Frequently asked questions
What are the three modes in WebBrain?
Ask is read only, reading the page, answering questions and fetching URLs. Act clicks, types, navigates, uploads, downloads and fills forms. Dev adds the developer surface, which is page source, styles, console and network, plus page edits that are described as reversible. Consequential actions raise a per site permission prompt before they run.
Do I need an API key to use WebBrain?
No. WebBrain Compass 1.0 is the default and needs no API key or local setup, and local models need no key either as long as you point WebBrain at an OpenAI compatible server such as llama.cpp, Ollama on port 11434, vLLM on port 8000 or SGLang on port 30000.
How much context window does a WebBrain model need?
At least a 16k token context. 8k works only with the Compact tier, and 4k is too small for the system prompt plus the tool schemas. WebBrain auto detects the real window for llama.cpp, Ollama and LM Studio, and auto compacts the conversation as it fills up.
What does WebBrain share when research sharing is on?
Alongside the existing scrubbed prompt and response share, the switch adds a bounded, content free diagnostic timeline for that provider's model attempts, including failed runs: tool names, outcomes, error codes and timings. It does not include tool arguments, page content or screenshots. Turning the same switch off also purges queued diagnostics.
How do I install WebBrain from source?
Clone the repository, then for Chrome open chrome://extensions/, enable Developer mode, click Load unpacked and select webbrain/src/chrome, or run npm run build:chrome first and load webbrain/build/chrome. For Firefox, open about:debugging#/runtime/this-firefox, click Load Temporary Add-on and select src/firefox/manifest.json; temporary add-ons are removed when Firefox restarts, and permanent installation requires signing through addons.mozilla.org.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/webbrain-one-webbrain)Star history chart for your README
[](https://hysenlabs.com/projects/webbrain-one-webbrain)Was this useful?