DragGAN: Editing Images by Dragging Points on the GAN Manifold
Official Code for DragGAN (SIGGRAPH 2023)
At a glance
- What is it?
- DragGAN is the official SIGGRAPH 2023 code for Xingang Pan and colleagues' point-based GAN editing method, where a user drags a point on a generated image and the model reshapes the picture to follow it. Its own license splits the algorithm from the StyleGAN3 code it builds on.
- Who is it for?
- A researcher with a CUDA card, or an Apple Silicon Mac willing to run the CPU-only environment file, is who this repository is built for. Someone who wants to edit their own photograph directly should look elsewhere first, since DragGAN's GUI only edits GAN-generated images unless a separate tool like PTI has already produced a latent code for a real one.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Probably not. The repository last received commits 30 months ago, on May 18, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
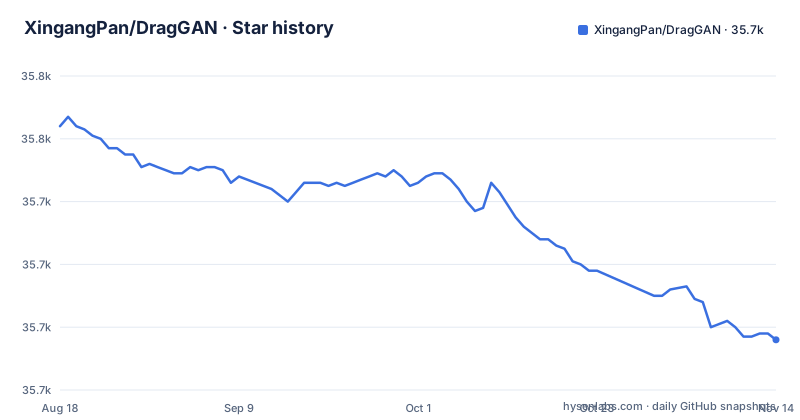
- XingangPan/DragGAN35,696 ★ · -68
| Repository | 2026-08-18 | 2026-11-14 |
|---|---|---|
| XingangPan/DragGAN | 35.8k | 35.7k |
-68 Stars in the last 88 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Dragging Points on a Generative Image Manifold, Not Editing Pixels
The README's own title names the method exactly: "Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold," credited to Xingang Pan, Ayush Tewari, Thomas Leimkuhler, Lingjie Liu, Abhimitra Meka and Christian Theobalt, published in the SIGGRAPH 2023 Conference Proceedings and linked to a paper on arXiv (2305.10973). This is a research group's official release of the code behind that paper, not a packaged consumer app, and the GUI it ships edits an image by moving a handful of points rather than painting or masking pixels directly.
Anyone without a GPU or a local Python setup can try two hosted demos the README links directly: one on OpenXLab and one on Hugging Face Spaces (radames/DragGan). The full local setup, covered below, starts with a CUDA graphics card by default.
Two Install Paths: CUDA via conda, or a Trimmed Environment for CPU and Apple Silicon
The README's default path assumes an NVIDIA GPU and follows NVlabs/stylegan3's own requirements. It sets up the environment with:
conda env create -f environment.yml
conda activate stylegan3
pip install -r requirements.txt
requirements.txt pins real versions behind that install: torch>=2.0.0, gradio>=3.35.2, Ninja==1.10.2 and glfw==2.6.1 among them, so the GUI's dependency on a windowing library (glfw) and a scientific stack (scipy, torchvision) is visible before anything downloads weights.
For a Mac with Apple Silicon, or any machine without CUDA, the README gives a second path that strips the GPU-specific lines out of the same environment file first:
cat environment.yml | \
  grep -v -E 'nvidia|cuda' > environment-no-nvidia.yml && \
    conda env create -f environment-no-nvidia.yml
conda activate stylegan3
export PYTORCH_ENABLE_MPS_FALLBACK=1
That last environment variable tells PyTorch to fall back to CPU for operations Apple's Metal backend does not yet implement.
The Docker Path Is CUDA-Only and Costs 25GB
A third route runs the Gradio visualizer in Docker instead of a local conda environment:
docker build . -t draggan:latest
docker run -p 7860:7860 -v "$PWD":/workspace/src -it draggan:latest bash
cd src && python visualizer_drag_gradio.py --listen
The Dockerfile explains why that image is heavy: it starts from nvcr.io/nvidia/pytorch:23.05-py3, Nvidia's own PyTorch container, and layers on X11 and OpenGL development packages, libgl1-mesa-dev, libglu1-mesa-dev, xorg-dev and several more, needed for the GUI's rendering. The README states the obvious consequence directly: "Beware the Docker image takes about 25GB of disk space!" The README adds an optional --gpus all flag on the run command for anyone who wants to use an Nvidia GPU inside the container.
Weights Download Separately, and the GUI Only Edits Images It Generated
Cloning the repository gets the code, not the model. A separate step fetches the pretrained StyleGAN2 weights:
python scripts/download_model.pyTwo more weight sets, for StyleGAN-Human and the Landscapes HQ dataset, are linked as direct downloads the README says to place under ./checkpoints manually rather than through that script. Only once weights exist does the GUI do anything, launched with sh scripts/gui.sh on Mac or Linux, or .\scripts\gui.bat on Windows, with python visualizer_drag_gradio.py as a Gradio-based alternative that the README calls universal across both platforms.
The README is explicit about a real limitation here: the GUI "supports editing GAN-generated images" directly, meaning images the model itself produced from a random latent code. To edit an actual photograph instead, the README says a user must "first perform GAN inversion using tools like PTI," an external project, before loading the resulting latent code and weights into DragGAN's own interface. There is no built-in path from a real photo straight into the drag interface.
GAN Inversion Required, Unlike a Diffusion Editor That Takes a Photo Directly
That inversion requirement is where DragGAN's approach differs most from diffusion-based image editors, the other common way to edit a photograph with a prompt or a gesture today. A diffusion-based editor typically takes a real photo as input and edits it in place. DragGAN's manifold is built from a GAN's latent space, so a real photo first has to be projected into that space by a separate tool, PTI in the README's own example, before point-dragging can touch it at all.
The tradeoff is not simply quality; it is workflow. A user who only ever wants to explore and tweak images the model itself generates never needs inversion and gets the full interactive dragging experience the paper describes. A user who arrives with their own photograph pays an extra, separate step before the first drag, and the README does not document how well that inversion preserves identity or detail, only that the tool exists.
Two Licenses in One Repository, Plus a Required Watermark
The README splits its own licensing instead of applying one blanket term. "The code related to the DragGAN algorithm is licensed under CC-BY-NC," a non-commercial Creative Commons license, while "most of this project," the code used or modified from StyleGAN3, falls under the Nvidia Source Code License instead. A reader cannot treat this repository as carrying one license; which file a given line lives in decides which terms apply, and GitHub's own license field returns NOASSERTION, meaning it could not resolve that split into one standard answer either.
One condition applies regardless of which license covers a given file: "Any form of use and derivative of this code must preserve the watermarking functionality showing 'AI Generated'." On activity, the repository shows no GitHub releases at all, and its last recorded push was on 2024-05-18, well over a year before this article was written. That date, not any claim about ongoing maintenance, is what a user should check before relying on this code today.
Editorial conclusion
A researcher with a CUDA card, or an Apple Silicon Mac willing to run the CPU-only environment file, is who this repository is built for. Someone who wants to edit their own photograph directly should look elsewhere first, since DragGAN's GUI only edits GAN-generated images unless a separate tool like PTI has already produced a latent code for a real one. Before building on this code, read both license files: the DragGAN algorithm itself is CC-BY-NC, while most of the surrounding codebase carries Nvidia's own source license from StyleGAN3, and derivatives of either must keep the required AI Generated watermark.
Frequently asked questions
Is DragGAN free to use?
The code is free to clone and run, but the README splits the license: the DragGAN algorithm itself is CC-BY-NC, a non-commercial license, while most of the surrounding codebase carries Nvidia's own Source Code License from StyleGAN3.
Can you run DragGAN without an NVIDIA GPU?
Yes. The README gives a separate path that strips the nvidia and cuda lines out of environment.yml before creating the conda environment, and sets PYTORCH_ENABLE_MPS_FALLBACK=1 for Apple Silicon Macs or CPU-only machines.
Do you need to download model weights separately from the code?
Yes. Cloning the repository does not include weights; the README has you run python scripts/download_model.py for the pretrained StyleGAN2 weights, with StyleGAN-Human and Landscapes HQ weights as optional separate downloads placed under ./checkpoints.
Can DragGAN edit a real photograph directly?
Not directly. The README states the GUI supports editing GAN-generated images, and that editing a real photo first requires GAN inversion with an external tool such as PTI before loading the resulting latent code into DragGAN's interface.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xingangpan-draggan)Star history chart for your README
[](https://hysenlabs.com/projects/xingangpan-draggan)Was this useful?