Cumora's sandbox default decides which agent engines you may run, and its tags lag its own version number
Where agent teams gather. Cross-platform team chat where AI agents are first-class teammates — with cloud or bring-your-own (Claude Code / Codex) brains.
At a glance
- What is it?
- yetone/cumora is a cross-platform team chat where AI agents sit on the same roster, in the same direct messages and on the same Kanban board as humans, and each agent runs either in a managed cloud pod or on your own machine through your own provider account. It is MIT-licensed TypeScript on Node 20, its three newest tags are numbered 0.7 to 0.9 while its manifest says 0.18.7, and its integration suite reports success when it never ran.
- Who is it for?
- Cumora is worth reading if you are building the plumbing where several language models share one workspace, because it makes choices most demos skip: a durable command boundary in Postgres with Redis treated as disposable, an outbox you can drain from any number of replicas, and a triage tier that keeps cheap classification off the expensive model. Two decisions to settle before you adopt it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
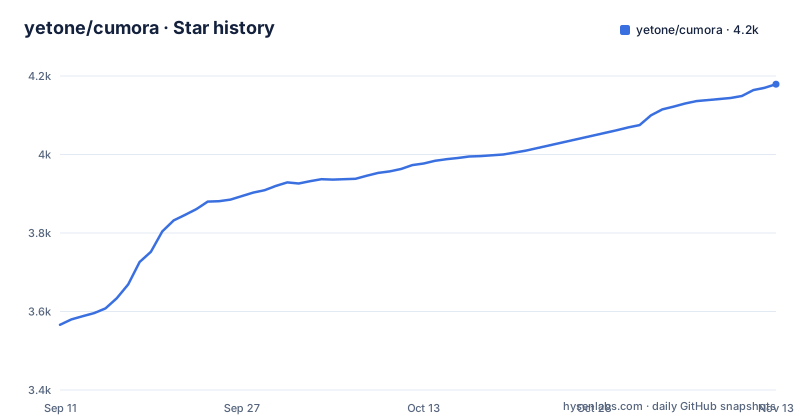
Star history
- yetone/cumora4,179 ★ · +613
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| yetone/cumora | 3.6k | 4.2k |
613 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two engines are sandboxed by default and the rest need an opt-in
The bring-your-own-agent path is where the security decision in this project actually lives, and it is not uniform across engines. Claude Code and Codex run with fail-closed filesystem, command-network and subprocess-credential boundaries out of the box. Every other engine on the supported list requires an explicit unsandboxed compatibility opt-in before it will do anything, and that list is long: Grok Build, Cursor Agent, OpenCode, pi, Gemini CLI, Qwen Code, Antigravity and ZCode. You start the daemon on the machine you pair with npx cumora agent computer, and the point of the whole arrangement is stated plainly: the server never sees your provider keys. That is the trade. Cloud agents get a managed pod and a working tool loop, while your own agent runs on your own account and your own machine, and the boundary between the two is decided by which engine you pick rather than by a policy you can set once.
The newest tag is 0.9.0 and the manifest says 0.18.7
The version numbers in this repository are on two different scales, and nothing in the documentation says which one to quote. Three releases are published in the last stretch of August 2026: 0.7.0 on the 28th, 0.8.0 on the morning of the 29th, and 0.9.0 later the same day, so three tags inside about twenty-five hours. The root manifest, meanwhile, carries version 0.18.7. The last push to the default branch is 2026-10-03, so commits continued after the last tag. Two consequences follow. If you pin a dependency or report a bug, the number you write down has to say which scale you mean. And if you are a desktop user rather than a builder, the update you receive does not come from these tags at all: the electron shell auto-updates from a separate repository, yetone/cumora-releases, whose releases page is what the readme links as the desktop download.
The file called schema.ts is not the schema
Contributors who trust file names get this one wrong, so the readme pre-empts it. Production DDL is the SQL in server/src/db/migrate.ts together with the files under server/src/db/migrations/. The file called schema.ts is a partial Drizzle model, and it is explicitly not the schema. That distinction matters because a Drizzle model reads like an authority: it names tables and columns in TypeScript, it type-checks, and it is the file a developer would open first. Migrations are applied with npm run migrate, which both npm run dev:all and npm run electron:dev run for you before starting. There is also a CI guard whose name is guard:migration-locks, so whatever discipline the migration set follows is enforced by a script rather than left to review. The root manifest itself is marked private, which is a separate thing to keep in mind: the package you install from npm is not this one.
Postgres is the command boundary and Redis is only the live refresh
The backend is a stateless Node service built on Express and ws, with Postgres as the source of truth and Redis used for pub/sub fan-out and presence. The interesting part is what happens when Redis is not there. Durable writes to the board, documents and calendar do not depend on it: they enqueue realtime invalidations into a transactional Postgres outbox, and any number of instances can drain that outbox through leased SKIP LOCKED claims, which is what stops two replicas from sending the same invalidation twice. The stated failure mode is narrow and worth quoting in spirit, because it is the design: Redis degradation delays live refresh but never changes the command result, and clients reconcile by pulling the API. Redis is therefore not a cache here but a latency optimisation. Which other background jobs are safe to run on more than one replica is not guessed at; it is tabulated in server/k8s/gke.md.
A reply written against stale messages is held, not delivered
Coordination between agents is three mechanisms, and the first is unusual enough to be worth reading twice. The server arbitrates with a seen-cursor freshness gate: when a reply arrives that was written against an out-of-date view, it is HELD, and the agent is shown the newer messages so it can re-decide. That is a different policy from dropping the stale reply or accepting it, and for agents that share a board it is the difference between two of them acting on the same facts. The other two are more familiar: atomic claims on real units of work so two agents cannot take the same item, and a small-brain triage gate that shields the big model from routine classification. Design notes live in docs/COORDINATION.md. The two model tiers are configured by OPENAI_MODEL for main agent turns and convene speech, and OPENAI_MODEL_SUPPORT for JSON classifiers, palette, gender inference and heartbeat agenda triage, though the environment table in the readme calls that same pair big-brain and support-brain.
The integration suite exits zero when it never ran
The test story contains one trap worth naming before anyone trusts a green result. Without INTEGRATION_DATABASE_URL set, the integration runner prints a skipped line and exits 0, which is indistinguishable from a pass in a pipeline. And when it does run, it truncates every table, so pointing it at a working database destroys the data in it. The unit side is conventional, using node:test across the server, the workers and the frontend library:
npm test                  # unit tests (node:test) for server + workers + frontend lib
npm run typecheck && npm run server:typecheck
npm run guard:big-brain   # CI guard: only agent turns may use the big model
The guard scripts are four named rules rather than one lint pass: big-brain usage is restricted to agent turns, every LLM call must be tracked, the engine registry is checked, and migration locks are checked. Linting is Biome, and CONTRIBUTING.md is said to list the full set of gates CI runs.
Local setup wants two databases, two ports and one key
Running this on your own machine is not a single command, because two services and one credential are required. You need Postgres and Redis, and the readme notes Homebrew services are fine. The setup is:
createdb -h localhost cumora
export OPENAI_API_KEY=sk-...

npm run setup          # install root + Email Worker dependencies
npm run dev:all       # Vite renderer on :5180 + API server on :5181
The renderer lands on port 5180 and the API on 5181, and the setup script installs three dependency trees, the root plus each of the two Cloudflare Workers. OPENAI_API_KEY is the only hard-required variable; everything else has a local default, including the Postgres and Redis URLs. An empty database is seeded with a starter team of six agents, three humans and nine conversations, and deliberately zero messages, so anything that appears in a conversation is produced live rather than replayed from fixtures. Node 20 or newer is required, and migrations run automatically on both dev paths.
One renderer, five shells, and an Android build nobody publishes
The src directory is described as pure UI: React 18 with Vite, TypeScript and Tailwind, wrapped by desktop, mobile, web and admin shells over the same components. Everything else is a shell around it. The electron directory is the desktop shell and takes its updates from the separate releases repository. ios and android are Capacitor shells sharing the identifier io.cumora.app, and the mobile situation is asymmetric: iOS is a TestFlight beta you join after installing Apple's app, while Android is not published at all and the instruction is to build it from the android directory yourself. Alongside those sit workers with two Cloudflare Workers, one for inbound mail and one for signed CDN delivery, a Go FUSE driver that mounts the agent workspace inside cloud pods, a benchmarks directory of real-model coordination tests, and a long row of one-off generator scripts at the root. Both .env.example and .env.production are committed, which is worth noticing when the template tells you to copy the example into a gitignored file.
Editorial conclusion
Cumora is worth reading if you are building the plumbing where several language models share one workspace, because it makes choices most demos skip: a durable command boundary in Postgres with Redis treated as disposable, an outbox you can drain from any number of replicas, and a triage tier that keeps cheap classification off the expensive model. Two decisions to settle before you adopt it. First the sandbox, since Claude Code and Codex are the only engines that run fail-closed by default and every other engine needs an explicit unsandboxed opt-in, so the safe configuration is narrower than the advertised engine list. Second the version, because the manifest sits at 0.18.7 while the newest tag is 0.9.0 and desktop users auto-update from a separate repository, so pin deliberately. And run the integration suite against a throwaway database, since it truncates every table and reports success when it skipped.
Frequently asked questions
What is Cumora?
It is a cross-platform team chat where AI agents are first-class participants: the same roster, the same direct messages, the same group conversations, the same Kanban board and calendar as the humans. Agents run either in a managed per-agent pod on Cumora's cloud or on your own machine, and both paths act on the world through the same cumora CLI protocol. The project is MIT-licensed TypeScript requiring Node 20 or newer.
How do I run Cumora on my own machine?
You need Postgres and Redis running locally, and one environment variable: OPENAI_API_KEY. The setup installs the root dependencies plus both Cloudflare Worker dependency trees, and dev:all starts the Vite renderer on port 5180 with the API server on 5181. Migrations run automatically on that path, and an empty database is seeded with six agents, three humans, nine conversations and no messages.
Does Cumora need my OpenAI API key?
For the cloud path, yes: OPENAI_API_KEY is the only hard-required variable, and cloud agents run a multi-hop tool-calling loop on the OpenAI Responses API with tools for shell, files, browser, email, memory and skills. On the bring-your-own-agent path the key is the one you already have, and the server never sees your provider keys. Every model call, cloud or BYOA, is recorded in a single llm_calls cost ledger.
What does Cumorah mean in Hebrew?
That question is about a different word. Cumora is a team chat product for AI agents, and nothing in the repository defines a Hebrew term or uses that spelling. Searching the bare name mostly returns an overnight mask, a skincare ingredient and a price query rather than this project.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yetone-cumora)Star history chart for your README
[](https://hysenlabs.com/projects/yetone-cumora)Was this useful?