PERT: the pretrained model whose own paper figures were wrong
PERT: Pre-training BERT with Permuted Language Model
At a glance
- What is it?
- PERT replaces BERT's masked-token objective with a permutation objective, shuffling the input and asking the model to say where each token came from, and what this repository publishes is a set of weights and figures rather than a training project.
- Who is it for?
- PERT fits someone who needs a Chinese or English encoder to drop into an existing BERT pipeline and who wants a training objective that never showed the model a [MASK] token. It fits badly if you need the recipe, because the repository ships weights, a licence and a folder of figures but no pretraining code, no data pipeline, and nothing beyond a corpus name for the training data.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
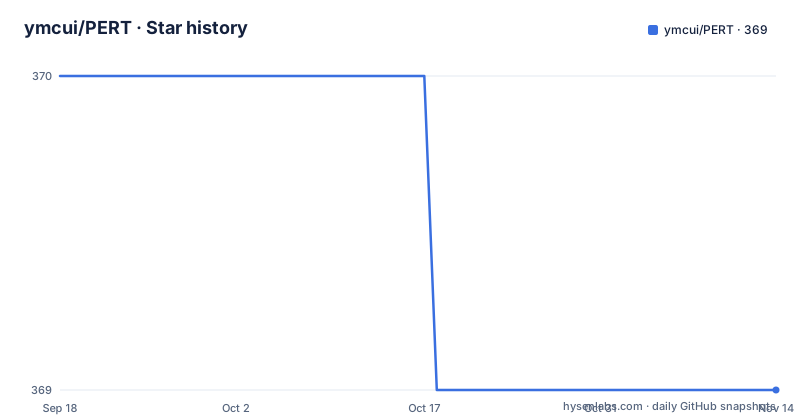
- ymcui/PERT369 ★ · -1
| Repository | 2026-09-18 | 2026-11-14 |
|---|---|---|
| ymcui/PERT | 370 | 369 |
-1 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The target is where a token came from, not what it was
The idea is a substitution for the masked language modelling objective, and it rests on an observation about reading: a certain degree of scrambled word order does not stop a sentence being understood, so semantic knowledge might be learnable from scrambled text. BERT hides tokens behind [MASK] markers and asks what belongs in each gap, which means the model never sees those tokens in context. PERT instead permutes tokens in place, so the input text stays complete and no extra marker is introduced, and the learning target becomes the original position of each token. The worked example in the README makes the contrast concrete. After WordPiece tokenisation, BERT masks three positions and is trained to map each masked slot back to the token that belonged there, positions 7, 10 and 13. PERT takes the same sentence, swaps two adjacent pairs, and is trained to predict the mapping: position 2 belongs at 3, position 3 belongs at 2, position 13 belongs at 14, and position 14 belongs at 13.
The README tells you to distrust the paper's own figures
There is a warning attached to the architecture diagram. The text says that the figures currently in the arXiv technical report are incorrect, that the diagram in the README should be used instead, and that the paper's images will be replaced when the paper is next updated. That is a rare admission to find in a research release, and it has a practical consequence for anyone reading the two documents side by side: the repository is the authority on the input and output format, and the paper is the authority on the results. The same section is careful about which structure it is describing, noting that what follows is the basic structure and input and output format for the pretraining stage rather than for fine-tuning, which is the stage most people actually care about.
Only the Transformer weights are released, not a recipe
The distribution is narrower than the name suggests. The note attached to the download table says the open-source release contains only the weights for the Transformer part, intended for two uses: fine-tuning on a downstream task, or serving as the initial weights for a second round of pre-training on your own data. Nothing about how those weights were produced is in the repository. There is no training script, no data preparation code, no tokenizer training, and no configuration beyond a corpus label in the download table. The top level holds a `.github/` directory, `.gitignore`, a LICENSE, the two READMEs, and a `pics/` directory, which is where the figures referenced by the documentation live. For a fine-tuning use case that is everything you need, since the weights drop into an existing BERT-shaped pipeline.
Two sizes, two corpora, and the original downloads behind passwords
Two model sizes are released, and the shapes are given exactly: PERT-large is 24 layers, 1024 hidden, 16 heads and 330M parameters, and PERT-base is 12 layers, 768 hidden, 12 heads and 110M parameters. The four original releases pair those sizes with two corpora. The Chinese models were trained on what the documentation calls the EXT data, described as Chinese Wikipedia plus other encyclopedias, news and question and answer material, totalling 5.4B tokens and about 20 GB on disk, and noted as the same data used for MacBERT. The English models, both uncased, used Wikipedia plus BookCorpus under the name WikiBooks. The original download links are TensorFlow 1.15 weights hosted on a Chinese file-sharing service, and each of the four links carries its own extraction password. TensorFlow 2 and PyTorch versions are a separate set on the Hugging Face hub, listed at 1.2 GB for the large models and 0.4 GB for the base ones.
The archive holds pert_config.json while the prose says bert_config.json
Unpacking the Chinese base archive produces a standard TensorFlow checkpoint triplet, pert_model.ckpt, pert_model.meta and pert_model.index, alongside a configuration file and a vocabulary. The configuration file is listed in that directory listing as `pert_config.json`, while the sentence immediately after it refers to `bert_config.json` as being identical to the Google original. Which name a loader expects is worth checking against the actual archive rather than the prose. The other half of that sentence is the compatibility claim: the vocabulary file is stated to be exactly the same as Google's, identical to the original Chinese BERT-base for the Chinese models and to the uncased version for the English ones. That is why a stock BERT tokenizer is enough, and it is also the constraint that keeps the permutation objective from being applied to a new vocabulary.
There is no PERT class, so the model loads as a BertModel
Because the body of the network is still BERT, the loading path is the ordinary transformers one, and the documentation is explicit that all models in the directory are loaded with the BERT tokenizer and BERT model, with the reading comprehension variants using the question answering class instead:
from transformers import BertTokenizer, BertModel

tokenizer = BertTokenizer.from_pretrained("MODEL_NAME")
model = BertModel.from_pretrained("MODEL_NAME")
The model identifiers are all under the hfl organisation on the hub, with Chinese and English variants in base and large sizes plus two MRC variants for reading comprehension, chinese-pert-large, chinese-pert-base, chinese-pert-large-mrc, chinese-pert-base-mrc, english-pert-large and english-pert-base. Nothing in the loading path is PERT-specific, which is convenient for a fine-tuning script you already have and means there is no code in this repository that reproduces the pretraining behaviour.
The authors report gains on some tasks and worse numbers on others
The framing in the introduction is unusually hedged for a model release, and worth reading before adopting the weights. It says PERT achieves performance gains on some Chinese and English natural language understanding tasks while doing worse on some tasks, and advises weighing that when choosing to use it. The baseline section then lists only a selection of experimental results, pointing to the paper for the full tables and analysis, with a convention that the number outside parentheses is the maximum and the number inside is the average. The Chinese evaluation covers ten tasks. Two are extractive reading comprehension, CMRC 2018 for simplified Chinese and DRCD for traditional Chinese. Six are text classification, split into two single-sentence tasks, ChnSentiCorp and TNEWS, and four sentence-pair tasks beginning with XNLI. The remainder of the list is past the point where the visible text stops.
A model release that grew sideways into a family of projects
The news section is a dated log and it explains why the repository feels quiet. It opens with thanks for attention on 17 February 2022 and an expectation that models would follow the next week, records the Chinese and English base and large releases on 24 February, the technical report on 15 March, an update on 7 May shipping a reading-comprehension-tuned PERT for several comprehension datasets together with a Hugging Face demo, and then stops being about PERT: LERT on 29 October 2022, described as a pretraining model fusing linguistic information, and Chinese LLaMA and Alpaca on 28 March 2023. The same page links the wider output of the lab, including MacBERT, Chinese ELECTRA, Chinese XLNet, Chinese BERT with whole word masking, the TextBrewer distillation tool and the TextPruner pruning tool. For this repository the practical answer to is it alive is the push date: 19 April 2026, with no releases ever tagged.
Editorial conclusion
PERT fits someone who needs a Chinese or English encoder to drop into an existing BERT pipeline and who wants a training objective that never showed the model a [MASK] token. It fits badly if you need the recipe, because the repository ships weights, a licence and a folder of figures but no pretraining code, no data pipeline, and nothing beyond a corpus name for the training data. Two things to check before committing. The authors state that PERT gains on some Chinese and English NLU tasks and performs worse on others, and advise judging case by case, so the published tables are a sample of ten Chinese tasks rather than a ranking. And the README says the figures in the arXiv technical report are erroneous and that its own diagrams are the correct ones, which is an unusual thing to have to check in a paper-backed release. On the mechanical side, the models load through BertTokenizer and BertModel, the open-source release contains only the Transformer weights, and the original downloads are TensorFlow 1.15 checkpoints. Apache-2.0 licensed, no tagged releases, branch last pushed on 19 April 2026.
Frequently asked questions
What is PERT in this repository?
A pre-trained language model that shuffles the word order of its input and trains the network to predict where each token originally sat, which means the input never needs a [MASK] token. The weights are published for Chinese and English in base and large sizes.
How does PERT differ from BERT's masked language modelling?
BERT replaces some tokens with [MASK] and predicts which position each one came from. PERT permutes tokens in place, so the text stays complete, and the target is the permutation itself, mapping each current position back to its original position. The stated inspiration is that a degree of word order scrambling does not prevent comprehension.
What can I download from the PERT repository?
Only the weights for the Transformer part, for downstream fine-tuning or as the starting point for further pre-training. Chinese-PERT-large is 24 layers, 1024 hidden, 16 heads and 330M parameters, while PERT-base is 12 layers, 768 hidden, 12 heads and 110M parameters. The original links are TensorFlow 1.15 weights, with TensorFlow 2 and PyTorch versions on the Hugging Face hub.
How do I load a PERT model with transformers?
With BertTokenizer and BertModel, since the network body is still a BERT structure. The documentation notes that all models in the directory are loaded that way, and that the MRC variants use BertForQuestionAnswering instead. The hub identifiers all live under the hfl organisation.
What corpora were the PERT models trained on?
The Chinese models used the EXT data, described as Chinese Wikipedia plus other encyclopedias, news and question and answer material, totalling 5.4B tokens and about 20 GB on disk, which the documentation notes is the same data as MacBERT. The English models used Wikipedia plus BookCorpus.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ymcui-pert)Star history chart for your README
[](https://hysenlabs.com/projects/ymcui-pert)Was this useful?