Scio's coverage badge points at a branch it no longer uses and its Maven badge still advertises Scala 2.12
A Scala API for Apache Beam and Google Cloud Dataflow.
At a glance
- What is it?
- spotify/scio is a Scala API for a batch and streaming framework, shipped as seventeen add-on artifacts with a REPL, type safe BigQuery and integration with a managed service. The repository's coverage badge targets a branch name it has moved away from, its Maven badge advertises the oldest cross-built artifact, two directories in the tree are absent from the published artifact list, two artifacts carry asterisk markers with no legend, and the page still links an incubator address for the framework it wraps.
- Who is it for?
- Use scio if you want a Scala surface over a batch and streaming framework you can run on a managed service, because the value is in the shape of the API and the add-on artifacts rather than in anything the underlying framework does not already do. Three things to know.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
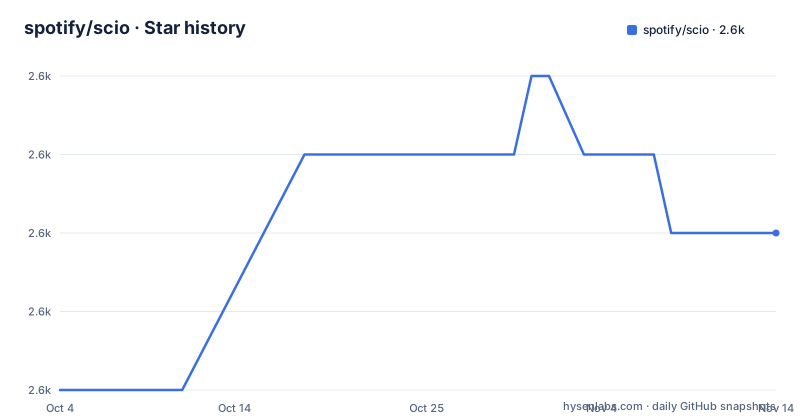
- spotify/scio2,630 ★ · +2
| Repository | 2026-10-04 | 2026-11-14 |
|---|---|---|
| spotify/scio | 2.6k | 2.6k |
2 Stars in the last 41 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The coverage badge points at a branch the repository no longer uses
The badge at the top of the page is a coverage report generated for a branch named master. The repository's default branch is main. The coverage service is therefore reporting on a branch that either no longer exists or no longer receives changes, which means the number the badge shows is measuring a tree that is not the one you are reading. This is the sort of defect that survives for years because nothing breaks: the badge still renders, the badge is still green or red, and nobody checks which branch it was generated from. The rest of the badge row is healthier. The build status badge is wired to the default branch, the licence badge points at the licence file in the repository, and the API badge points at the documentation site rather than at a stale local file.
The Maven badge still advertises the oldest cross build
The artifact badge points at the core library built for Scala 2.12, which is the oldest cross-built line a library like this would carry and is several major Scala versions behind current. Everything else the page says about the project is current, including the floor for the build toolchain and the list of add-ons, so the badge is the only place a version statement appears and it is the least current one on the page. Two implications follow. A reader cannot use it to decide which Scala version the project supports today, and a build that resolves against the version the badge names is several years old. The repository does carry configuration for automated dependency upgrades through a version steward, which is the mechanism that keeps the cross-builds moving, so the information is not missing from the project, only from the badge.
Benchmarks and a macro module are in the tree and not in the artifact list
The artifacts section enumerates what the project publishes: a core library, a REPL extension, an extras module, and add-ons for Avro, Cassandra, Elasticsearch, gRPC, JDBC, a graph database, Parquet, Redis, Snowflake, TensorFlow records, managed transforms, sort merge bucket operations, Google Cloud storage systems, and a three part test library. The repository root has two more library directories that this list does not mention: a macro module and a directory whose name is the abbreviation for a Java benchmarking harness. So the tree is larger than the published surface, which is normal, and it means a directory in the repository is not evidence that a dependency on it will resolve. The benchmark directory is the more interesting omission, because a project that measures itself usually says so somewhere, and here the only trace is the directory name.
Two artifacts carry asterisks with no legend
Two entries in the artifact list end in an asterisk: the Cassandra add-on and the Elasticsearch add-on. Nothing on the page explains what the asterisk means. There is no footnote below the list, and the two entries are otherwise described in the same one-line style as the rest, which suggests the marker used to point at something that has since been deleted, most likely a support status note like the best effort caveat that the extras module carries in prose. It is a small blemish, and it is worth more attention than it looks: a reader looking for whether the Cassandra add-on is production ready will find a marker that promises an answer and delivers nothing, and will probably ask in the issue tracker instead.
The quick start is a generated project and a staged word count
The quick start is unusually concrete for a framework page, and it works because it never explains the API. You install a build tool and a JDK, generate a new project from a template the project maintains for exactly this purpose, and build it. The build produces a runnable script under a staging directory, and the generated project contains one example job: a word count that takes an output path. Then the page tells you to list the output files and read one of them, and it even names the exact filename it expects, which tells you the example splits its output across four part files. That is a better teaching sequence than a feature list, and it also means a reader can evaluate the whole toolchain in about ten minutes before deciding whether to read anything else. The two commands that do the work are short enough to memorise:
cd scio-job
sbt stage
then the staged script is run with an output path, and the files it wrote are listed and read back.
A software catalogue descriptor sits in the public root
Among the root files is a catalogue descriptor, the kind of small YAML file an internal software catalogue reads to register a component: who owns it, what it is, where its documentation lives. Its presence tells you the project is registered in a company catalogue, and it is the kind of file that usually carries metadata of no use outside the company, listing lifecycle stages and owning teams. It is also harmless and occasionally useful, since the ownership field is a more honest answer to who maintains this than a readme badge is. The rest of the root is tooling a Scala project of this size would have anyway: a build definition, a project directory for plugins, formatter and linter configuration, an options file for the build tool, a script directory, a documentation site directory, and a file listing commits to hide from blame annotations.
Two links point at an incubator address and a retired SDK
The framework this project wraps is linked through its old incubator address, which is where that project lived before it graduated and where the canonical address now redirects. The managed service it integrates with is linked through the separate Java SDK repository rather than through the framework itself, which is the path that was current before the managed service moved its runners onto the open framework. Both links work and both are the wrong door. Nothing about them is broken in a way a reader would notice immediately, which is precisely the problem: the page reads as current because every link resolves, and a reader who follows the SDK link lands in a repository whose status the page never mentions.
Editorial conclusion
Use scio if you want a Scala surface over a batch and streaming framework you can run on a managed service, because the value is in the shape of the API and the add-on artifacts rather than in anything the underlying framework does not already do. Three things to know. The published cross-builds are the thing to check, since the only version statement on the page is a badge pointing at the oldest artifact line. The repository contains modules that are not published, so a directory in the tree does not tell you what you can depend on. And a couple of the page's links have rotted, which is a small thing individually and a sign that the documentation site, not the readme, is where current instructions live.
Frequently asked questions
What is Scio?
A Scala API for Apache Beam and Google Cloud Dataflow, inspired by Spark and Scalding, with a unified batch and streaming model, a REPL extension, type safe BigQuery, orchestration through futures, a distributed cache and integration with a managed service.
Is the Spotify code open source?
Partly, and this framework is the part that is. It is published under the Apache 2.0 licence with a copyright line naming the company, and the page links its own documentation, API reference, examples and a separate repository of data processing snippets.
How do I start a Scio job?
Install a JDK of version 11 or newer and the build tool, generate a project from the template the project maintains, then build it. The generated job contains a word count example, and the page shows how to list its output files and read one of them.
Which Scala version does Scio publish for?
The Maven Central badge on the page points at the core artifact built for Scala 2.12, which is the only version statement the page makes. The repository does use automated dependency upgrades, so the cross-built lines are newer than the badge suggests.
What add-on artifacts does Scio publish?
Seventeen, including Avro, Cassandra, Elasticsearch, gRPC, JDBC, Neo4j, Parquet, Redis, Snowflake, TensorFlow records, managed transforms with Iceberg, sort merge bucket operations, Google Cloud storage systems, a REPL extension, an extras module and a three part test library.
What is in the Scio repository besides the published artifacts?
A benchmarking directory, a macro module, integration tests, the documentation site, linter configuration, deployment scripts and a software catalogue descriptor for an internal catalogue. None of those directories appears in the published artifact list.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spotify-scio)Star history chart for your README
[](https://hysenlabs.com/projects/spotify-scio)Was this useful?