grepai: local semantic search that needs an embedding provider first
Semantic Search & Call Graphs for AI Agents (100% Local)
At a glance
- What is it?
- A Go CLI that indexes a repository as vectors so an agent can ask for authentication logic instead of a regex, traces callers, and exposes itself over MCP. It calls itself 100% local, which is true of your code and conditional on the embedding runtime you supply, and a local make build stamps the binary as version 0.1.0 while the releases are at v0.37.0.
- Who is it for?
- grepai suits a developer whose agent is burning tokens re-reading a repository and who already has a local embedding model, since the index is only as good as the embedding provider you point it at. Check four things first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
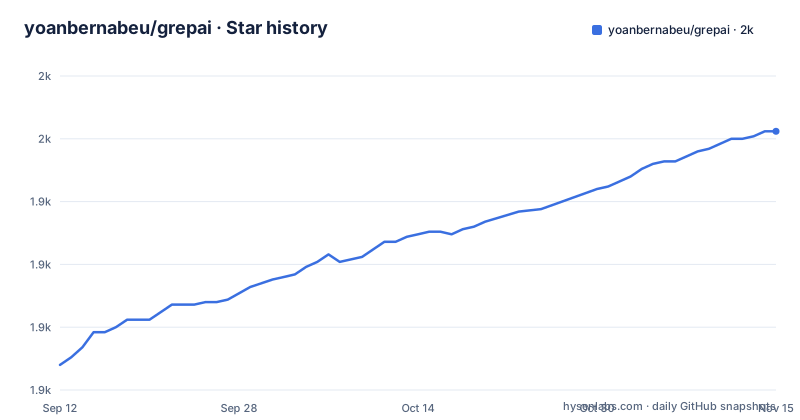
- yoanbernabeu/grepai1,953 ★ · +93
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| yoanbernabeu/grepai | 1.9k | 2k |
93 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Local means you supply the embedding runtime
The feature list says one hundred percent local and your code never leaves your machine. The requirement line underneath the install commands qualifies that: an embedding provider is required, and the three named are Ollama, which is the default, LM Studio, and OpenAI. The recommended first step is pulling one model:
ollama pull nomic-embed-textSo the privacy claim holds for your source, and the embedding request still goes wherever the provider lives. If you pick OpenAI, the vectors are computed remotely, and only your code is local.
The compose file makes the local path more awkward than the feature list implies. Its Ollama service is commented out, described as optional and marked Linux only, with a block of NVIDIA GPU reservation notes to uncomment alongside it. There is no Windows recipe in that file at all, and the README offers a PowerShell installer for the CLI without saying what provides embeddings there.
That is the first thing to sort out, because an index of vectors with no embedding model is an empty index.
A local build stamps itself as version 0.1.0
The build file starts like this:
BINARY_NAME=grepai
VERSION?=0.1.0
BUILD_DIR=bin
LDFLAGS=-ldflags "-s -w -X main.version=$(VERSION)"
The question mark on `VERSION` means it is only a default. If you do not pass VERSION on the command line, the version string compiled into the binary is 0.1.0, and it is written into `main.version` at link time.
The releases are at v0.37.0, published 2026-09-10, with v0.36.1 on 2026-09-01 and v0.36.0 on 2026-08-30. The last commit to the repository is 2026-09-21 and it is not archived.
So a developer who builds from source and a user who installs the released binary can report completely different versions, and the number in the source tree is the one that looks wrong. Anyone filing an issue about a local build needs to say how they set VERSION, or the report starts with a version that matches nothing upstream.
The rest of the build file is careful in the same way. The linker flags strip the symbol table and dead code, and the version is the only variable injected.
Two vector stores, two profiles, and one default password
Both a Postgres vector extension and Qdrant are in the main require block of the module, not behind a build tag, so the store is a choice made at configuration time rather than at compile time.
The compose file ships both as optional services, each behind a profile. Postgres uses the pgvector image for version 16, creates a database, user and password all set to `grepai`, publishes 5432 to the host, keeps its data in a named volume, and has a healthcheck running `pg_isready` every five seconds with five retries. Qdrant publishes 6333 for the HTTP API and dashboard and 6334 for gRPC, and its data goes to a bind mount in the working directory rather than a named volume.
That bind mount is the detail to notice. Postgres data survives a `docker compose down` because it lives in a named volume, while the Qdrant directory is just a folder next to the compose file, which means the two backends do not have the same durability story.
The default credentials are also in the file, in plain text, with the port published to the host. That is normal for a development compose file and worth treating as development only if you run one.
Everything in this file is behind a profile, which means nothing starts unless you name it.
The language metadata says C, the module says Go 1.25.5
The repository reports its primary language as C, which does not match anything else about it. The module file declares Go 1.25.5, the build file compiles with `go build`, and the root holds a golangci-lint configuration and a goreleaser configuration, both Go tools. There is a Nix flake and a lock file, and a `rpg/` directory that is not a Go package name you would choose by accident.
The dependency list explains what the tool is made of. `spf13/cobra` is the command line surface. The charm libraries, bubbletea, bubbles and lipgloss, plus a TUI helper, are the interactive parts. `fsnotify` is the file watcher behind the always up to date claim. `smacker/go-tree-sitter` is a parser binding, so indexing reads syntax rather than lines. `mark3labs/mcp-go` is the MCP server, and `google.golang.org/grpc` comes with it.
Storage is `jackc/pgx/v5` for Postgres and `pgvector-go` and the Qdrant client for the vectors. `sabhiram/go-gitignore` decides what not to index, which is the sort of dependency that quietly determines whether your search results are about code or about build output.
There is also an `fsharp/` directory, an `updater/`, a `daemon/` and a `framework/`, none of which the front page mentions.
Four commands, a daemon, and an MCP server
The quick start is four lines, and the third one is the product:
grepai init                        # Initialize in your project
grepai watch                       # Start indexing daemon
grepai search "error handling"     # Search semantically
grepai trace callers "Login"       # Find who calls a function
`init` writes the project configuration, `watch` starts the indexing daemon and keeps the index fresh as files change, `search` takes a phrase, and `trace callers` answers the question you have before editing something.
The feature list gives the intended payoff in its own example: ask for authentication logic and find `handleUserSession`, that is, find code by intent when the naming does not match your words. The comparison table puts the same point as grep and ripgrep matching patterns against grepai matching conceptually related code.
Two integration surfaces are named. It works with Claude Code, Cursor and Windsurf out of the box, and it can be called directly as a tool through its MCP server. The documentation site covers configuration, agent setup and MCP wiring, which is where the actual agent integration instructions live rather than on the page.
Shell completion is unusually thorough, covering commands, flags and dynamic values such as workspace names, project names, providers and backends, with recipes for zsh including an oh-my-zsh plugin, bash, fish and PowerShell.
Lint runs in Docker, and the docs build needs Node
The contributor surface has a shape that is easy to miss from the front page. The lint target does not call a local linter:
docker run --rm -v $(PWD):/app -w /app golangci/golangci-lint:v2.13.2 golangci-lint run ./...It runs the linter in a pinned container. A second target, `lint-local`, calls a locally installed binary instead, so there are two lint paths with different prerequisites and the documentation does not say which is expected.
The test target runs with the race detector, and a coverage target produces a profile and an HTML report. The pre-commit target chains formatting, `go vet`, the containerised lint and the race tests, and its closing message is cut off after a checkmark and the word All, so the last thing a passing run prints is not in the file.
Documentation has its own chain. A generator written in Go produces the command reference, then the docs build moves into a directory and runs an npm install before building, and a development variant runs npm install and a dev server. So building the docs needs Go and Node, and the generated command reference is a build artefact rather than a checked in file.
Cross compilation is defined for five targets, which is where the gaps show: Linux and macOS on amd64 and arm64, and Windows on amd64 only.
The token saving claim rests on forum posts
The headline claim is that grepai drastically reduces AI agent input tokens by giving relevant context instead of raw search results. The evidence offered for it is a block of testimonials.
The most substantive is a Reddit comment on a Claude community thread, from a user saying they had just hit their limit and that it took thirteen percent of a max 5 plan just to read their own codebase. That post is credited with more than 280 thousand views. The other two are one line each: one post on X saying it works great and takes five minutes to install, and one on LinkedIn saying the results are incredible.
So the number that supports the headline is one person's bill on one repository, not a measurement, and the page does not publish a benchmark of its own. The documentation site has a blog section that includes benchmarks, which is where a controlled comparison would live if one exists.
The other claim on the page is the one that is easy to verify: your code stays on your machine, which holds as long as the embedding provider is a local one. The two halves of the pitch have very different levels of evidence behind them, and it is worth keeping that straight when deciding whether to install it.
Editorial conclusion
grepai suits a developer whose agent is burning tokens re-reading a repository and who already has a local embedding model, since the index is only as good as the embedding provider you point it at. Check four things first. Which provider you will run, because the default is Ollama and the Windows path has no container recipe for it in the compose file. Whether Postgres or Qdrant will hold your vectors, since both are wired in and both publish host ports. That the version your binary reports means something, given the mismatch between the build default and the tags. And whether the token saving claims, which come from forum posts rather than a published benchmark, matter to you enough to test them on your own repository.
Frequently asked questions
What does grepai need before it can index a repository?
An embedding provider: Ollama, which is the default, LM Studio, or OpenAI. The recommended model is nomic-embed-text, pulled with ollama pull. Without a provider the index has no vectors, and the local compose file only offers a commented out Ollama service marked as Linux only.
Which commands does the grepai CLI have?
grepai init to set up a project, grepai watch to run the indexing daemon, grepai search with a phrase to search semantically, and grepai trace callers with a function name to find its callers. The feature list also names an MCP server so an agent can call it as a tool.
Where does grepai keep its vectors, Postgres or Qdrant?
Either, both are wired in as direct dependencies and both appear in the compose file behind profiles. The Postgres service uses pgvector on Postgres 16 with a named volume, while Qdrant stores into a bind mount in the working directory, so the two backends do not have the same durability story.
Does grepai send my code to an external service?
Your code is indexed locally and the project states that it never leaves your machine. The embedding request is separate, though: with the default Ollama provider it is local, while selecting OpenAI sends the embedded content to that endpoint.
What version does a local grepai build report?
0.1.0 by default, because the build file sets VERSION to 0.1.0 when it is not passed on the command line and injects it into main.version at link time. The published releases are at v0.37.0, so a locally built binary reports a version that matches nothing upstream.
How do I run the tests and linter for grepai?
The test target runs the race detector, and the lint target runs golangci-lint inside a container at a pinned tag, so linting needs Docker. A separate lint-local target uses a local binary, and the docs build runs a Go generator before an npm build in the docs directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yoanbernabeu-grepai)Star history chart for your README
[](https://hysenlabs.com/projects/yoanbernabeu-grepai)Was this useful?