hax is a coding agent in C whose subagents are resolved through PATH, not through a plugin runtime
A minimalist, terminal-native coding agent written in C.
At a glance
- What is it?
- A single native binary that runs on four Unix platforms, connects to seven provider families including local llama.cpp servers, keeps its sessions in plain text keyed to a directory, and documents its missing features as decisions rather than gaps. The build is meson behind a shell script behind a Makefile.
- Who is it for?
- hax is for a specific person: someone who already runs models on their own hardware, wants an agent that behaves like another Unix tool, and would rather read a transcript than configure a permission matrix. Its two real strengths are the transcript view and the wire trace, which together answer the question most agent tools defer, namely what exactly left the machine.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
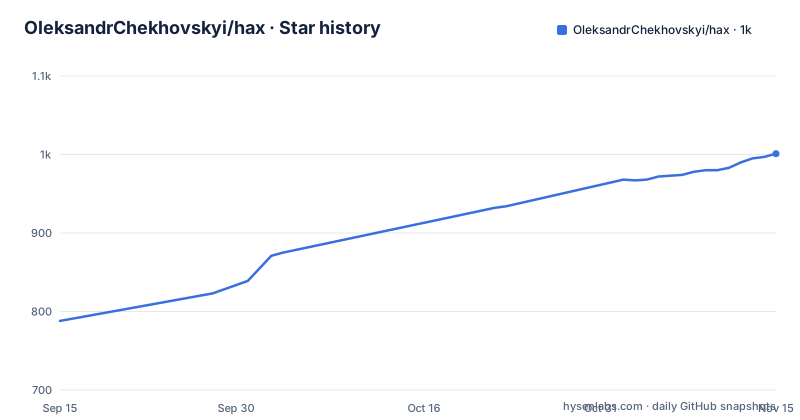
- OleksandrChekhovskyi/hax1,001 ★ · +213
| Repository | 2026-09-15 | 2026-11-15 |
|---|---|---|
| OleksandrChekhovskyi/hax | 788 | 1k |
213 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A meson build hidden behind one shell script behind a Makefile
The build system is layered three deep, and each layer exists for a reason.
At the bottom is meson, with a `meson.build` at the root and a `meson install -C $(BUILD_DIR)` behind the install target. Around it sits a shell script that every target delegates to, with the build directory passed in as an environment variable. The Makefile comment states the purpose without pretending otherwise: these are entry points for humans, for editors running a make command, and for coding agents, and the script exists to keep successful output compact and failure output focused on diagnostics.
That last clause is the interesting one. Most build wrappers are silent about why they exist. This one is explicitly trying to produce output that a machine can read as well as a person, which is a deliberate accommodation for the class of tool it is.
The development configuration matches that. A compilation database is committed, along with format and lint configuration files, so an editor or a static analyser can work from the repository without a setup step. Tests and lint are separate targets, and both need extra tools that the main build does not: the interactive test scenarios are driven by a terminal multiplexer, and linting needs both a formatter and a static analyser, each installable through the same dependency script with a named argument.
The dependency script itself covers nine platform families, from Debian and its derivatives through Fedora, Arch, openSUSE, Alpine, macOS and both BSDs.
Subagents are resolved through PATH, so two installs can diverge
The single most consequential design decision in this project is stated in a Makefile comment rather than in the feature list. The agent resolves its subagent invocations through PATH.
That is the whole of the composition model. Instead of a plugin runtime that loads extensions into its own process, hax composes by spawning subprocesses, which is why the feature list describes it as a well-behaved Unix tool that composes via subprocesses instead of plugins.
The consequence is a deployment hazard rather than a philosophical one. If a system package and a development build are both installed, a subagent call is dispatched to whichever `hax` appears first on PATH, and nothing in the parent process guarantees that is the copy the user believes they are running. Over a long agent run with nested calls, that is a real possibility for divergence.
The project knows this, and the build has a target for it. `make symlink` depends on the build, creates `~/.local/bin`, resolves the absolute path of the freshly built binary, and repoints the symlink at it on every rebuild, printing the resulting link. The comment explains why: development is nicest with the dev binary on PATH, and the symlink tracks every rebuild so it cannot go stale.
So the fix is documented and automated, but it is opt-in. A user who installs from a package manager and also builds from source has to run it, or has to notice the problem later.
Provider, model, effort and preset each live in three different places
Configuration is optional, and the interesting part is that there is no single place that decides which model answers.
Four things have to be chosen: the provider, the model, the effort level, and a preset. Each can be set in more than one place.
Interactive selections made in the running program are remembered separately from the configuration file. Command line flags apply only to the current run, so passing a model flag twice changes nothing persistent. Environment variables exist for shells and scripts. And a resumed conversation restores its own provider, model, effort and preset, unless a command line selection flag overrides them.
That last clause is the only override rule the front page states outright: a resumed session restores its own settings, and an explicit flag wins over them. Everything else, including how a remembered interactive selection interacts with the config file and with an environment variable, is delegated to a separate configuration document that covers the file format, the resolution order, presets and the full setting reference.
For a tool whose selling point is that it gets out of the way, this is the part most likely to surprise someone. A session resumed next week can answer with a different model than the one it was started with, and the only way to be certain is to look, which the transcript view makes possible.
Sessions belong to a directory rather than to you
Every session option in the quick start is scoped to a directory, and the very first instruction is to run the agent from the project directory you want it to work in.
That gives four entry points. Running it with no arguments opens an interactive session. The one-shot flag runs a single prompt and prints the final answer. Continuing with a short flag picks up the latest session for the current directory, and a longer resume flag lets you choose a past session for the same directory. A session identifier can be combined with one-shot mode to continue a specific conversation and get a single answer back.
hax                         # interactive REPL
hax -p "list TODOs"         # run one prompt and print the final answer
printf "explain x" | hax -p # read the prompt from stdin
hax -c                      # continue the latest session for this directory
hax --resume                # pick a past session for this directory
hax --resume=ID -p "next"   # resume a specific session in one-shot mode
Prompts can also arrive on standard input, so the agent drops into an existing pipeline without a shell wrapper.
The storage matches the Unix framing. Configuration and session files are plain text, paths follow the XDG convention, and in one-shot mode standard output stays clean with resume hints sent to standard error, which is what lets `hax -p` be captured by a script without post-processing.
A separate document covers the session file format and a JSON stream mode, and the debugging document covers trace and transcript logs, a mock provider and demo scripts, which is the combination you would use to see what a change does without spending a call.
The provider list in the feature bullet is shorter than the table
Two lists of providers exist and they do not match.
The feature bullet names OpenAI and compatible endpoints, Anthropic and compatible endpoints, Codex through a ChatGPT subscription, OpenRouter, the two OpenCode variants, llama.cpp, and custom endpoints. The setup table that follows adds a row that the bullet does not mention: a local Ollama server, started by running its serve command.
Reading the table as a whole is more useful than the bullet. Three of the seven rows need nothing but an environment variable set to the vendor's standard name, which means hax inherits whatever credentials your shell already has. One row, Codex, needs no key at all and instead asks you to run a login command inside the agent, which is the path that uses a ChatGPT subscription rather than an API account.
Two rows are local servers with no credentials involved: llama.cpp and Ollama. The llama.cpp row is the one the feature list goes furthest on. Start the server with a model file, then point hax at it with a provider flag, and the agent discovers the model and the runtime's capabilities by itself, with no provider configuration block required for the default setup. Given that the stated reason for the whole project being in C is to leave memory available for local models, that path being the path of least resistance is the design point.
Configuration for anything beyond these defaults lives in a separate providers document.
The missing features are documented as decisions, not as gaps
Most projects list what they have. This one spends a paragraph on what it will never have.
The stated audience is developers who live in the terminal, run local models, audit what their tools do, package software for distributions, or run agents where resources are scarce. Then it names four things other agents build and hax deliberately does not: a marketplace for tool servers, a plugin runtime, panels inside an editor, and per-command permission prompts.
Per-command approvals are the omission that matters most for a tool with shell access, so it is worth looking at what is offered in their place, and the answer is auditability rather than prevention. A transcript view on a single key shows exactly what was sent to the model and exactly what it replied. A detailed wire protocol trace can be collected on request. A mock provider exists so behaviour can be exercised without a real endpoint. A philosophy document is said to explain each omission and the pattern that covers the need.
The terminal behaviour is the other half of that argument, and it is specific. Streaming Markdown and live tool output are reflowed for display, and only the current streaming line or the input area is redrawn, so the terminal's own scrollback stays intact and a transcript that has scrolled past is still there. The stated guarantee is blunt: it does not take over or mess with your terminal.
That constraint shapes the code. A full-screen alternate-screen interface would have made several of the other omissions easier.
Four platforms, four install routes, and three releases in three weeks
Platform support is Linux, macOS, FreeBSD and OpenBSD, with Windows covered by running it under a Linux subsystem. The BSDs are source-only.
There are four ways in. A Homebrew cask covers macOS and Linux. The Arch repository carries it under a short package name. On any Linux distribution you can download a prebuilt static binary for your architecture, either x86_64 or aarch64, and unpack it into any directory already on your path. Or you build from source, which the document is explicit about producing a different artefact: a binary linked against your system's shared libraries instead of a static one.
The source route runs three commands. Clone, run the dependency script, then make, and the binary lands in a build directory. Installation afterwards goes through meson and may prompt for a superuser password.
The dependency script installs a compiler, an HTTP client library, a JSON parser, meson, ninja, and pkg-config, plus a fuzzy finder used for file completion when it is present. On platforms the script does not cover, the same list has to be installed by hand before make will work.
Version history is recent and fast: 0.3.0 on 2026-08-12, 0.4.0 on 2026-08-22, and 0.5.0 on 2026-09-04. The default branch was pushed on 2026-09-29, so the tree is about three weeks ahead of the newest tag, and the changelog is at the root next to two agent instruction files.
Editorial conclusion
hax is for a specific person: someone who already runs models on their own hardware, wants an agent that behaves like another Unix tool, and would rather read a transcript than configure a permission matrix. Its two real strengths are the transcript view and the wire trace, which together answer the question most agent tools defer, namely what exactly left the machine. Its structural trade-off is that composition happens through subprocesses and PATH rather than through a plugin runtime, which is why the Makefile bothers to keep a development symlink current: an agent that shells out to its own name will call whichever copy is found first. If you need per-command approvals, an extension marketplace or a panel inside an editor, the project says plainly that it will not grow those and points at another tool. Check that the copy on your PATH is the one you built before you trust a long agent run to do what you think it is doing.
Frequently asked questions
What is hax and what is it written in?
A minimalist, terminal-native coding agent written in C, distributed as a single native binary with a small dependency set that starts immediately and uses only a few megabytes of memory. The stated reason for the memory profile is to leave as much as possible available for models running locally on the same machine.
How do I install hax?
On macOS or Linux with `brew install oleksandrchekhovskyi/hax/hax`, from the Arch repository as hax, or by downloading a prebuilt static binary for x86_64 or aarch64 from the latest release and unpacking it into a directory on your path. From source it needs a compiler, libcurl, jansson, meson, ninja and pkg-config, installed by scripts/install_deps.sh on nine platform families.
Which model providers does hax support?
OpenAI and compatible endpoints, Anthropic and compatible endpoints, Codex through a ChatGPT subscription, OpenRouter, the OpenCode Zen and Go variants, llama.cpp, Ollama, and custom endpoints. Three need only a vendor-standard environment variable, Codex uses a login command inside the agent, and the two local servers need no credentials at all.
Does hax use a local llama.cpp model without configuration?
Yes. Start the server with a model file, then run hax with the llama.cpp provider flag, and the agent discovers the model and the runtime capabilities itself. The document states that no provider configuration block is needed for the default setup.
Does hax ask for permission before running commands?
No, and that omission is deliberate. The document names per-command permission prompts, a plugin runtime, an editor panel and a tool marketplace as things other agents build and hax chooses not to, and points to a philosophy document explaining each. In their place it offers a transcript view on a key that shows exactly what was sent and replied, an optional wire protocol trace, and a mock provider for testing without a real endpoint.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oleksandrchekhovskyi-hax)Star history chart for your README
[](https://hysenlabs.com/projects/oleksandrchekhovskyi-hax)Was this useful?