The repository description says 900 skills in four layers, the README says 271 in two
900+ pure-markdown skills for autonomous AI research, organized as 9 freely-composable packages over a 4-layer hierarchy (Campaign → Strategy → Tactic → SOP). Non-linear orchestration with backtracking, 6 MCP integrations. The AI is the researcher — you set the direction.
At a glance
- What is it?
- DARE is a graph of markdown skill files that an agent reads off disk, with no runtime and no build step. Its own front page, its package manifest and its latest release tell three different stories about how big it is, and the faster entry point deliberately gives up the approval gate and resumability.
- Who is it for?
- The design decisions here are worth reading even if you never install it, because the five-part node contract and the rule that completion is a condition rather than a step count are transferable to any agent workflow you build. Two things to know before you use it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 23 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
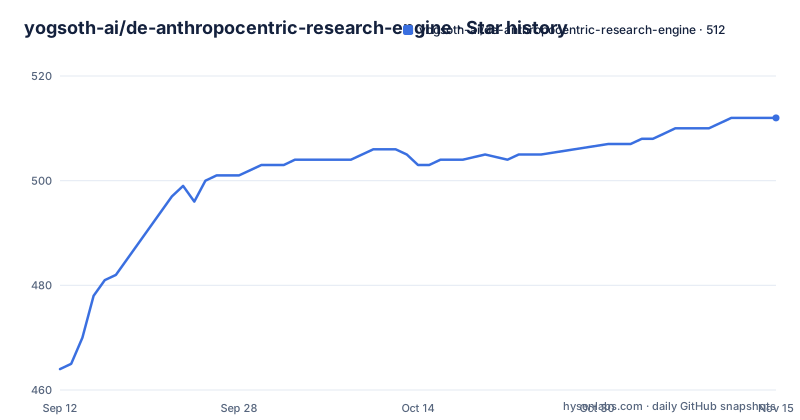
- yogsoth-ai/de-anthropocentric-research-engine512 ★ · +48
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| yogsoth-ai/de-anthropocentric-research-engine | 464 | 512 |
48 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three different sizes for the same project
The repository description advertises more than nine hundred pure markdown skills, organised as nine composable packages over a four-layer hierarchy running from campaign down to standard operating procedure. The README describes something smaller and flatter: a research skill graph for AI-native science made of 271 markdown files with no runtime, no dependencies and no build step, laid out as one flat directory with two layers. The package manifest agrees with the README and calls it a 267-node graph. The two numbers in the README reconcile cleanly on their own, with 267 graph nodes made of 51 tactics and 216 procedures, plus four product shells that run the session rather than the science, which adds up to the 271 files. The release that introduced the current design is titled after the two-layer graph, which is the clearest sign that the description is left over from an earlier structure.
Four shells run the session, 267 nodes do the science
The architecture is deliberately thin at the top. Four shells, named for what they do, run a session: an entry point, a catalog, a spec writer and a spec executor. Everything else in the directory is a graph node, and the distinction the project insists on is that a shell is not a third scientific layer and holds no research contract, while a graph node never manages the session. Below the shells sit the two layers. A tactic is a complete research transformation that owns its thresholds and its gates and knows which procedures it needs, with the named examples including synthesising literature evidence, validating a research gap, formulating hypotheses, analogical discovery, structured red teaming, experiment design and causal model construction. A tactic may call procedures, which is what makes the graph rather than a tree, and that call structure is the reason partial installation fails.
Completion is a condition, never a step count
Every node in the graph carries the same five parts: an input contract, a procedure, an output contract, quality gates and a failure clause. The gates are described as the point of the whole design, because a node finishes when a stated condition is objectively satisfied rather than when its steps have been performed, and the text rules out three specific false completions, elapsed time, an empty result and an interruption. That is a real answer to a common failure in agent workflows, where a long turn that produced nothing is treated as finished. The failure clause is given equal weight: each node states what its output looks like when the work did not hold, with an abstraction gap, an unmet threshold and a counterexample as the named cases, so the caller receives a diagnosis instead of silence. Silence, in other words, is a bug in the contract rather than an acceptable outcome.
The fast entry point drops the gate and the checkpoint
There are two ways in and they are not equivalent. The guided entry takes a research direction in plain language, crystallises a North Star and a brief, drafts a staged spec for approval, and only then executes it phase by phase with append-only checkpoints, so nothing runs before you approve and an interrupted run resumes from the last complete checkpoint. The catalog entry skips all of that: no North Star, no spec, the agent reads the index of tactics, plans its own route and loads whatever fits, and the documentation suggests asking it to state which tactics it intends to use in what order before it starts. Tactics still run their own procedures and gates in this mode. What you lose is stated plainly, the approval step and the checkpoint log, which means the agent's plan is the only plan and an interrupted run does not resume. The README says to use the guided path by default.
Install the whole graph, because partial installs have no fallback
There is one install path and it is a single command that takes the wildcard skill selector:
npx skills add yogsoth-ai/de-anthropocentric-research-engine --skill '*'The instruction to install everything is not incidental. A partial install breaks the call edges, because a tactic that loads a procedure which is not there has no fallback path, so the graph degrades into broken nodes rather than a smaller working graph. You run it from your own project directory rather than from a clone of the repository, and there is nothing else to configure: no package install, no API keys and no configuration file for tool servers, because the library is a set of skill files that the agent reads off disk. The manifest at the repository root is marked private, which is consistent with that, since it describes the project for tooling and is never published to a registry.
Five rival systems named, none of them measured
The design section positions this project against a list of five named systems, described as fixed-pipeline research tools that execute stages in a predetermined order, with the claim that where they do backtrack, they retry the current step rather than returning from experiment design to literature review when the evidence base turns out to be insufficient. The argument is that a pipeline assumes research is predictable while an arsenal assumes it is not, so this project prescribes no order at all: the spec commits to a sequence and records the conditions under which that sequence is abandoned, and inside an approved plan the executing agent holds full routing authority. The reasoning is coherent. What is absent is any evidence: no benchmark, no comparison of outputs, no citation for the claim about how those five systems handle backtracking. Treat the positioning as a design opinion rather than a measured result.
No MCP configuration needed, and MCP servers still recommended
The install section states that nothing else needs configuring, naming no package install, no API keys and no configuration file for tool servers, which reads as a claim that the graph is self-contained. A later section of the same document recommends specific MCP servers, and the repository description counts six such integrations. Both statements can hold at once, since an agent that already has those tools connected would use them and an agent without them would simply run the graph without them, but the document does not say that explicitly. That gap matters for the claim that there is no runtime, because a skill that expects a search or document tool to exist will behave differently on a machine where it does not. The remaining root files are small and unremarkable: a licence, a security policy, an assets folder, a manifest for the skills registry and the skills directory itself.
Editorial conclusion
The design decisions here are worth reading even if you never install it, because the five-part node contract and the rule that completion is a condition rather than a step count are transferable to any agent workflow you build. Two things to know before you use it. The project's own metadata contradicts its documentation on size and structure, so take the counts in the current README rather than the ones you see in search results, and check that a claim about a rival system is something you can verify elsewhere. And if you want the fast entry point, understand what you are giving up: without the spec approval step there is no gate before execution, and without the checkpoint log an interrupted run starts over rather than resuming.
Frequently asked questions
What is the De-Anthropocentric Research Engine?
A research skill graph for AI-native science, made of 271 markdown skill files with no runtime, dependencies or build step, installed as an Agent Skills library. You give it a research direction, it turns that into a North Star, a brief and a staged research spec, then executes the spec against explicit completion gates.
How do I install DARE?
With one command that installs the whole graph using the wildcard skill selector, run from your own project directory rather than a clone of the repository. A partial install is not supported, because a tactic that loads a procedure which is missing has no fallback, and nothing else needs configuring: no package install, no API keys and no tool server configuration file.
What is the difference between the two DARE entry points?
The guided entry builds a North Star, a brief and a staged spec for your approval, then runs it phase by phase with append-only checkpoints, and an interrupted run resumes from the last complete one. The catalog entry has no spec and no approval step, the agent picks its own route through the tactic index, and an interrupted run does not resume.
Does DARE need API keys or MCP servers?
No configuration is required: the install section names no package install, no API keys and no tool server configuration file, because the agent reads the skill files from disk. Separate documentation also recommends particular MCP servers, so those integrations are optional rather than required, although the document does not say so in those terms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yogsoth-ai-de-anthropocentric-research-engine)Star history chart for your README
[](https://hysenlabs.com/projects/yogsoth-ai-de-anthropocentric-research-engine)Was this useful?