s3fs-fuse: mounting a bucket that rewrites itself on every append
FUSE-based file system backed by Amazon S3
At a glance
- What is it?
- s3fs-fuse exposes an S3 bucket through FUSE so ordinary file tools can read and write it while the objects stay in S3's native format. The POSIX surface is broad, but the cost model is not a local one, and the project is explicit about which operations rewrite a whole object, list over the network, or are never atomic.
- Who is it for?
- Use s3fs-fuse when one host needs POSIX-shaped reads and writes over a bucket it also touches with the AWS CLI, and accept that appends, renames, and recursive listings are network operations rather than local ones. Do not treat it as shared writable storage for several hosts, since there is no coordination between clients, inotify misses writes made elsewhere, and renames are not atomic.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
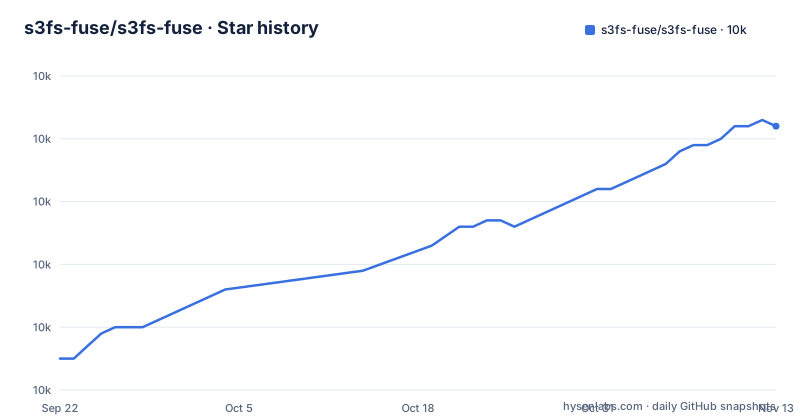
- s3fs-fuse/s3fs-fuse10,032 ★ · +37
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| s3fs-fuse/s3fs-fuse | 10k | 10k |
37 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Object bytes stay in S3's own format, and there are no hard links
s3fs does not translate objects into blocks or a private sidecar format. The bytes S3 stores are handed back through FUSE unchanged, which is why the AWS CLI keeps working against the same bucket while it is mounted. The POSIX coverage is described as a large subset: reading and writing files, directories, symlinks, mode, uid/gid, and extended attributes. Server-side encryption is optional, and data integrity is checked with MD5 hashes. An in-memory metadata cache holds attributes, and a local disk data cache sits underneath reads. Signatures can be v2 or v4, and the region is user-specified, which is what makes Amazon GovCloud reachable. The gap inside that subset is hard links. There is no hard link support, so any build step or backup tool that calls link() will not work as it would on a local file system.
An append rewrites the whole object through multi-part upload copy
Random writes and appends are listed as supported features, but the cost lands on the entire object. A random write or an append requires rewriting the whole object, and the project only makes that manageable by splitting the rewrite into multi-part upload copy requests. Large files therefore move through multi-part uploads rather than one request. A process that patches a few bytes near the front of a large file still requires rewriting the entire object. A long-running log that a service keeps open and appends to is the worst case, because each append requires rewriting the entire object. The object remains valid afterward because the native format is preserved, but validity is not the same as cheap, and a throughput budget built on local disk assumptions will be wrong.
Directory listing pays network latency and inotify only sees local writes
Two behaviours make a mounted bucket a poor fit for anything that inspects a tree continuously. First, metadata operations such as listing directories have poor performance due to network latency, so a recursive walk, a checksum pass, or a build tool that enumerates files pays a network round trip per directory rather than reading a local inode table. Second, inotify detects only local modifications, not external ones by other clients or tools. A writer that goes through the AWS CLI, another host with the same bucket mounted, or a server-side process changes the bucket without the watcher on this mount noticing anything. The practical consequence is that a silent watcher is not evidence that the directory is unchanged. Either re-list periodically, or treat the mount as read-mostly for anything that must be observed.
Renames are server-side copies with no atomicity and no client coordination
Renames are implemented as a server-side copy, and the project states plainly that there are no atomic renames of files or directories. A copy of a large object takes time, and a concurrent reader can observe the source name and the destination name at the same moment, with the copy only partly complete. There is also no coordination between multiple clients mounting the same bucket, so two mounts on two hosts can each rewrite the same key and the later write simply wins, with no lock, no version check, and no error surfaced to either side. Editor and job patterns that write a temporary file and then rename it over the original are the common trigger. On a non-atomic rename, a crash or a kill between the copy and the delete leaves both names behind in the bucket, and a re-run of the job can then pick up the leftover copy as if it were real input.
Non-Amazon endpoints need url and use_path_request_style, and can read stale data
Against anything other than Amazon S3, the mount has to be told where the endpoint is and how to address it. Specifying the URL and path-style requests is the documented path for a non-Amazon S3 implementation, and both settings reappear in the fstab form. The project points at S3Proxy for combining s3fs with Backblaze B2, EMC Atmos, Microsoft Azure, and OpenStack Swift buckets, and keeps a separate wiki page for other S3-based object stores. The behavioural difference to plan around is consistency. Non-AWS providers may have eventual consistency, so reads can temporarily yield stale data. AWS is the exception, having offered read-after-write consistency since Dec 2020. On a non-AWS backend, a read issued right after a write can return the previous object, which means retry loops, cache invalidation, and any build that verifies a file it just wrote all need to tolerate it.
Credentials come from a 600-mode passwd file, the environment, or the AWS credentials file
Three sources are recognized: the standard AWS credentials file stored in ${HOME}/.aws/credentials, a custom passwd file, and the AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, and AWS_SESSION_TOKEN environment variables. The custom passwd file defaults to ${HOME}/.passwd-s3fs, and /etc/passwd-s3fs is available as a system-wide alternative, with both needing owner-only permissions. Creating the per-user file, then making the first mount against an existing bucket, looks like this:
echo ACCESS_KEY_ID:SECRET_ACCESS_KEY > ${HOME}/.passwd-s3fs
chmod 600 ${HOME}/.passwd-s3fss3fs mybucket /path/to/mountpoint -o passwd_file=${HOME}/.passwd-s3fsThe key and the secret sit in plaintext on disk, so that 600 mode is the only thing standing between the bucket and anyone who can read your home directory or root. The environment variable route avoids the file but pushes the secret into the environment of every process you launch, which is a wider blast radius than it looks. For a machine with more than one person on it, decide deliberately which of the two you are using.
One package name per distro, two steps on macOS, and a separate Windows install
Packaging is not uniform, and the package names are not interchangeable across families. Debian 9 and Ubuntu 16.04 or newer use apt, Fedora 27 or newer uses dnf, and RHEL and CentOS 7 or newer need the EPEL release package added first. Amazon Linux takes amazon-linux-extras install epel before yum will find it. Arch uses pacman, Gentoo uses emerge, SUSE 12 and openSUSE 42.1 or newer use zypper, and FreeBSD uses pkg. macOS 10.12 and newer is a two-step path, macFUSE first and then the s3fs-mac formula from the gromgit/fuse tap, because the FUSE layer has to exist before s3fs can load. Windows has its own install, documented in COMPILATION.md rather than a package manager. For a mount that must survive a reboot, add the fstab line and check that the netfs service is enabled at boot. When something fails and you need to see the requests, the debug form is:
mybucket /path/to/mountpoint fuse.s3fs _netdev,allow_other 0 0s3fs mybucket /path/to/mountpoint -o passwd_file=${HOME}/.passwd-s3fs -o dbglevel=info -f -o curldbgEditorial conclusion
Use s3fs-fuse when one host needs POSIX-shaped reads and writes over a bucket it also touches with the AWS CLI, and accept that appends, renames, and recursive listings are network operations rather than local ones. Do not treat it as shared writable storage for several hosts, since there is no coordination between clients, inotify misses writes made elsewhere, and renames are not atomic. Before mounting against anything other than Amazon S3, confirm the consistency guarantees of that backend, and decide deliberately whether credentials live in a passwd file or in the environment.
Frequently asked questions
What is s3fs and what is it used for?
It is a FUSE-based file system that mounts an S3 bucket on Linux, macOS, or FreeBSD so you can operate files and directories in the bucket like a local file system, while keeping the native object format so other tools such as the AWS CLI can still read them.
what is s3fs fuse
s3fs-fuse is the C++ implementation that mounts a bucket through Filesystem in Userspace. It covers a large subset of POSIX including files, directories, symlinks, mode, uid/gid, and extended attributes, and it works against Amazon S3 and other S3-based object stores.
What are the differences between S3 and s3fs?
S3 is the object store; s3fs is the client that presents that bucket as a mounted directory. Because the two are not the same layer, S3 cannot offer the same performance or semantics as a local file system, and random writes or appends require rewriting the entire object.
s3fs fuse vs goofys
The project lists goofys as similar to s3fs but with better performance and less POSIX compatibility. s3fs is the option to pick when you need the wider POSIX surface; goofys is the one the project points at when throughput matters more than POSIX fidelity.
s3fs fuse alternatives
The project names several, each with a different shape: CSI for S3 as a Kubernetes CSI driver, s3backer to mount a bucket as a single file, S3Proxy to reach Backblaze B2, EMC Atmos, Microsoft Azure, and OpenStack Swift through s3fs, s3ql which uses its own object format, and YAS3FS which uses SNS to let multiple clients mount a bucket.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/s3fs-fuse-s3fs-fuse)Star history chart for your README
[](https://hysenlabs.com/projects/s3fs-fuse-s3fs-fuse)Was this useful?