Agent Squad: Classifier-Routed Multi-Agent Orchestration in Python, TypeScript and Swift
Flexible and powerful framework for managing multiple AI agents and handling complex conversations
At a glance
- What is it?
- Agent Squad routes each user turn to one of your specialized agents using a classifier that reads agent descriptions and conversation history. The Python and TypeScript runtimes run in the cloud; the newer Swift runtime runs the same orchestration model on device. The interesting part is the routing seam, and the interesting limitation is what happens when routing goes wrong.
- Who is it for?
- Adopt Agent Squad if you already have several distinct agents and want a shared routing and context layer rather than a single monolithic prompt, and if you are willing to own the classifier's prompt and the storage backend. Do not adopt it if you need deterministic dispatch, since the routing decision is made by a model reading agent descriptions.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Swift, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
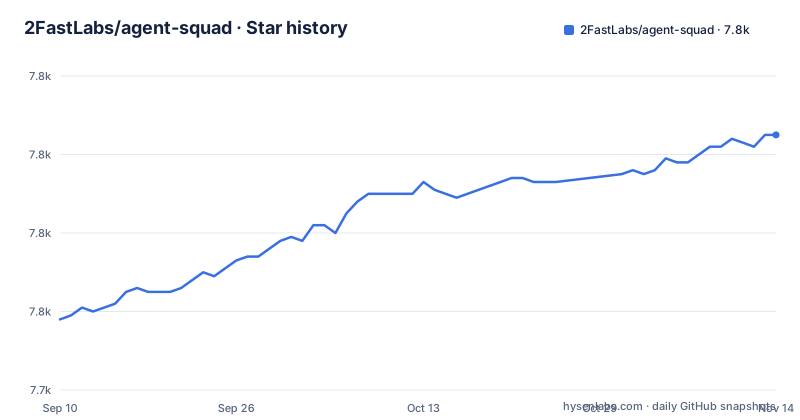
Star history
- 2FastLabs/agent-squad7,805 ★ · +47
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| 2FastLabs/agent-squad | 7.8k | 7.8k |
47 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The routing problem Agent Squad is built around
Most teams that end up with several agents do not start there. They start with one prompt, then add a second agent for a different domain, then a third, and suddenly the entry point has to decide which one should answer. Agent Squad addresses exactly that decision. The README describes the project as a framework that "routes each user query to the most suitable of your specialized agents and maintains conversation context across them." The unit of work is a turn: one user input, one selected agent, one stored exchange.
The audience is narrow but real. You need more than one agent with distinguishable responsibilities, you need the selection to depend on conversation context rather than a static keyword rule, and you want the same model available in more than one language runtime. A single-agent chatbot has no routing problem to solve, and a workflow with fixed steps has no need for a classifier at all. Agent Squad is for the middle case: several specialists, one entry point, ambiguous queries.
What actually happens between input and response
The README gives a four-step flow. User input is analyzed by a Classifier. The Classifier uses the agents' descriptions and the conversation history to select the best agent for the turn. The selected Agent processes the input, calling tools as needed. The Orchestrator saves the exchange and returns the response.
That ordering matters. Agent selection is not a lookup on a routing table. It is a model call that receives your agent descriptions as part of its input, which means the quality of your routing is a function of how you wrote those description strings. The example in the README uses a description like "Specializes in technology: software, hardware, AI, cybersecurity, cloud." Two agents whose descriptions both mention cloud will produce ambiguous routing, and there is no rule engine underneath to break the tie. The classifier is the tie-breaker.
The Orchestrator is the object you construct and hold. In TypeScript it is `new AgentSquad()`, in Python `AgentSquad()`, in Swift `Orchestrator(agents:store:)`. You register agents on it, call a route method, and receive either a stream or a final payload. Context is stored per user and per session, which is why every route call in the examples takes a `userId` and a `sessionId`.
The two patterns layered on top: SupervisorAgent and GroundedAgent
SupervisorAgent changes the shape of the graph. Instead of one classifier picking one agent, a lead agent coordinates a team "in parallel using an agent-as-tools architecture, maintaining shared context and delivering one coherent response." The README states it supports dynamic delegation of subtasks and works with all agent types, and that it can itself be registered in the classifier, which is how you build hierarchical teams. That last detail is the design decision worth noting: the supervisor is not a separate primitive, it is an agent that happens to hold other agents, so it composes with the routing layer rather than replacing it.
GroundedAgent is a different kind of intervention. It splits one answer across two models. A gatherer calls your tools and sees the raw results but "never speaks to the user." An isolated presenter then writes the reply "from the curated tool output alone". The stated intent is that answers cannot drift from your data. This is a cost trade: two model calls per response instead of one, in exchange for a narrower channel between tool output and user-visible text.
Installing and wiring it up in each runtime
TypeScript installs with `npm install agent-squad` and imports `AgentSquad` and `BedrockLLMAgent`. You add an agent with `orchestrator.addAgent(...)`, passing a name, a description and `streaming: true`, then call `orchestrator.routeRequest("What is AWS Lambda?", "user123", "session456")`. The response carries `metadata.agentName` so you can log which agent was chosen, and if `response.streaming` is true you iterate `response.output` as an async iterator.
Python installs with `pip install "agent-squad[aws]"`, and the README notes the alternatives `[anthropic]`, `[openai]` and `[all]`. The extra is how you select provider dependencies. The Python route call is `await orchestrator.route_request("What is AWS Lambda?", "user123", "session456", {}, True)`, with a positional dictionary and a boolean, and the stream yields `AgentStreamResponse` objects whose `.text` you print. Note the asymmetry: Python uses `agent_name` in metadata, TypeScript uses `agentName`.
Swift is added as a package dependency pointing at the repository with `branch: "main"` rather than a tagged version, which is worth flagging. You construct an `Agent` with a `ChatCompletionsClient(model: "gpt-4o-mini", apiKey: apiKey)`, build an `Orchestrator(agents:store:)` with `try DeviceChatStorage(userId: "u1")`, and consume `orchestrator.route(.text(...), userId:sessionId:)` as an async sequence of events, matching on `.textDelta(let token)`. The Swift runtime requires iOS 16+ or macOS 14+.
Where the classifier approach breaks down
The classifier is also the failure mode. Because routing is a model judgement over natural-language descriptions, it is probabilistic in a way a dispatch table is not. If a user asks something that legitimately spans two agents, the framework picks one and the other never sees the turn.
A second constraint is that routing depends on conversation history. That is a feature for follow-up questions and a liability for long sessions, because the same input can route differently at turn two and turn forty. If your agents are not truly interchangeable in quality, that variance is visible to users as inconsistent answers.
Third, the storage backend is a seam you must fill. The Python and TypeScript examples construct the orchestrator with no storage argument at all, and the Swift example passes an explicit `DeviceChatStorage(userId:)`. The README describes context management as a feature and extensibility of storage as a design goal. Treat persistence as something to verify rather than assume.
How it differs from LangGraph and similar graph frameworks
LangGraph, and graph-oriented orchestration libraries generally, ask you to declare nodes and edges: the control flow is authored, and the model operates inside the nodes you defined. Agent Squad inverts that. You register agents with descriptions and let a classifier decide the edge at runtime. The difference shows up when requirements change. In a graph framework, adding a specialist means adding a node and an edge condition. In Agent Squad it can mean adding an agent with a well-written description and letting the classifier learn to prefer it, which is less code and less certainty.
That trade cuts both ways. Graph frameworks give you a traceable path you can assert on in a test. Agent Squad gives you `metadata.agentName` after the fact, which tells you what was chosen but not why. If you need reproducible routing for compliance or debugging, the authored-graph approach fits better. If your agent set changes often and you would rather not maintain edge logic, the classifier approach costs less to keep current.
Maintenance, licensing and the repository move
The README carries a migration notice: the project was previously hosted at `awslabs/agent-squad`, is now maintained at `2fastlabs/agent-squad`, and was formerly named `multi-agent-orchestrator`. The README asks readers to update bookmarks, clone URLs and dependencies. If you have an existing dependency pinned to the old path, that rename is the first thing to check, because a moved repository affects both your package manager resolution and any CI configuration that references the old URL.
Release cadence is visible in the recent tags: `typescript_1.1.5` and `python_1.1.4` both on 2026-09-23, with `typescript_1.1.4` on 2026-07-14. The runtime versions are tracked separately, which means Python and TypeScript can drift even though the README claims they "maintain feature parity." There is no Swift version tag among the releases, so the Swift runtime appears to be consumed from `main` rather than a release, consistent with the `branch: "main"` dependency shown in the quick start.
The licence is Apache-2.0, which permits commercial use and modification and includes a patent grant. Apache-2.0 also requires that you preserve copyright and licence notices and state significant changes if you redistribute modified source. This is a description of the licence text, not legal advice; check the `LICENSE` file and your own obligations before shipping a modified fork.
Editorial conclusion
Adopt Agent Squad if you already have several distinct agents and want a shared routing and context layer rather than a single monolithic prompt, and if you are willing to own the classifier's prompt and the storage backend. Do not adopt it if you need deterministic dispatch, since the routing decision is made by a model reading agent descriptions. Before committing, verify two things in your own environment: how the classifier behaves when two agent descriptions overlap, and whether your chosen storage backend survives a process restart, because the Python and TypeScript quick-start examples pass no storage argument.
Frequently asked questions
what is agent squad
Agent Squad is a flexible, lightweight open-source framework for orchestrating multiple AI agents. It routes each user query to the most suitable specialised agent and maintains conversation context across them, with pre-built agents for Bedrock, Anthropic, OpenAI, Lex and Lambda, plus classifiers, storage and retrievers you can replace. It runs in Python 3.11+, TypeScript on Node.js, and a new Swift runtime on iOS 16+ and macOS 14+ that runs entirely on device.
what is aws agent squad
That was its earlier home. The README states that the project was previously hosted at awslabs/agent-squad and is now maintained at 2fastlabs/agent-squad, and that it was formerly named multi-agent-orchestrator, with a request to update bookmarks, clone URLs and dependencies. Its Amazon Bedrock heritage is still visible in the pre-built Bedrock agent and the Bedrock examples.
How do I install Agent Squad?
In TypeScript, `npm install agent-squad`. In Python, `pip install "agent-squad[aws]"`, or the [anthropic], [openai] or [all] extras, since the provider integrations are optional. In Swift, add the package to Package.swift or through Xcode's Add Package Dependencies with the URL https://github.com/2FastLabs/agent-squad on the main branch, which needs iOS 16 or macOS 14.
Does Agent Squad call an LLM to decide which agent handles a request?
Not necessarily. The default path analyses user input with a Classifier that uses the agents' descriptions and the conversation history. The JevClassifier component sends a typed choice question to Jev, TypeSafe AI's System One model, and returns the winning agent with a calibrated confidence, and it includes a built-in unknown option so an out-of-scope request returns no agent instead of a forced match.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/2fastlabs-agent-squad)Star history chart for your README
[](https://hysenlabs.com/projects/2fastlabs-agent-squad)Was this useful?